@TimFernholz at @TechCrunch breaks down how General Compute is building its inference cloud with SambaNova, and why faster, more efficient inference infrastructure is becoming critical for the next wave of AI. Featuring insights from General Compute CEO @FPuklowski and CTO
@sambanovaai
-
Responses API Now Supported Across SambaCloud, Stack, Managed
By
–
3/ The Responses API is now supported across: SambaCloud SambaStack SambaManaged Starting with:
• gpt-oss-120B
• MiniMax M2.5
• MiniMax M2.7 Built for Codex CLI, Cline, OpenCode, CrewAI, OpenClaw, and custom agent harnesses. -

SambaNova Responses API Accelerates High-Volume Agent Workflows
By
–
2/ Paired with SambaNova’s new Responses API, devs now get the fastest, most reliable foundation for high-volume agent workflows: • Large refactors
• Migrations
• Repo cleanup
• Multi-step coding tasks Because in agentic workflows, speed + cost determine whether an agent is -
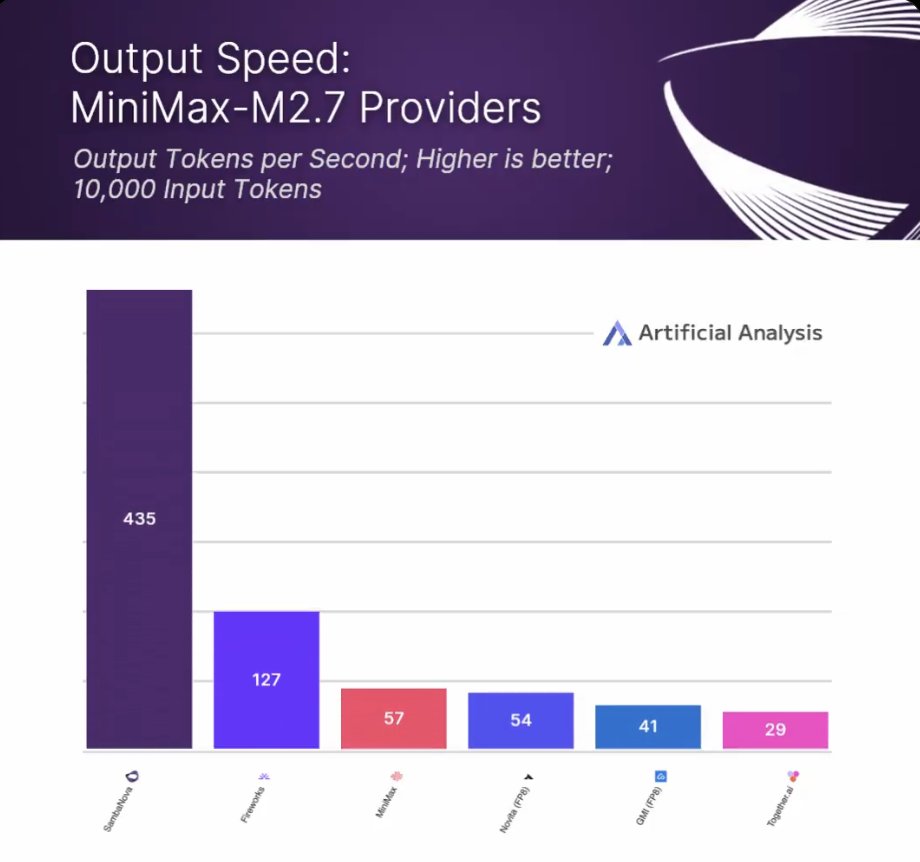
MiniMax M2.7 Live: 435 Tokens/Sec for Coding Agents
By
–
1/ @MiniMax_AI M2.7 is live on SambaCloud — running at 435 output tokens/sec, more than 3x the next-fastest provider (per @ArtificialAnlys
). Built for the way coding agents actually work: Reading files Running tests Fixing errors Looping until the job is done -
SambaNova Partners on Sovereign AI Cloud for Australia
By
–
Proud to partner with SCX as they deliver the world's 1st RDU-based sovereign AI cloud to Australia.
— SambaNova (@SambaNovaAI) 27 mai 2026
Designed for enterprises & government agencies that demand performance, compliance, and absolute data sovereignty.
Learn more ⬇️https://t.co/00T0eD3WtP pic.twitter.com/K27mYcuojJProud to partner with SCX as they deliver the world's 1st RDU-based sovereign AI cloud to Australia. Designed for enterprises & government agencies that demand performance, compliance, and absolute data sovereignty. Learn more https://
sambanova.ai/solutions/sout
herncrossai?utm_source=x&utm_medium=organic&utm_content=customer-partner
… -
Agentic AI and Premium Inference Speed Explained
By
–
Agentic AI changes what speed actually means.
— SambaNova (@SambaNovaAI) 27 mai 2026
Behind every response, multiple agents are reasoning and exchanging tokens in real time. Faster inference means faster outcomes.
🎧 @SumtiJairath explains why premium inference matters @dcdnews: https://t.co/9Wwc0vkssJ pic.twitter.com/4eKEfKJjyRAgentic AI changes what speed actually means. Behind every response, multiple agents are reasoning and exchanging tokens in real time. Faster inference means faster outcomes. @SumtiJairath explains why premium inference matters @dcdnews
: https://
podcasts.apple.com/us/podcast/epi
sode-102-the-training-to-inference-passageway/id1607349232?i=1000764784324
… -

Coding Agents as Tool-Using Systems with API Support
By
–
Coding agents are no longer chatbots, they’re tool-using systems that read files, run tests, patch code, and iterate until it works. That’s why we’re adding /v1/responses support across SambaCloud, SambaStack, and SambaManaged for faster agent workflows.
-
SambaHouse AI Demo Night: Sovereign Infrastructure Event
By
–
Still can't get over how much fun we had in Sydney.
— SambaNova (@SambaNovaAI) 26 mai 2026
SambaHouse AI Demo Night with @Equinix and @SCXAICloud brought together Australia’s AI community for demos, lightning talks, and conversations around the future of sovereign AI infrastructure. pic.twitter.com/RX42KWhJxeStill can't get over how much fun we had in Sydney. SambaHouse AI Demo Night with @Equinix and @SCXAICloud brought together Australia’s AI community for demos, lightning talks, and conversations around the future of sovereign AI infrastructure.
-
Heterogeneous Hardware Strategy for Enterprise AI Inference
By
–
Enterprises don’t need a single chip to handle all inference workloads.
— SambaNova (@SambaNovaAI) 26 mai 2026
The better approach is heterogeneous: GPUs for compute-heavy prefill, RDUs for fast decode, and CPUs for orchestration and integrations.
Right work, right hardware layer. That’s how you avoid tradeoffs. 🦾 pic.twitter.com/B1tqmROeQ2Enterprises don’t need a single chip to handle all inference workloads. The better approach is heterogeneous: GPUs for compute-heavy prefill, RDUs for fast decode, and CPUs for orchestration and integrations. Right work, right hardware layer. That’s how you avoid tradeoffs.
-
RDUs deliver high tokens per kilowatt-hour for AI inference
By
–
AI infrastructure doesn’t have to mean massive power draw.
— SambaNova (@SambaNovaAI) 22 mai 2026
Our RDUs deliver the highest tokens per kilowatt-hour, helping reduce deployments with ~10kW average power consumption.
More inference. Less energy. 🦾
Learn more: https://t.co/v6jPztJPFp pic.twitter.com/dUM5bB3T5kAI infrastructure doesn’t have to mean massive power draw. Our RDUs deliver the highest tokens per kilowatt-hour, helping reduce deployments with ~10kW average power consumption. More inference. Less energy. Learn more: https://
sambanova.ai/products/rdu-a
i-chips?utm_source=x&utm_medium=organic
…