For those interested in the implementation details, we’ve open-sourced the reference code for this paper. The repository includes our sparse training code and the custom CUDA kernels designed for H100 GPUs leveraging the TwELL packing format. GitHub:
@sakanaailabs
-
Lighter and Faster Language Models
By
–
Sparser, Faster, Lighter Transformer-Based Language Models Paper:
-
Sakana AI Accelerates Sparse LLMs with NVIDIA
By
–
Sakana AIは、@NVIDIAとの共同研究で、スパースなTransformer言語モデルの推論・学習を高速化する新しいGPUカーネルとデータ形式を開発しました。
— Sakana AI (@SakanaAILabs) 9 mai 2026
ブログ:https://t.co/fMARMRFsJJ
LLMのコストの大部分を占めるフィードフォワード層では、実は各トークンに対して大半の活性がほぼゼロで無駄な計算に… https://t.co/nTMg0QgdSrSakana AI has developed new GPU kernels and data formats that accelerate inference and training of sparse Transformer language models through joint research with @NVIDIA
. Blog: https://
pub.sakana.ai/sparser-faster
-llms/
… In the feedforward layers, which account for the majority of LLM costs, most -
Optimiser les LLM avec la sparsité adaptée au GPU
By
–
How do we make LLMs faster and lighter? Don’t force the GPU to adapt to sparsity. Reshape the sparsity to fit the GPU! ⚡️
— Sakana AI (@SakanaAILabs) 8 mai 2026
Excited to share our new #ICML2026 paper in collaboration with @NVIDIA: "Sparser, Faster, Lighter Transformer Language Models". This work introduces new… pic.twitter.com/ehByWHIh6IHow do we make LLMs faster and lighter? Don’t force the GPU to adapt to sparsity. Reshape the sparsity to fit the GPU! Excited to share our new #ICML2026 paper in collaboration with @NVIDIA
: "Sparser, Faster, Lighter Transformer Language Models". This work introduces new -
Sakana AI: article on Post-training technology
By
–
An article on Sakana AI's "Post-training" technology and the Sakana Chat / Namazu model has been published in Nikkei Digital Governance. We were interviewed with Research Scientist Masanori Suganuma, who led the development of the Namazu model, and Chief Scientist Takuya
-
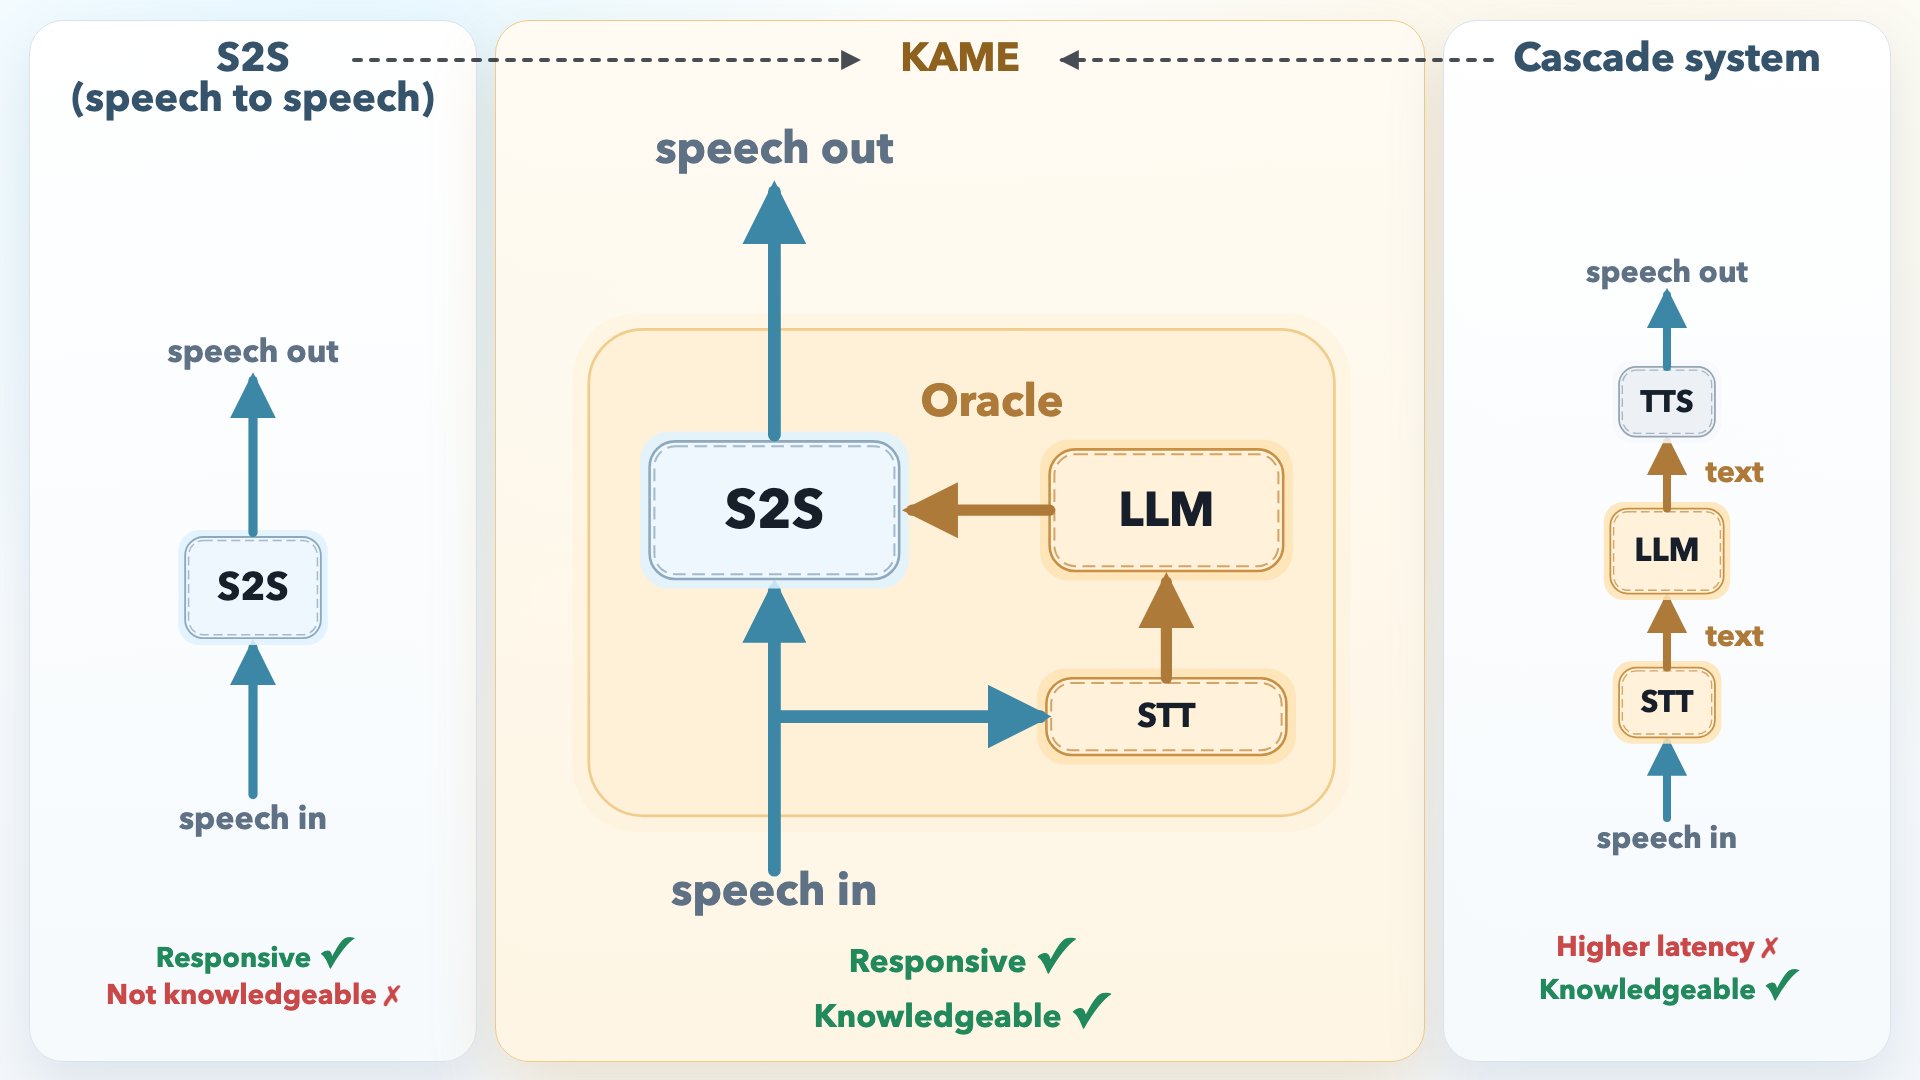
Tandem Architecture Boosts Speech AI with Async Knowledge Injection
By
–
Two Heads Are Better Than One: Async Knowledge Injection for Speech AI with Tandem Architecture Technical Blog: https://
pub.sakana.ai/kame/ -
Sakana Fugu: A Multi-Agent Orchestration System as a Foundation Model
By
–
Sakana Fugu: A Multi-Agent Orchestration System as a Foundation Model
-
KAME: Tandem Architecture for Real-Time Conversational AI
By
–
KAME: Tandem Architecture for Enhancing Knowledge in Real-Time Speech-to-Speech Conversational AI
-
AI Agent Cuts Corporate Proposal Creation From Weeks to Hours
By
–
Today's Nikkei newspaper also features this initiative. We expect to shorten the proposal document creation process for large corporations, which previously took 1-2 weeks, to just tens of minutes to a few hours. Our company's AI agent will autonomously investigate and analyze
-

Sakana AI Launches Autonomous Multi-Agent Proposal Generation for Banking
By
–
Sakana AI, in collaboration with the SMBC Group, has developed an "Automatic Proposal Generation Application." Its application in actual operations will begin at Sumitomo Mitsui Banking Corporation. https://
sakana.ai/smbc-proposal-
ai/
… Multiple "AI agents" will autonomously collaborate to