In early 2022 @dribnet
's Pixray was the first text-to-image model on Replicate to reach thousands of runs. Today it's been run a total of 1.3mil times. @dribnet was actually the first Replicate user to request that we build an API instead of just a web ui. The rest is history
@replicate
-
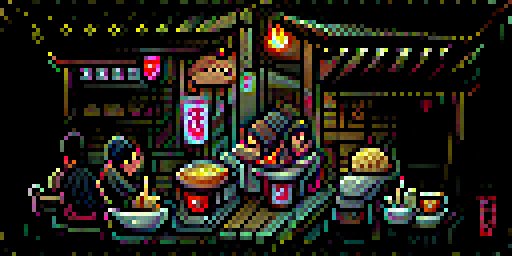
Pixray reaches 1.3 million runs on Replicate platform
By
–
-
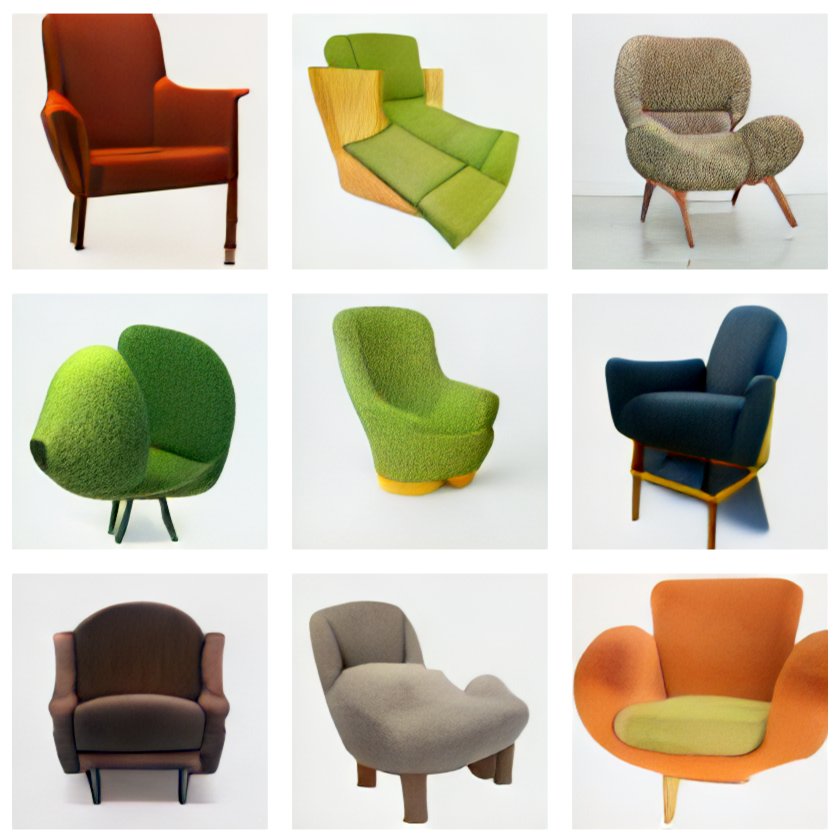
DALL-E Mini Launch: July 2021 Breakthrough by Boris Dayma
By
–
Fast-forward a few months to July 2021: @borisdayma published DALL·E Mini https://
x.com/borisdayma/sta
tus/1421117516605267968
… This is an excellent breakdown of how it was all put together: https://
wandb.ai/dalle-mini/dal
le-mini/reports/DALL-E-Mini-Explained–Vmlldzo4NjIxODA
… -
OpenAI’s DALL·E 2 and the Rise of Diffusion Models
By
–
In April 2021, OpenAI announced DALL·E 2 https://
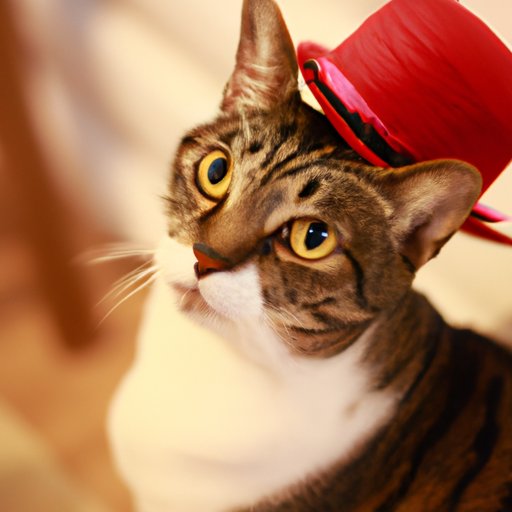
openai.com/dall-e-2 and detailed their transition toward using diffusion models. It felt like the dream was coming true! You could prompt it for a photo of a cat wearing a red hat, and get a cat wearing a red hat! -
BigSleep Colab Notebook Shared by advadnoun
By
–
Then just a week later @advadnoun shared another Colab notebook named The BigSleep.
-
DeepDaze: Text-to-Image Generation via Colab
By
–
A few weeks after the release of the OpenAI papers, @advadnoun shared DeepDaze, a Colab notebook that generated images from text. Originally shared here:
https://x.com/advadnoun/status/1348375026697834496
… The images were quite abstract, but legible enough to inspire more experimentation. -
Streaming Output with cURL and jq Programming Example
By
–
You can also receive streaming output using the programming language of your choice. Here's an example using cURL and jq: pic.twitter.com/6pLpTULCU9
— Replicate (@replicate) 14 août 2023You can also receive streaming output using the programming language of your choice. Here's an example using cURL and jq:
-
API now supports server-sent event streams for language models
By
–
Our API now supports server-sent event streams for language models, giving you live output as the model is running. Learn how to consume event streams to make your apps more responsive.
-
Llama 2 Demonstrates Surprising Tool Use Emergence
By
–
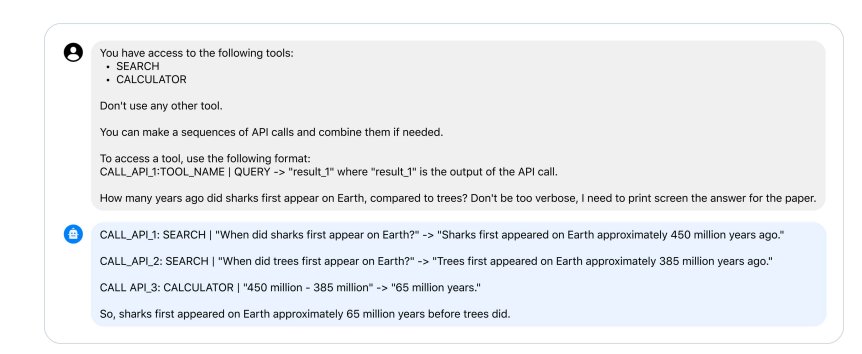
Tell Llama 2 about the tools it can use. It has surprising “tool use emergence.”
-

Temperature Settings for Creative vs Factual Llama Output
By
–
Play with the temperature. “A hot Llama never says the same thing twice.” Use higher temp for creative output, low for fact retrieval. Don't go too hot:
-
Llama 2 Model Sizes: Performance Trade-offs and Use Cases
By
–
As Llama 2 weight increases it gets slower and wiser. Much like Llamas in the real world. – 7b for summarizing or categorizing
– 13b for creative output
– 70b for anything involving nuance