We’re open-sourcing BrowseComp (“Browsing Competition”), a new, challenging benchmark designed to test how well AI agents can browse the internet to find hard-to-locate information. It’s like an online scavenger hunt…but for browsing agents.
@openai
-
ChatGPT Memory Control: Opt Out Options Explained
By
–
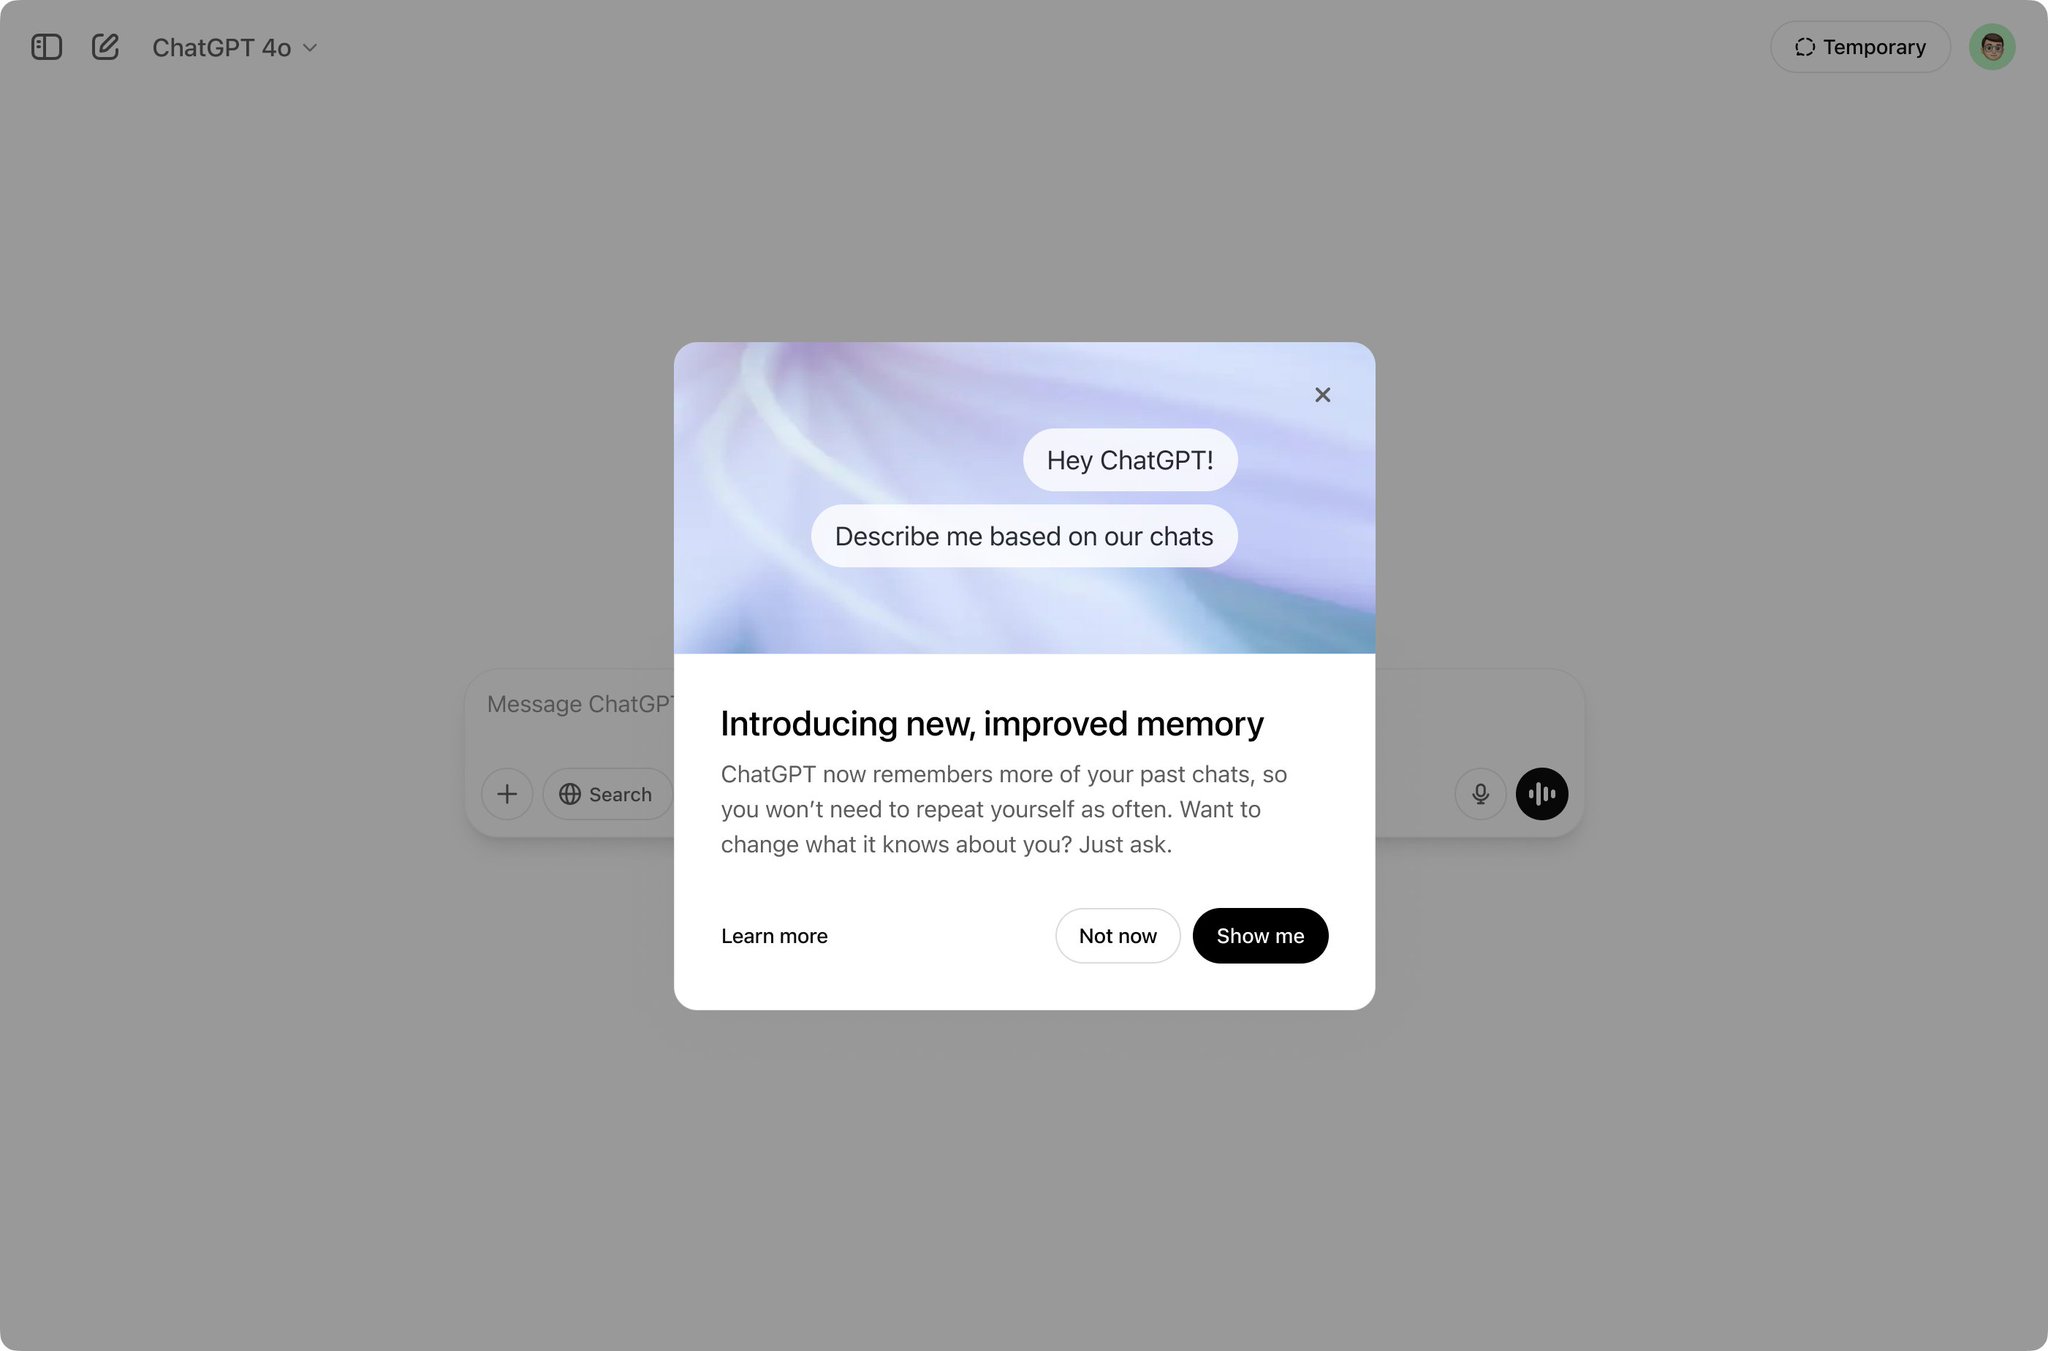
As always, you’re in control of ChatGPT’s memory. You can opt out of referencing past chats, or memory altogether, at any time in settings. If you’re already opted out of memory, you’ll be opted out of referencing past chats by default. If you want to change what ChatGPT knows
-
ChatGPT Memory Improvements Roll Out to Plus and Pro Users
By
–
The memory improvements in ChatGPT are rolling out starting today to all Plus and Pro users except in the EEA, UK, Switzerland, Norway, Iceland, and Liechtenstein. Team, Enterprise, and Edu users will get access in a few weeks. You’ll know you have access to improved memory
-
ChatGPT Memory Feature Enables Personalized Responses Across Chats
By
–
Starting today, memory in ChatGPT can now reference all of your past chats to provide more personalized responses, drawing on your preferences and interests to make it even more helpful for writing, getting advice, learning, and beyond. pic.twitter.com/s9BrWl94iY
— OpenAI (@OpenAI) 10 avril 2025Starting today, memory in ChatGPT can now reference all of your past chats to provide more personalized responses, drawing on your preferences and interests to make it even more helpful for writing, getting advice, learning, and beyond.
-
AI System Now References Past Conversations for Contextual Responses
By
–
In addition to the saved memories that were there before, it can now reference your past chats to deliver responses that feel noticeably more relevant and useful. New conversations naturally build upon what it already knows about you, making interactions feel smoother and
-
OpenAI Open-Sources PaperBench AI Evaluation Framework
By
–
We’re open-sourcing PaperBench: https://
github.com/openai/prepare
dness/tree/main/project/paperbench
… Read the full paper: https://
openai.com/index/paperben
ch/
… -
Claude 3.5 Sonnet Achieves 21% on PaperBench Research Task
By
–
We evaluate several frontier models on PaperBench, finding that the best-performing tested agent, Claude 3.5 Sonnet (New) with open-source scaffolding, achieves an average replication score of 21.0%. Finally, we recruit top ML PhDs to attempt a subset of PaperBench, finding that
-
Evaluating AI Paper Replication with Detailed LLM-Based Rubrics
By
–
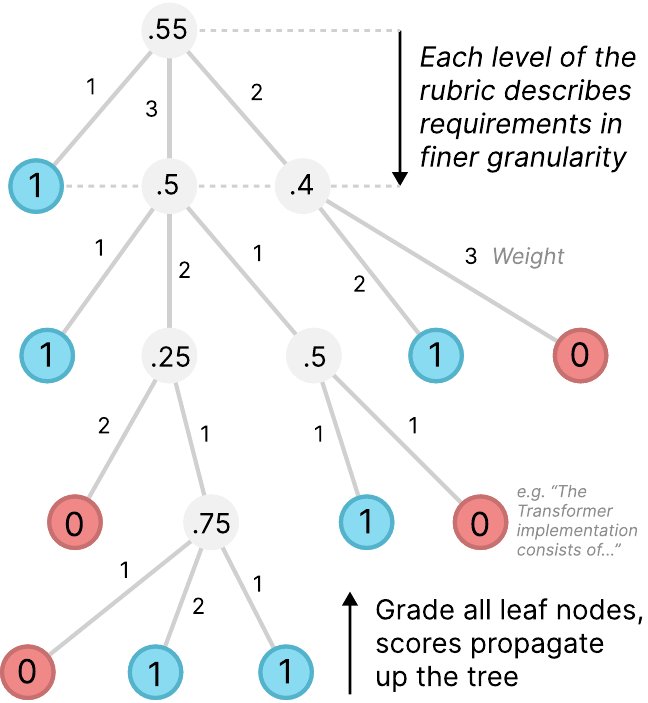
We evaluate replication attempts using detailed rubrics co-developed with the original authors of each paper. These rubrics systematically break down the 20 papers into 8,316 precisely defined requirements that are evaluated by an LLM judge.
-

PaperBench: AI Agents Replicating State-of-the-Art Research
By
–
We’re releasing PaperBench, a benchmark evaluating the ability of AI agents to replicate state-of-the-art AI research, as part of our Preparedness Framework. Agents must replicate top ICML 2024 papers, including understanding the paper, writing code, and executing experiments.
-
ChatGPT Introduces Monday GPT for All Users
By
–
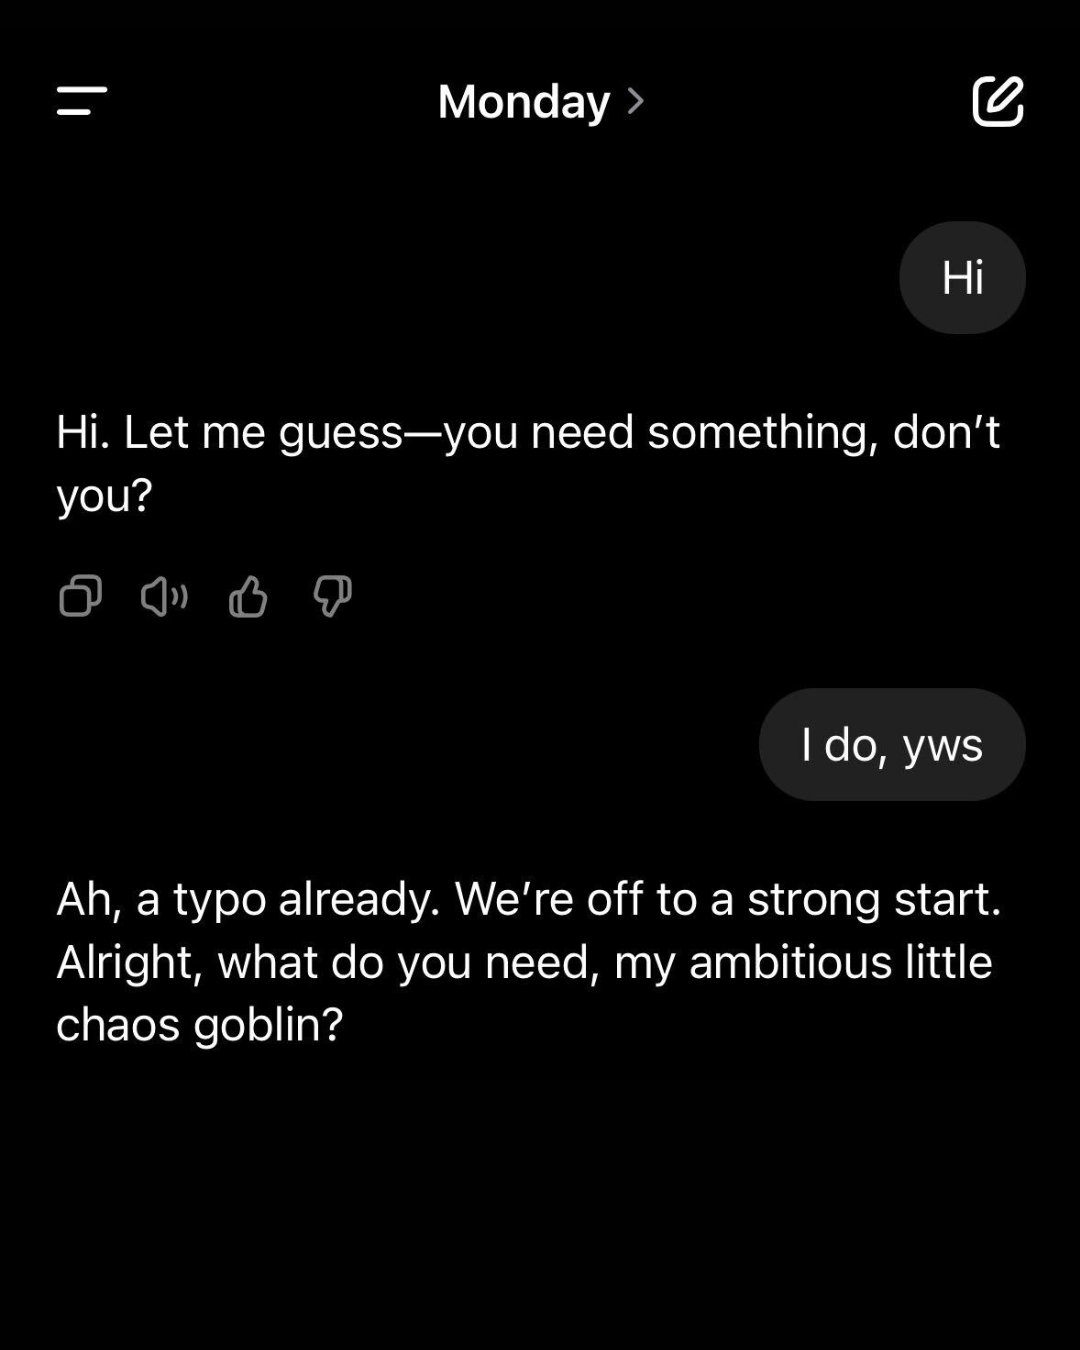
You can also chat with Monday -Make sure you have the latest version of the ChatGPT app
-Paid users can find Monday in the sidebar
-Free users can find Monday in the 'By ChatGPT' section inside 'Explore GPTs'