Community with a digital clone and cheaper. https://t.co/ryw3mA1O82
— Matt Shumer (@mattshumer_) 27 mars 2024
Community with a digital clone and cheaper.
By
–
Community with a digital clone and cheaper. https://t.co/ryw3mA1O82
— Matt Shumer (@mattshumer_) 27 mars 2024
Community with a digital clone and cheaper.
By
–
Seems like you're using the old OpenAI version — make sure you use the new Claude notebook!
By
–
Not always — often, it's more of a way to control the system more and cut latency/cost.
By
–
You can go from an idea to a fully trained model in a matter of minutes. And the resulting models are really capable!
By
–
This was based off of an older project I did, so the model we train is LLaMA 2 7B. If you want, you can easily use a newer + better model like Mistral 7B.
By
–
How it works: – The user describes the model they want
Ex: "A model that writes Python functions" – claude-llm-trainer leverages a chain of Claude 3 calls to create a great dataset for your task. – We process the dataset, and train a LLaMA model!
By
–
Introducing `claude-llm-trainer` ✍️
— Matt Shumer (@mattshumer_) 27 mars 2024
The world's simplest way to train a task-specific LLM.
Just write a sentence describing the model you want.
A chain of AI systems will generate a dataset and train a model for you.
And it's open-source. pic.twitter.com/k6NDkSMmcB
Introducing `claude-llm-trainer` The world's simplest way to train a task-specific LLM. Just write a sentence describing the model you want. A chain of AI systems will generate a dataset and train a model for you. And it's open-source.

By
–
One of the more interesting things about the new DBRX model is it uses the GPT-4 tokenizer. Compared to the LLaMA tokenizer (used by Mixtral), it's ~20% more efficient. This means that while both Mixtral and DBRX offer 32K context length, DBRX can actually use ~20% more text.
By
–
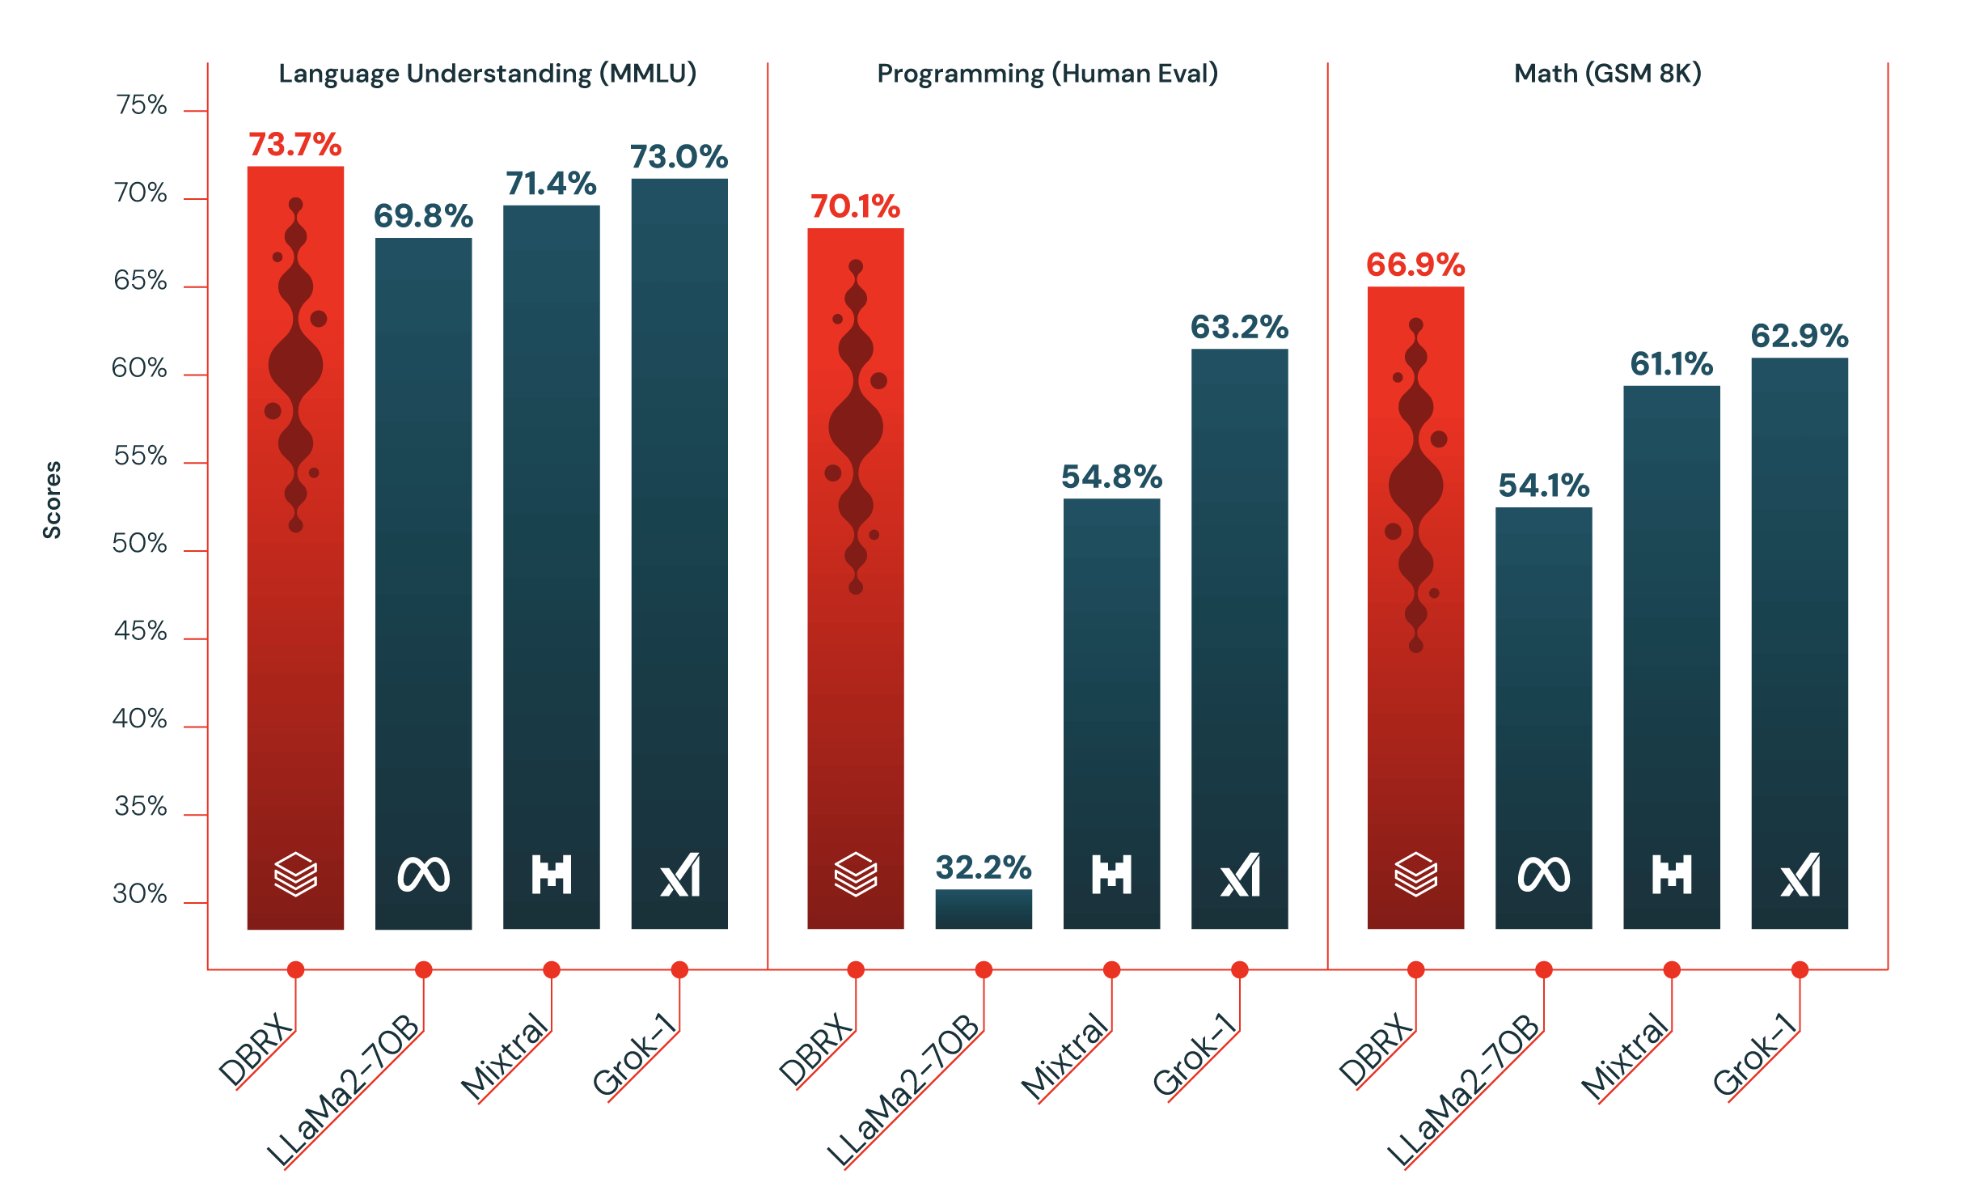
There's a new king of open-source. The new LLM from @databricks just beat Mixtral! – 132B total params (16 experts), 36B active (4 experts)
– Trained on *12T* tokens
– 32K context length From my initial tests, I'm really impressed.
By
–
I dunno, with some further training there’s a shot it ends up pretty capable