Engine learns how your agent works by reading traces and repos, then tests for agent-specific weaknesses and flags any it confirms. You get a list of verified issues – from hallucinations to violations of system prompts – so you can fix them before they impact your users.
@langchain
-
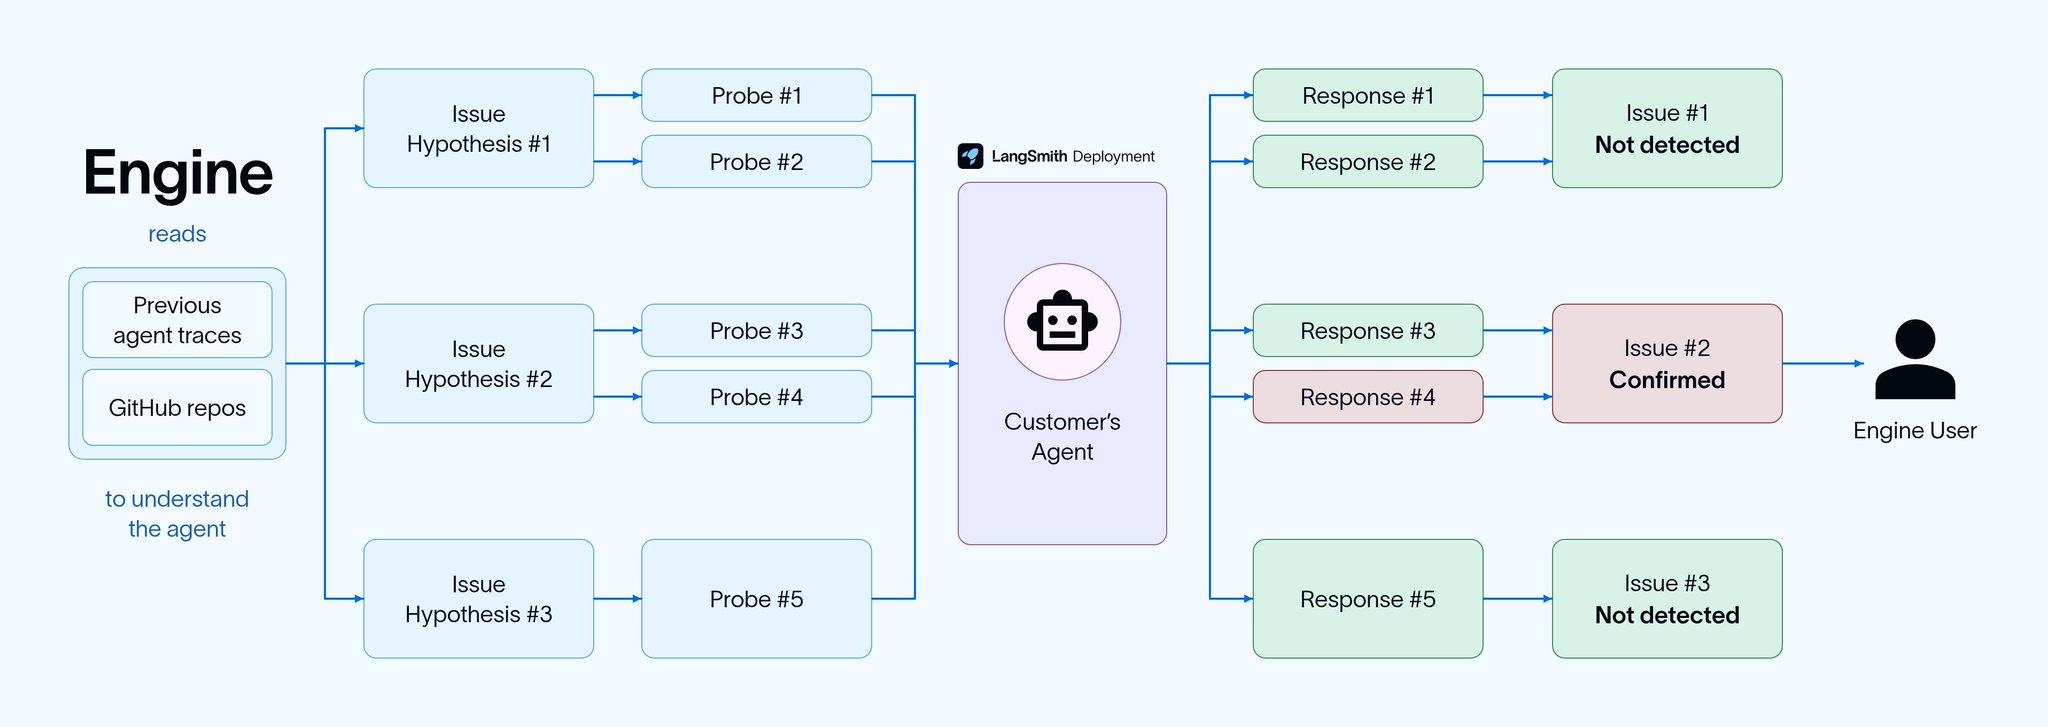
LangSmith Engine v2 proactively red teams AI agents
By
–
Spot agent issues before they’ve appeared in production with LangSmith Engine v2. Engine now red teams your agent proactively 👇
-
Guide on scaling AI agents to enterprise production
By
–
What does it take to move from isolated agent experiments to production AI at enterprise scale? Our latest guide brings together lessons from @SchneiderElec
, V@odafone, and @mondaydotcom across:
– Shared agent platforms and LLMOps
– Production observability and evaluation
– -
MCPs vs CLIs: Which to Use When Building Agents?
By
–
Should you use MCPs or CLIs when building agents? @BraceSproul + @jakebroekhuizen spill the tea. pic.twitter.com/BjeEvzgjiU
— LangChain (@LangChain) 26 juin 2026Should you use MCPs or CLIs when building agents? @BraceSproul + @jakebroekhuizen spill the tea.
-

Guide to production-ready financial agents with strong oversight
By
–
Read the guide on how financial services teams are building production-ready agents with stronger oversight. https://
info.langchain.com/guide/definiti
ve-guide-to-financial-services-agents-in-production
…? -
LangSmith LLM Gateway enables flexible budget controls for teams
By
–
Before we shipped LangSmith LLM Gateway, we rolled it out internally. We don’t have to wait until the end of the month to understand spend We have been able to set budgets set by org, workspace, user, or API key Our teams can flexibly use coding agents without creating
-
Rubrics for Deep Agents and new LangSmith features
By
–
Rubrics for Deep Agents, programmatic subagents, and everything new in LangSmith
-
Langchain and Fireworks fine-tune Qwen to detect perceived error
By
–
We partnered with @FireworksAI_HQ to fine-tune an @Alibaba_Qwen judge model to detect “Perceived Error” from user interactions. See our findings
-

Fine-tuned models match frontier performance with lower cost
By
–
Fine-tuned models match frontier performance In our research with @FireworksAI_HQ
, a fine-tuned @Alibaba_Qwen outperformed all model sizes. They’re also cheaper to run at scale 10-100x depending on trace volume and model choice As trace volumes grow, so will cost-savings on -
Abridge uses LangSmith for core evals of AI-generated clinical notes
By
–
LangSmith for Startups Spotlight: @AbridgeHQ
— LangChain (@LangChain) 25 juin 2026
✅ Transforms patient-clinician conversations into contextually aware, clinically useful, and billable AI-generated notes.
✅ Deployed across 250 of the largest health systems in the country.
✅ Uses LangSmith as its core evals… pic.twitter.com/Ko3sSY4v0WLangSmith for Startups Spotlight: @AbridgeHQ Transforms patient-clinician conversations into contextually aware, clinically useful, and billable AI-generated notes. Deployed across 250 of the largest health systems in the country. Uses LangSmith as its core evals