people that don't know love to criticize Meta on twitter, since it's guaranteed engagement but you have to realize that releasing open weights puts you in a vulnerable position. it's scary, and hard. that's why no one else is doing it google's gemma is open, but small. AI2's
@jxmnop
-
Foundational Machine Learning Research Paper Highly Recommended
By
–
overall a really entertaining read, highly recommend. here's a link http://
jmlr.org/papers/volume3
/bengio03a/bengio03a.pdf
… -
Neural Networks Outperform N-gram Models in Mixture Architecture
By
–
their neural networks worked better than any other methods and the bigger ones are better although at this scale, mixing with ngrams still helps a lot. they use a "mixture of models" – similar to today's MoEs, but the experts are different ngram models, plus one neural network
-
CPU vs GPU: Computing Power Gap in AI Training
By
–
they trained on a cluster of 64 1.2 GHz CPUs i did some math and think this is roughly 1 teraflop. a single H100 GPU gives you 4,000 teraflops lol
-
Model Training Scale: From 800K to 25 Trillion Tokens
By
–
their model is trained on 800K words, which is around 2.5M tokens. remember today's models are up to ~25T tokens (10^7 more, or 10 million million times) (they trained another model on 15M words)
-
Compact Language Model Architecture: 12M Parameters vs LLAMA 4
By
–
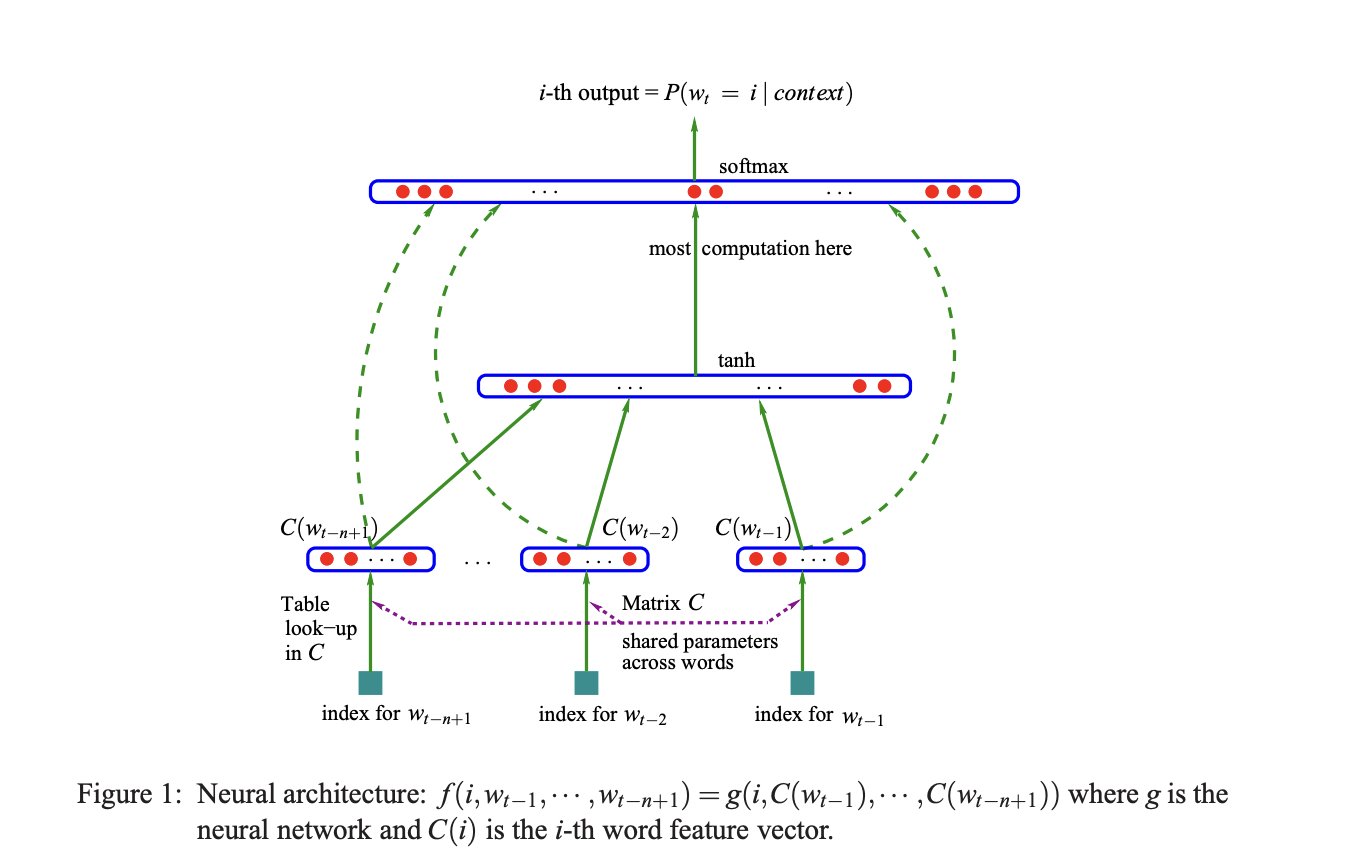
they use word embeddings + single-layer MLPs vocab size is 18K, context window is 6 words, hidden dimension is 60, word embedding have 100 dimensions their model has approx |V|(nm + h) = 17,964 × (6 × 100 + 60) = 12 million parameters about 200K times smaller than LLAMA 4…
-
Hogwild Parallel Processing on CPU: Engineering Techniques
By
–
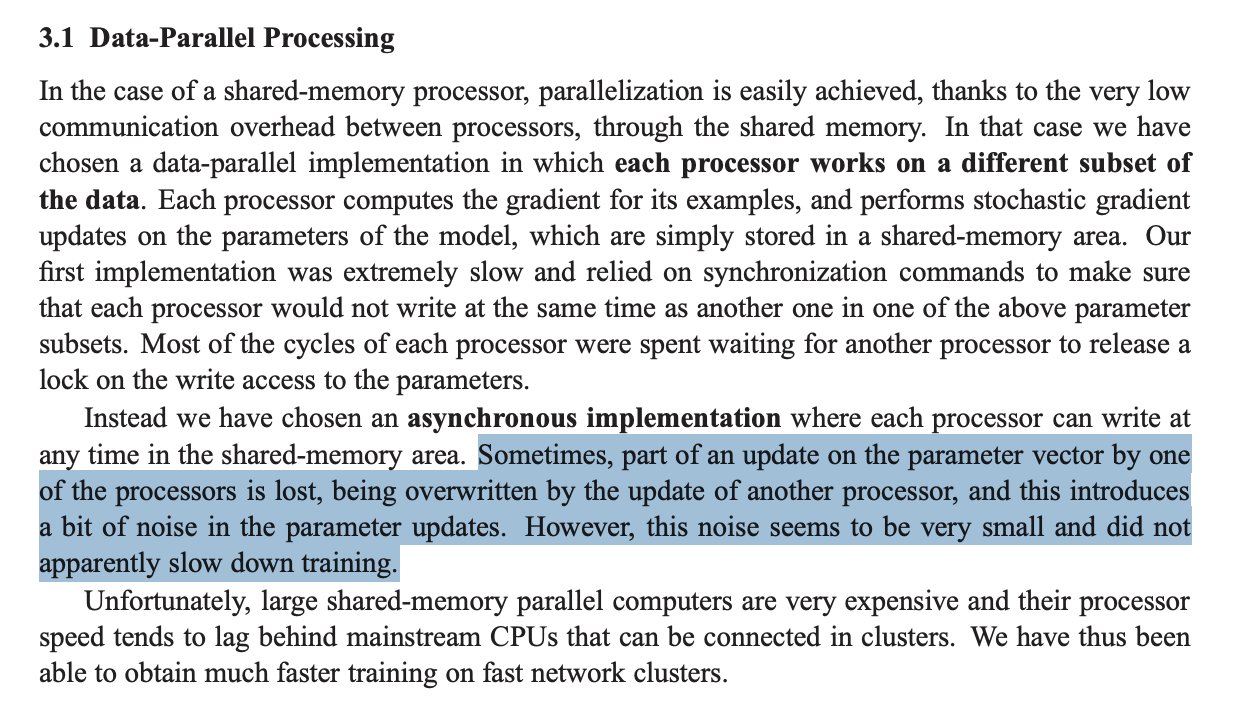
they do parallel processing (on CPU). i think this is now a well-known technique called Hogwild that wasn't formally developed until 2011. engineering this sounds pretty fun:
-
Neural Networks Training History: The 2003 Montreal Paper
By
–
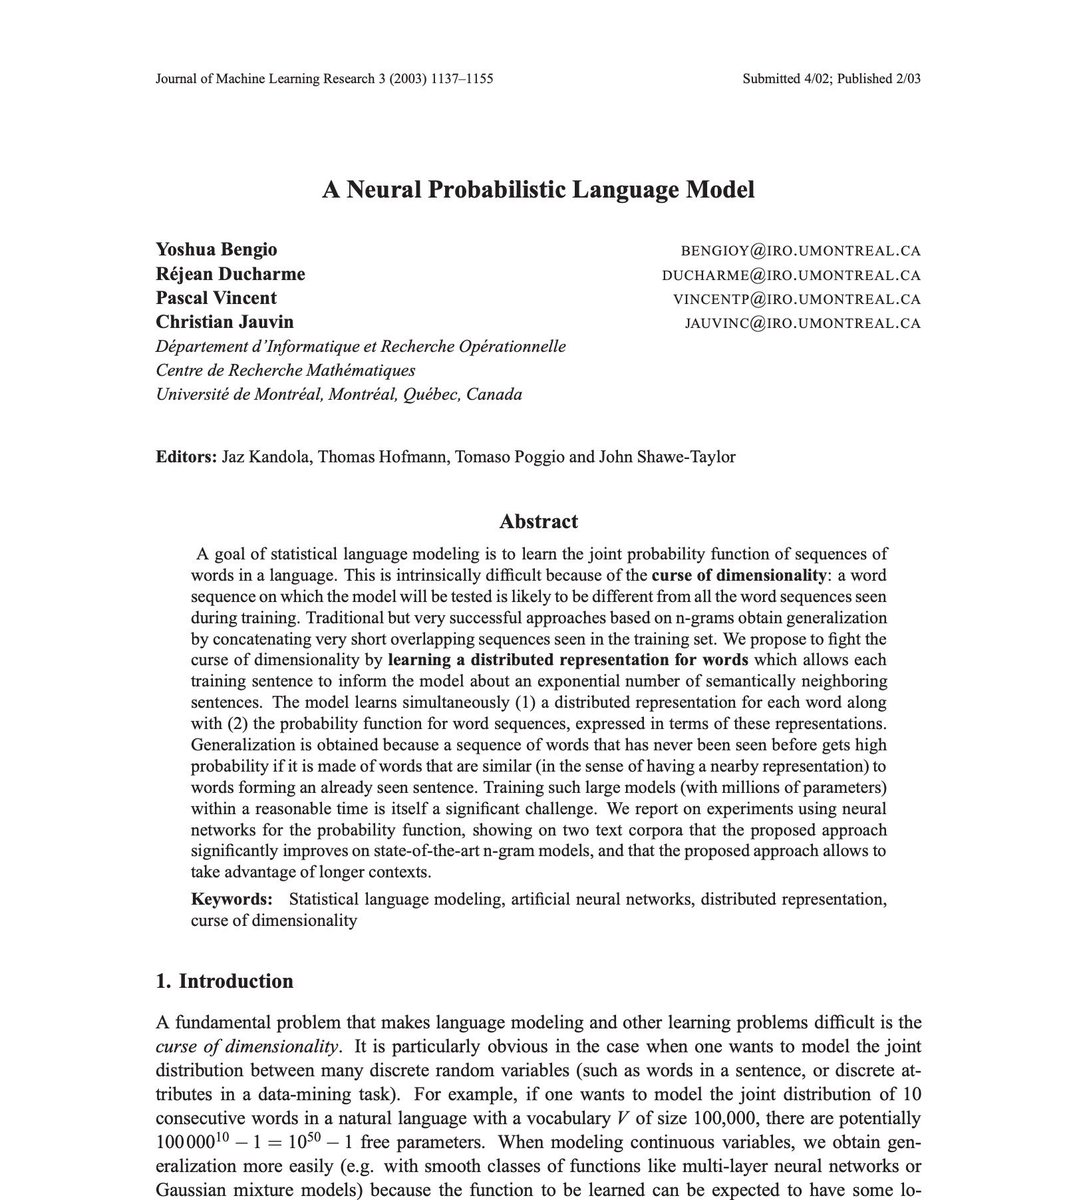
did you know people have been training neural networks on text since 2003? everyone talks about Attention Is All You Need. but this is the real paper that got our field started. it was in 2003, in montreal. i read it, and it was even more forward-thinking than i expected:
-
Smart Actors Adapt Strategy or Hide Knowledge
By
–
i believe you, but they are also very smart, and likely to change course in the face of evidence. so i'd guess either (a) they will start trying something new or (b) they know something that we don't