Starlink @huggingface connection is quite fast
@julien_c
-
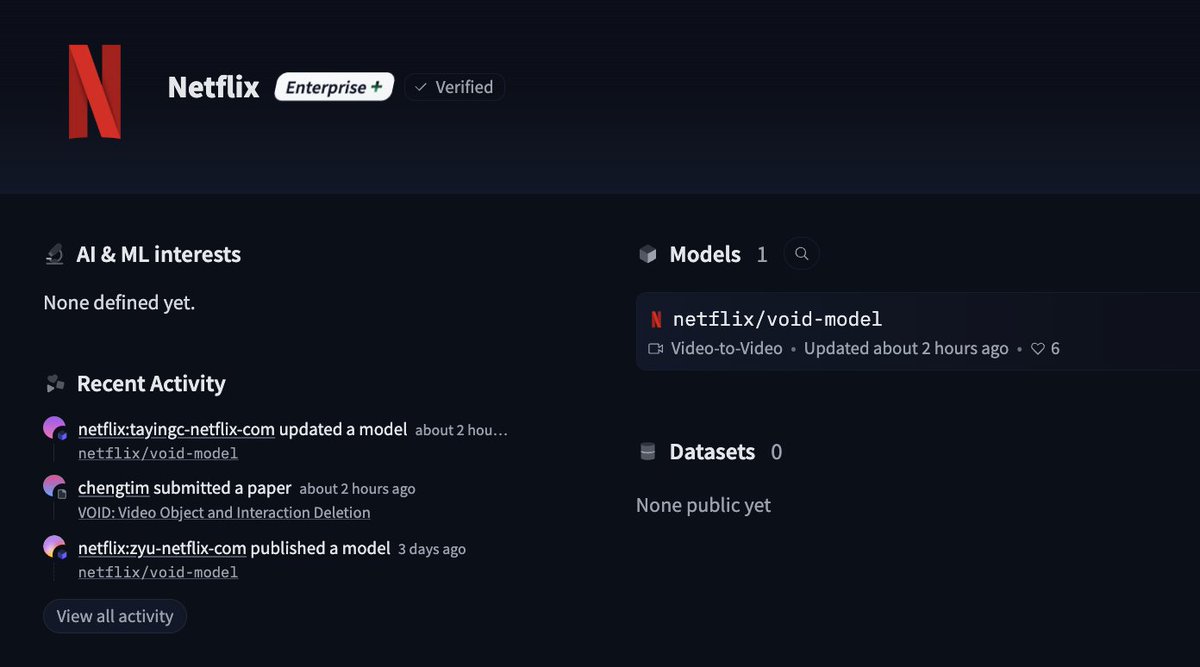
Netflix releases first public model on Hugging Face
By
–
Welcome to the movement @netflix Sylvain Filoni (@fffiloni) Netflix just dropped their first public model on @huggingface 👀 — https://nitter.net/fffiloni/status/2039992515604983994#m
-
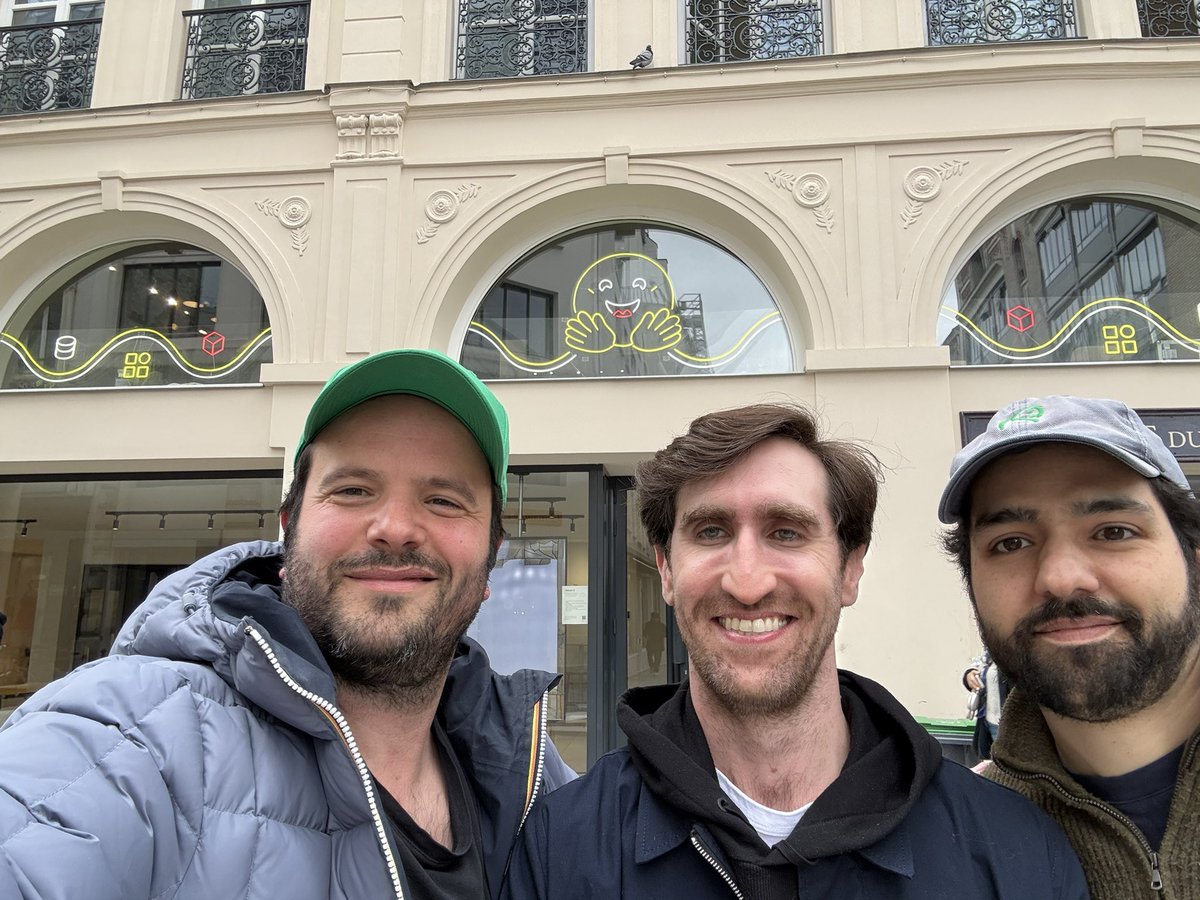
Gemma 4 Launch Celebration with Local AI Community Leaders
By
–
To celebrate the Gemma 4 launch we held a small impromptu get together with @yagilb from @lmstudio fame Feat. @victormustar from @huggingface Go Local AI!! ❤️❤️
-
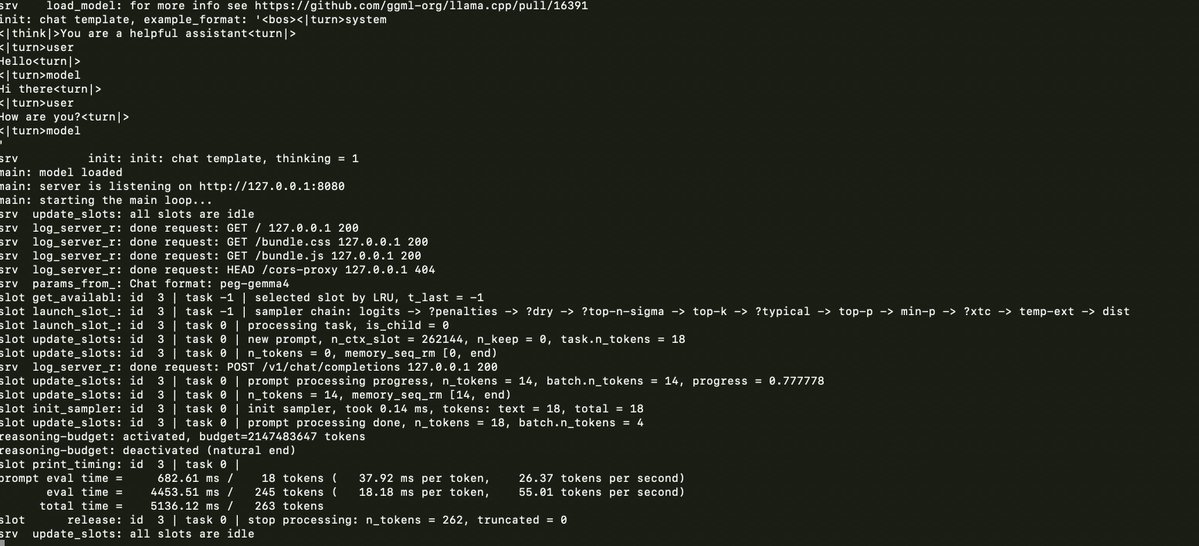
Running Llama.cpp and Gemma 4 on M1 Max MacBook Pro
By
–
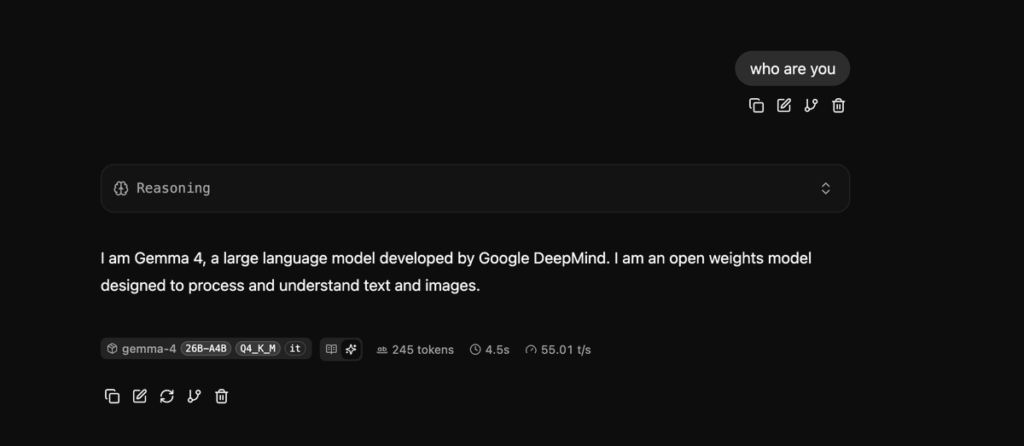
llama.cpp and gemma 4 on a 6 year old Macbook Pro M1 Max
-
Llama 31B Performance in llama-server: User Experience
By
–
Did you try the 31B in llama-server? Worked well for me
-
Julien calls OpenAI acquiring Disney in 2027
By
–
in 2027 OAI will acquire Disney i'm calling it John Coogan (@johncoogan) TBPN has been acquired by OpenAI! The show is staying the same and we’ll continue to go live at 11am pacific every weekday. This is a full circle moment for me as I’ve worked with @sama for well over a decade. He funded my first company in 2013. Then helped us fix a serious logjam during a critical funding round a few years later. When I took my second company through YC, he was president at the time, and then when I joined Founders Fund, the first deal I saw in motion was the post-ChatGPT round in late 2022. And as we started growing TBPN last year, he was the very first lab lead to join the show. Thank you to everyone that has been a part of TBPN until now. The last year has been the most fun and rewarding part of my career and we’re excited to have more resources than ever going forward. — https://nitter.net/johncoogan/status/2039756493621542915#m
-
llama.cpp achieves 300 tokens/second on Mac Studio M2 Ultra
By
–
Let me demonstrate the true power of llama.cpp:
— Georgi Gerganov (@ggerganov) 2 avril 2026
– Running on Mac Studio M2 Ultra (3 years old)
– Gemma 4 26B A4B Q8_0 (full quality)
– Built-in WebUI (ships with llama.cpp)
– MCP support out of the box (web-search, HF, github, etc.)
– Prompt speculative decoding
The result:… pic.twitter.com/B3EnpbWJdeLet me demonstrate the true power of llama.cpp: – Running on Mac Studio M2 Ultra (3 years old) – Gemma 4 26B A4B Q8_0 (full quality) – Built-in WebUI (ships with llama.cpp) – MCP support out of the box (web-search, HF, github, etc.) – Prompt speculative decoding The result: 300t/s (realtime video)
-
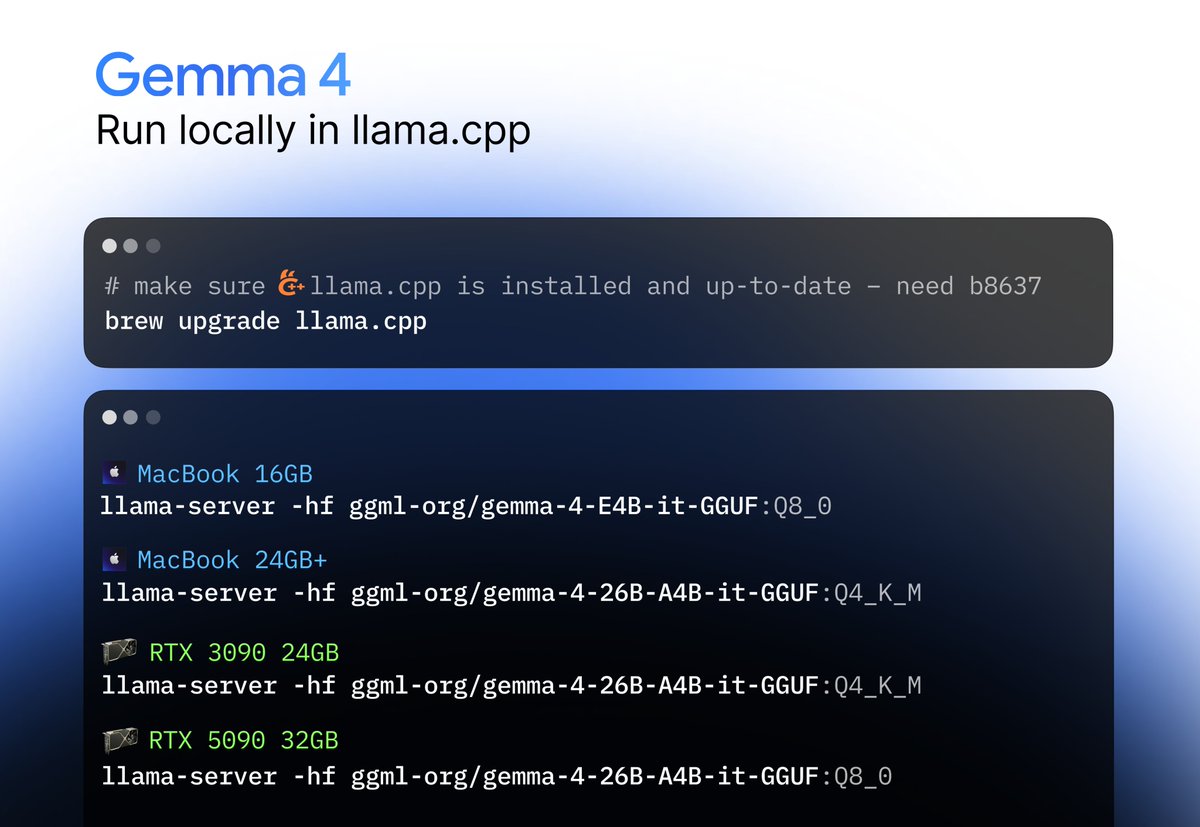
Installing and Running Llama.cpp with Gemma Model
By
–
Just do this: brew install llama.cpp –HEAD Then; llama-server -hf ggml-org/gemma-4-26B-A4B-it-GGUF:Q4_K_M
-
Executive Resigns Over Intern’s Mistake at Hugging Face
By
–
We all make mistakes, but still 😡😡 Leandro von Werra (@lvwerra) An intern on my team made a mistake. As a consequence I am resigning effective immediately. Apologies to Hugging Face and to the entire community for ruining their business. — https://nitter.net/lvwerra/status/2039349647001473358#m
-
Hugging Face Infrastructure Team Handles Massive Download Scale
By
–
makes me think… the Hugging Face infra team is one of the best in the world right now. The scale is now truly insane, randoms are spamming 1T×10 downloads all day lol