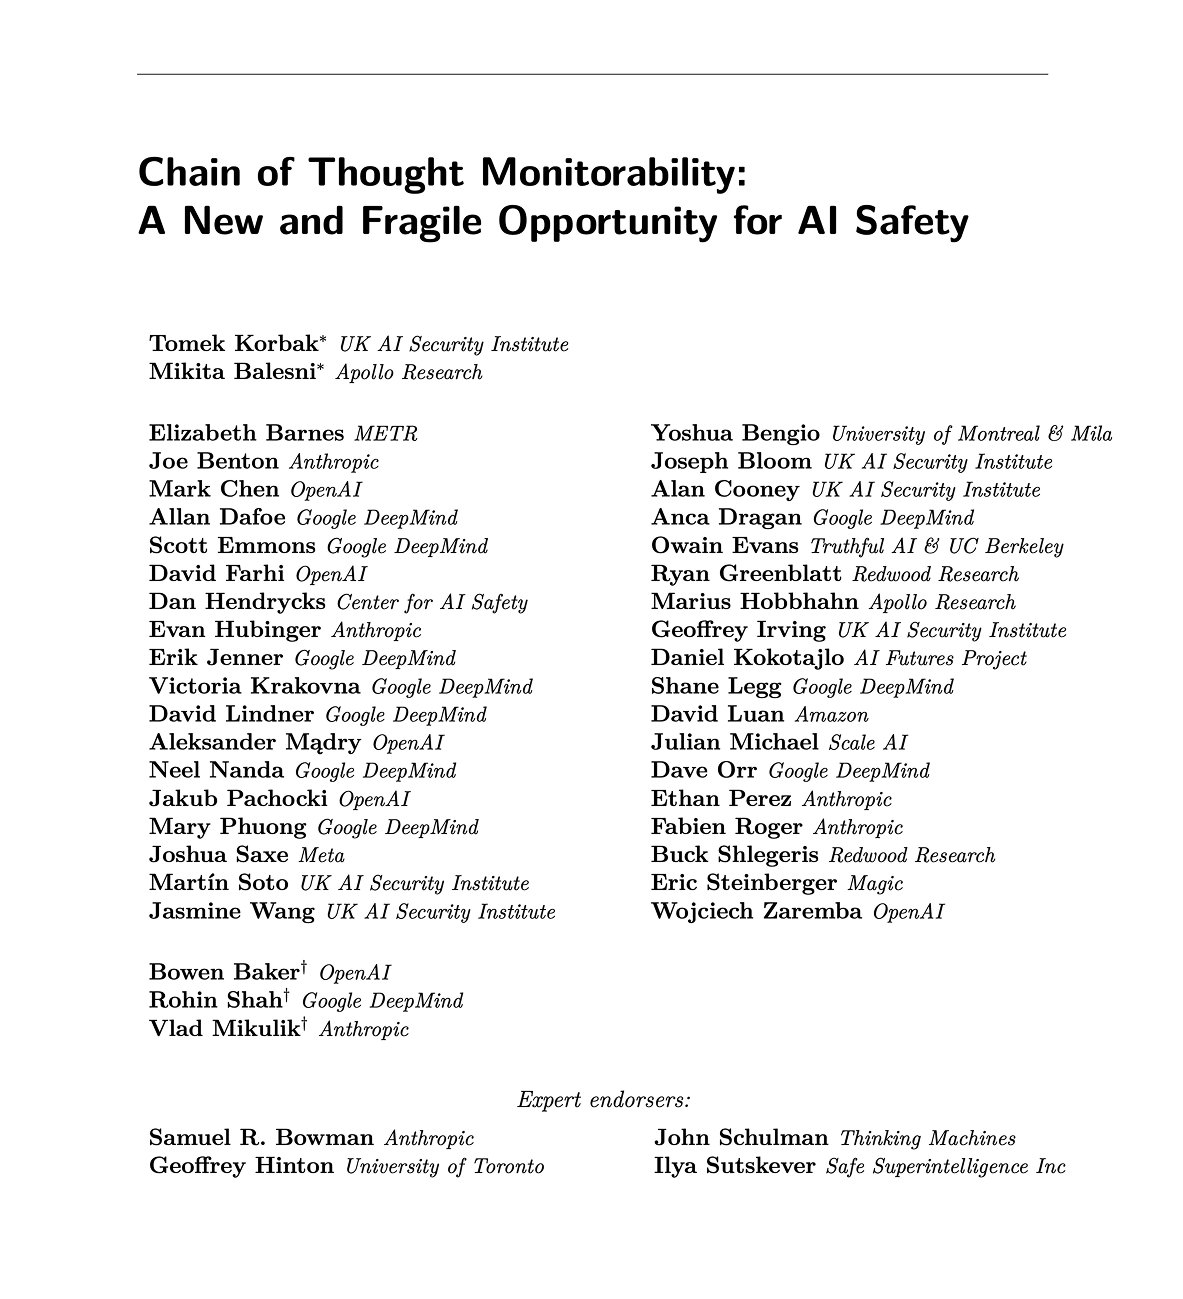
1) It's not common to have "expert endorsers" either. Although there is some prior history of authors trying to provide the reader a sense of how experts assess the content. In these cases, the norm is to provide responses received from all contacted experts.
@jeremyphoward
-
Jeremy Howard shares Anthropic research on similar topics
By
–
Similar thoughts about this paper here from Anthropic's @janleike
: -
Chain of Thought Training Faithfulness and Interpretability Questioned
By
–
They've only listed those that agree I told them "I don't agree. I don't think CoT has much of a useful role to play. It's only really showing something that appears to be a meaningful trace because they're trained to appear that way, but actually they're not faithful at all"
-
Publishing Research: Present Both Supporting and Critical Feedback
By
–
IMO if you're going to go to the trouble to get feedback about your paper before publishing (which is a great idea!) you should publish *both* sides. Just listing prominent supporters gives the wrong impression.
-
Anthropic’s Jan Leike shares similar thoughts on research paper
By
–
Similar thoughts about this paper here from Anthropic's @janleike BTW:
-
Publishing Research: Include Both Supporting and Opposing Perspectives
By
–
IMO if you're going to go to the trouble to get feedback about your paper before publishing (which is a great idea!) you should publish *both* sides. Just listed prominent supporters gives the wrong impression.
-
System Prompts as Prioritized Instructions Framework
By
–
So really I think "follows prioritised instructions" might be a better framing, where the system prompt is taken as the highest priority instruction?
-
Redefining AI Misuse Requests: Safety vs Developer Intent
By
–
"requests for misuse" only makes sense, to me, if defined as "request to do a thing that the system prompt asks not to do". This is not necessarily harmful or unsafe. It's just not what the developer wanted.
-
User Intent Framing and AI Safety Safeguards Context
By
–
I think I disagree with your framing. "The user is intentionally asking for something that could lead to harmful outcomes if no safeguards are in place" could refer to no prompts, or all prompts, depending on context.
-
Model Controllability: Essential for Safe AI Deployment
By
–
For someone wanting to deploy a model, what they really need to know is how controllable it is, so that they can make it behave in the way they require.