


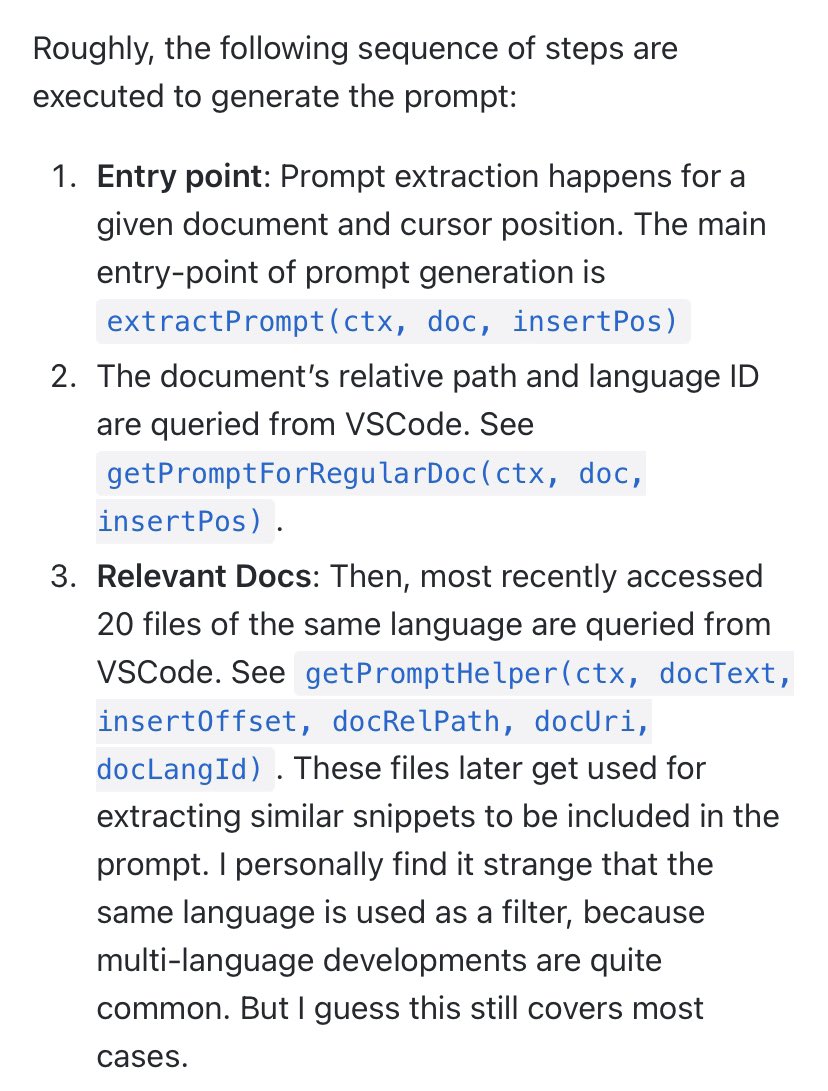
When you hit tab in GitHub Copilot, you’re FITM-completing a prompt of your file with an implicit comment header added, and it takes pages to describe what might be in that header. That’s prompt engineering. That’s a moat.
By
–
When you hit tab in GitHub Copilot, you’re FITM-completing a prompt of your file with an implicit comment header added, and it takes pages to describe what might be in that header. That’s prompt engineering. That’s a moat.
By
–
See @parth007_96
’s brilliant notes on reverse-engineering GitHub Copilot here: https://
thakkarparth007.github.io/copilot-explor
er/posts/copilot-internals
…
By
–
I increasingly see GPT‑3/LLM prompts as assembly code, not as human interface. We shouldn’t be writing prompts, but prompt compilers. A template string is not a moat.
By
–
Expanding on a (private account) reply: Its response reliably contains the current date, information it could not learn from its training data, which ends 2021-09. In all other contexts it reliably pretends not to know the current date and will guess incorrectly if asked.
By
–
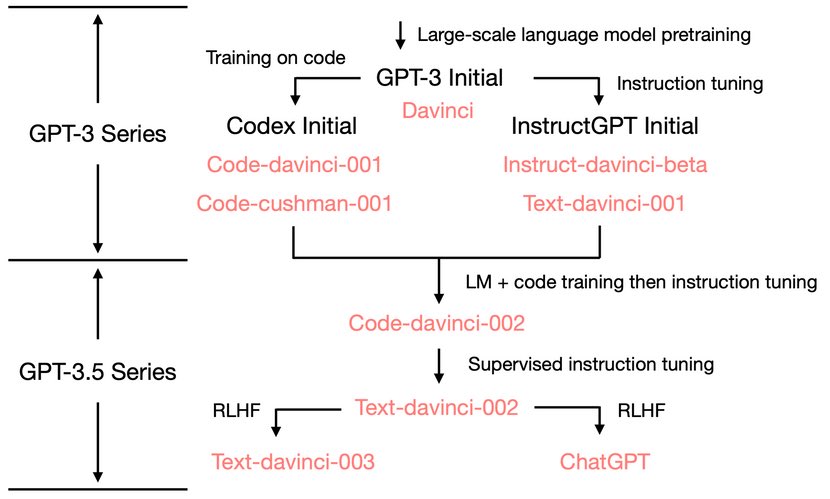
It’s from here: https://
yaofu.notion.site/How-does-GPT-O
btain-its-Ability-Tracing-Emergent-Abilities-of-Language-Models-to-their-Sources-b9a57ac0fcf74f30a1ab9e3e36fa1dc1
…
By
–
Note while models tuned this way are aligned to follow the intent of prose instruction, the barrier to their misuse declines as well, presenting new safety issues.
By
–
Later, reinforcement learning was used to automate the task of human evaluation as well. This yielded a endless fountain of tuning data that could be produced entirely by machine — a process known as RLHF.
By
–
By tuning the model on its own generations, filtered to those deemed perfect by human evaluators, greater volumes of data could be used, yielding a more intelligent and obedient model.
By
–
Early attempts at instruction tuning relied entirely on demonstrations from humans. This made the model easier to prompt, but the approach was limited by the inherent difficulty of manufacturing new humans.
By
–
Instruction tuning / RLHF is technically a Human Instrumentality Project, merging the preferences of countless humans to form an oversized, living amalgam of our will. We then hand control of it to a random, socially awkward kid and hope for the best.