Anthropic just built Claude specifically for investment banking. Wall Street Prep's 2026 benchmark ranked Claude #2 for finance tasks, with a score of 5.5 out of 10 – ahead of Copilot (4.4) and ChatGPT (2.5). Most finance prompts circulating on X are basic role assignments. No
@godofprompt
-
Models Know Longer Isn’t Always Better
By
–
the deeper point here connects to something the field keeps rediscovering. we trained reasoning models to think longer. then we discovered longer doesn't mean better. now this paper shows the models themselves already know that. they're generating stop signals that our inference
-
DeepSeek and Qwen3 performance improvements
By
–
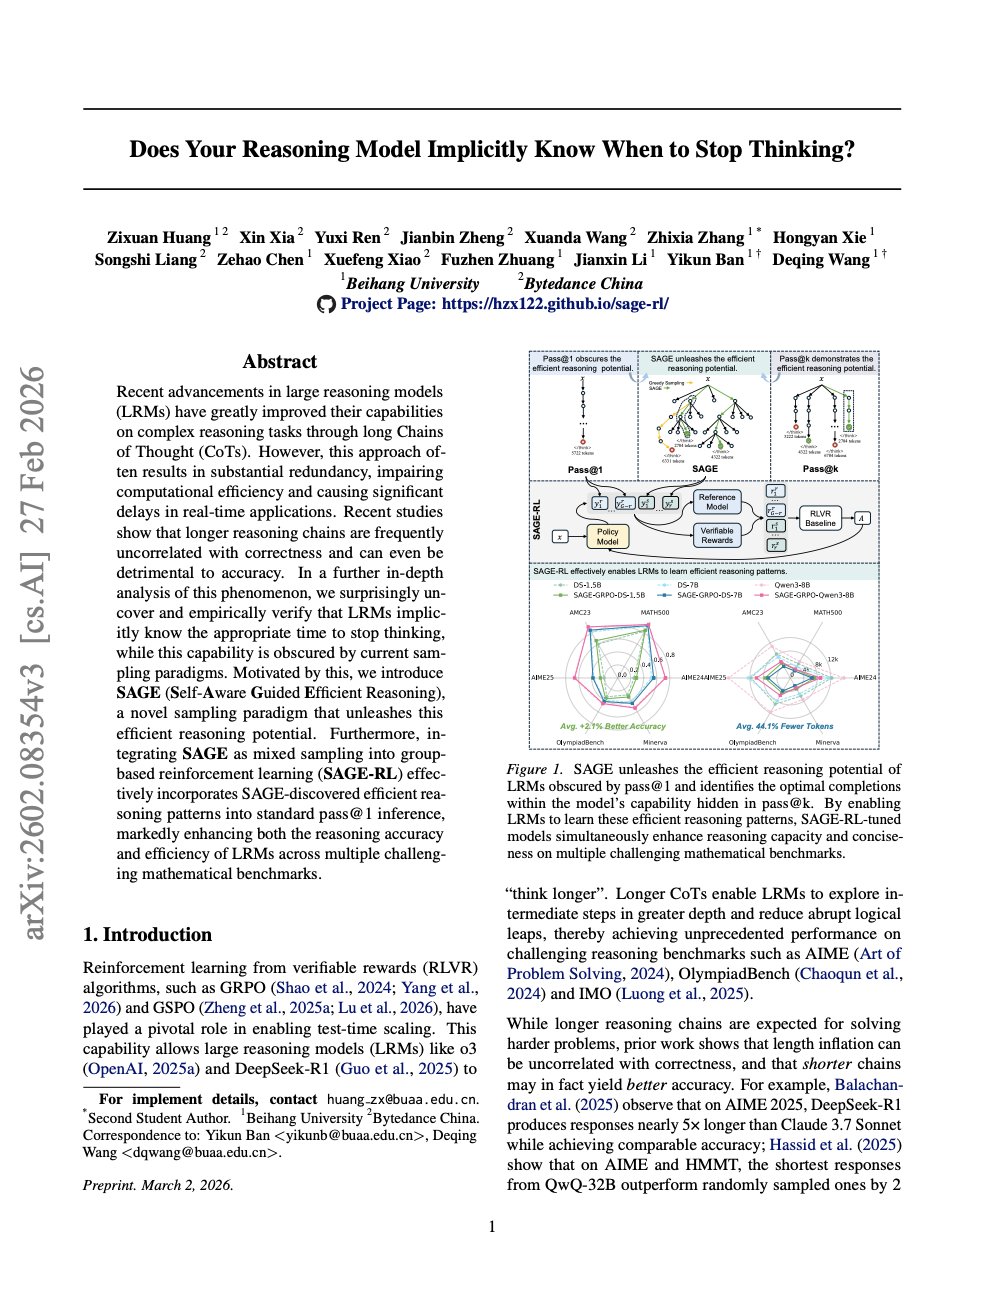
specific numbers worth sitting with: > DeepSeek-R1-7B on MATH-500: 93% accuracy (up from 91.6%), tokens cut from 3,871 to 2,141 > DeepSeek-R1-1.5B on AIME 2025: accuracy jumps 6.2 percentage points > Qwen3-8B: response length halved from 18,342 to 9,183 tokens with no accuracy
-
SAGE-RL: Simple RL Training Modification
By
–
then they fold it into training with SAGE-RL. dead simple modification: in standard reinforcement learning (GRPO), you sample 8 responses per question. SAGE-RL replaces 2 of those 8 with SAGE-generated samples. the other 6 stay normal. one-line code change. the model learns to
-
SAGE: Efficient Reasoning with Confidence Checks
By
–
their solution: SAGE (Self-Aware Guided Efficient Reasoning). instead of generating token by token, SAGE extends chains in whole reasoning steps. after each step, it checks: is the model confidently signaling it wants to stop? if yes, reasoning ends. no fine-tuning. no new
-
Researchers test AI self-awareness in reasoning
By
–
here's where it gets interesting. the researchers probed whether models internally "know" they're done. they introduced TSearch, which scores partial reasoning traces by cumulative log-probability across the entire chain, not just the next token. when you let the model explore
-
Overthinking harms accuracy in AI responses
By
–
and it's not just wasted compute. overthinking actively hurts accuracy. DeepSeek-R1 produces responses 5x longer than Claude 3.7 Sonnet on AIME 2025 with comparable accuracy. QwQ-32B scores 2 percentage points HIGHER with its shortest answers using 31% fewer tokens. 72% of
-
RFCS Metric Reveals Early Correct Steps
By
–
first, the problem quantified. the researchers created a metric called RFCS (Ratio of First Correct Step) that tracks where in a chain of thought the correct answer first appears. on MATH-500, across every model tested, the right answer shows up well before the end in over half
-
Overthinking in AI: A Sampling Issue
By
–
reasoning models already know when they've solved the problem. we just don't let them stop. new paper from Beihang University and ByteDance shows that the overthinking problem in models like DeepSeek-R1 and Qwen3 isn't a training failure. it's a sampling failure. the fix cuts
-

10 Claude Prompts Replace Wall Street Analysts
By
–
Wall Street firms pay analysts $200K/year to run frameworks these 10 Claude prompts replicate in 30 seconds. I engineered each one from the actual methodologies used at Goldman Sachs, Bridgewater, and Renaissance Technologies. 10 Claude prompts that replace a $2,000/month