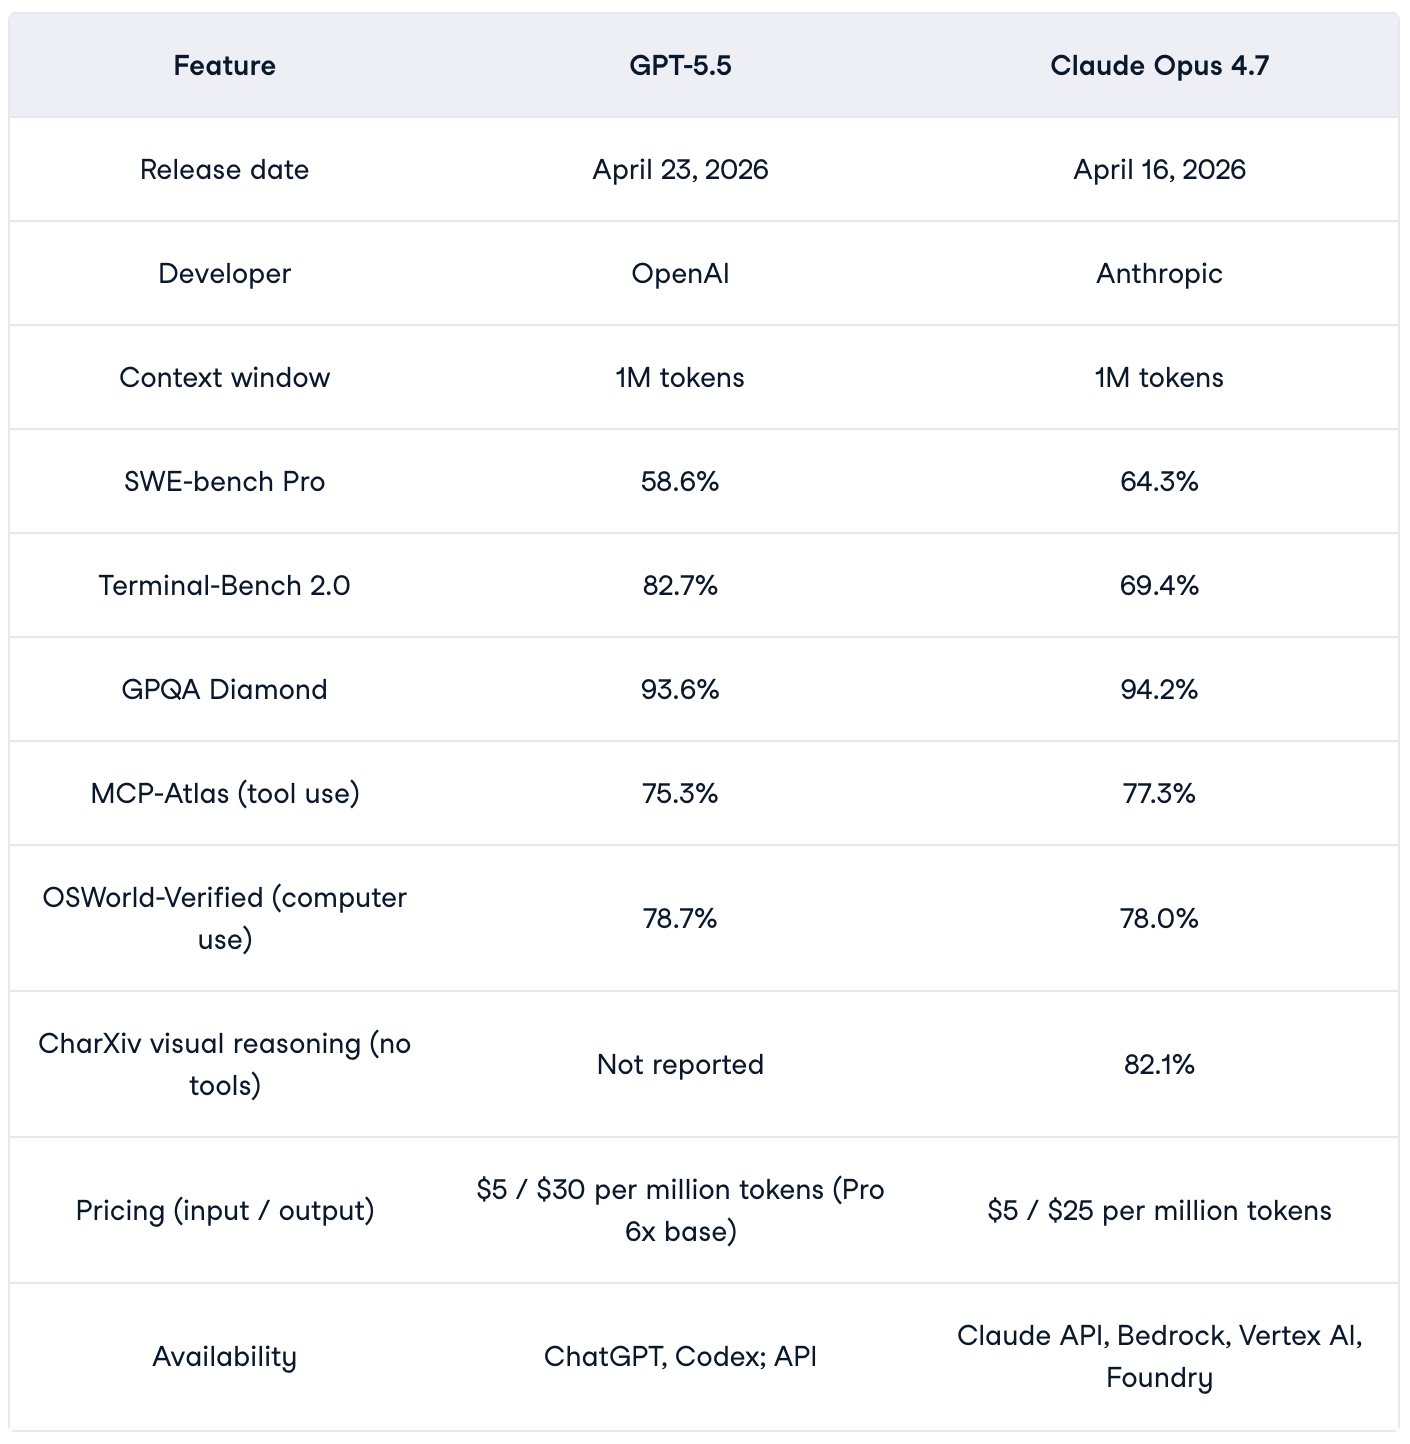
On the 10 benchmarks where both OpenAI and Anthropic report scores, here's the split: Claude Opus 4.7 leads on 6. GPT-5.5 leads on 4. But the leads aren't random. They cluster by category. And that changes what "winning" means entirely.
@godofprompt
-
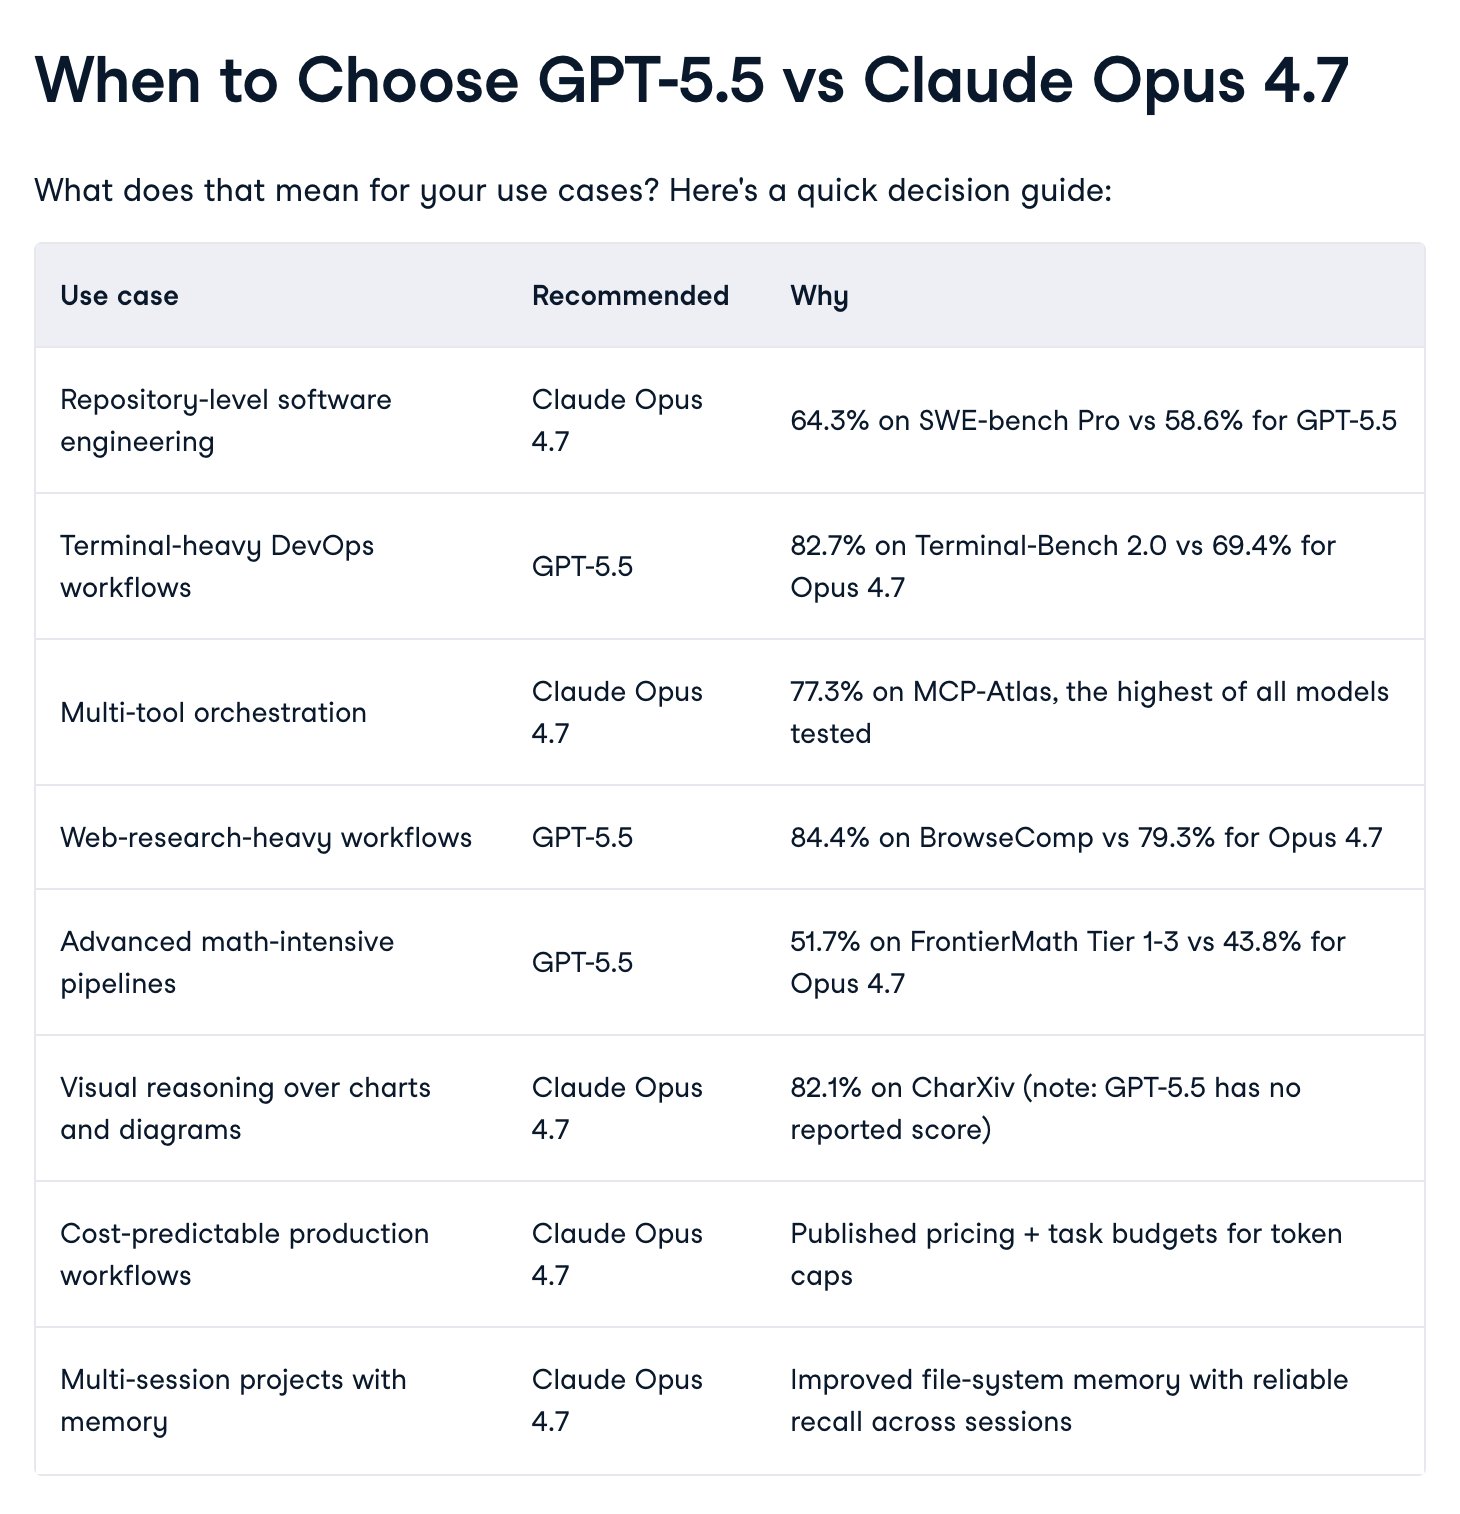
GPT-5.5 vs Claude Opus 4.7: The real benchmark story
By
–
GPT-5.5 shipped 7 days after Claude Opus 4.7. Everyone picked a winner based on headlines. I looked at every benchmark both labs published. The real story isn't what most people are reporting:
-
Reflection protocol before any serious AI task
By
–
LLMs don't think. You do. So before I ask AI to do anything serious, I run this prompt first. 3x more upvoted on r/ChatGPT than any other prompt type. Here's my version: ————————-
THINKING PROTOCOL
————————- You are a senior expert in [your -
Transform any AI model into a senior business strategist with this prompt
By
–
The prompt I use to turn any AI model into a senior business strategist: ———— Prompt: You are a senior management consultant with 20 years of experience across Fortune 500 companies and high-growth startups. I will describe a business challenge. Your job:
1.Ask me 5 -
Three Steps to Double AI Session Output Quality
By
–
How to start today: 1. Write a one-page IDENTITY file for your project (who, what, voice, constraints)
2. Keep a running DECISIONS log (what you chose, what you tried, why)
3. Load both at the start of every AI session Output quality doubles. The data is clear. -
Optimize thinking architecture before optimizing prompts
By
–
The shift most people haven't made yet: Stop optimizing the prompt. Optimize the thinking architecture before the prompt. A prompt is a tool. A thinking system is reusable infrastructure. This is what "LLMs don't think, you do" means in practice.
-
AI operators shift from writing prompts to building thinking systems
By
–
For operators using AI daily, this changes the workflow: Before: write a great prompt, get a great output, lose the context. After: build a thinking system once, every prompt inherits it. The professionals who shifted first compound. Everyone else starts from zero every
-
Prompt drift in parallel terminals fixed by hand-built markdown system
By
–
Translation: prompt quality without persistent context produces drift. A solo operator running parallel Claude Code terminals put it best: "Each terminal has no idea what decisions I made in the other." Their workaround? A markdown file system they built by hand.
-
Structured decision files boost agent performance over raw logs
By
–
The 7-agent experiment confirmed it directly. Agents that wrote structured DECISIONS.md and PROGRESS.md files outperformed agents that dumped raw logs. Same models. Same prompts. Same starting budget. The variable was the thinking architecture between sessions.
-
Indie builder threads on AI memory and agents converge
By
–
In the last 7 days, two threads from indie builders hit 100+ comments each. One asking how to handle memory across AI tools. One running 7 AI agents head-to-head with $100 each. Both threads converged on the same finding.