The shift is simple but devastating: Opus 4.6 inferred your intent and filled in the gaps.
Opus 4.7 does EXACTLY what you ask. Nothing more. Translation: the same prompt now produces narrower, terser, sometimes broken results. Here's how to fix it
@godofprompt
-
Adjusting Prompting Strategies for Opus 4.7 Behavior Changes
By
–
-
Prompt Engineering Adjustments for Claude 3.7 Opus
By
–
RIP your old Claude prompts Opus 4.7 dropped 3 weeks ago and it follows instructions LITERALLY now. It scores 87.6% on SWE-bench (vs 80.8% on 4.6) but every prompt tuned for 4.6 is silently failing. 7 fixes that stopped my outputs from getting worse:
-
Using AI prompts to automate solopreneur workflows
By
–
Most solopreneurs spend 60-70% of their day in Q1 and Q3. Firefighting and reacting to other people's timelines. Q2 is where systems get built, skills compound, and your revenue stops depending on you showing up every single hour. This prompt shows you the split. Then
-
Using MCP Connectors and Prompts for AI-Driven Data Audits
By
–
Three ways to deploy this: MCP Connectors (strongest): If you use Claude with Google Calendar, Notion, or any connected app, paste the prompt and say "read my calendar for this week." Claude pulls your real schedule and runs the audit on live data. Spreadsheet upload: Export
-
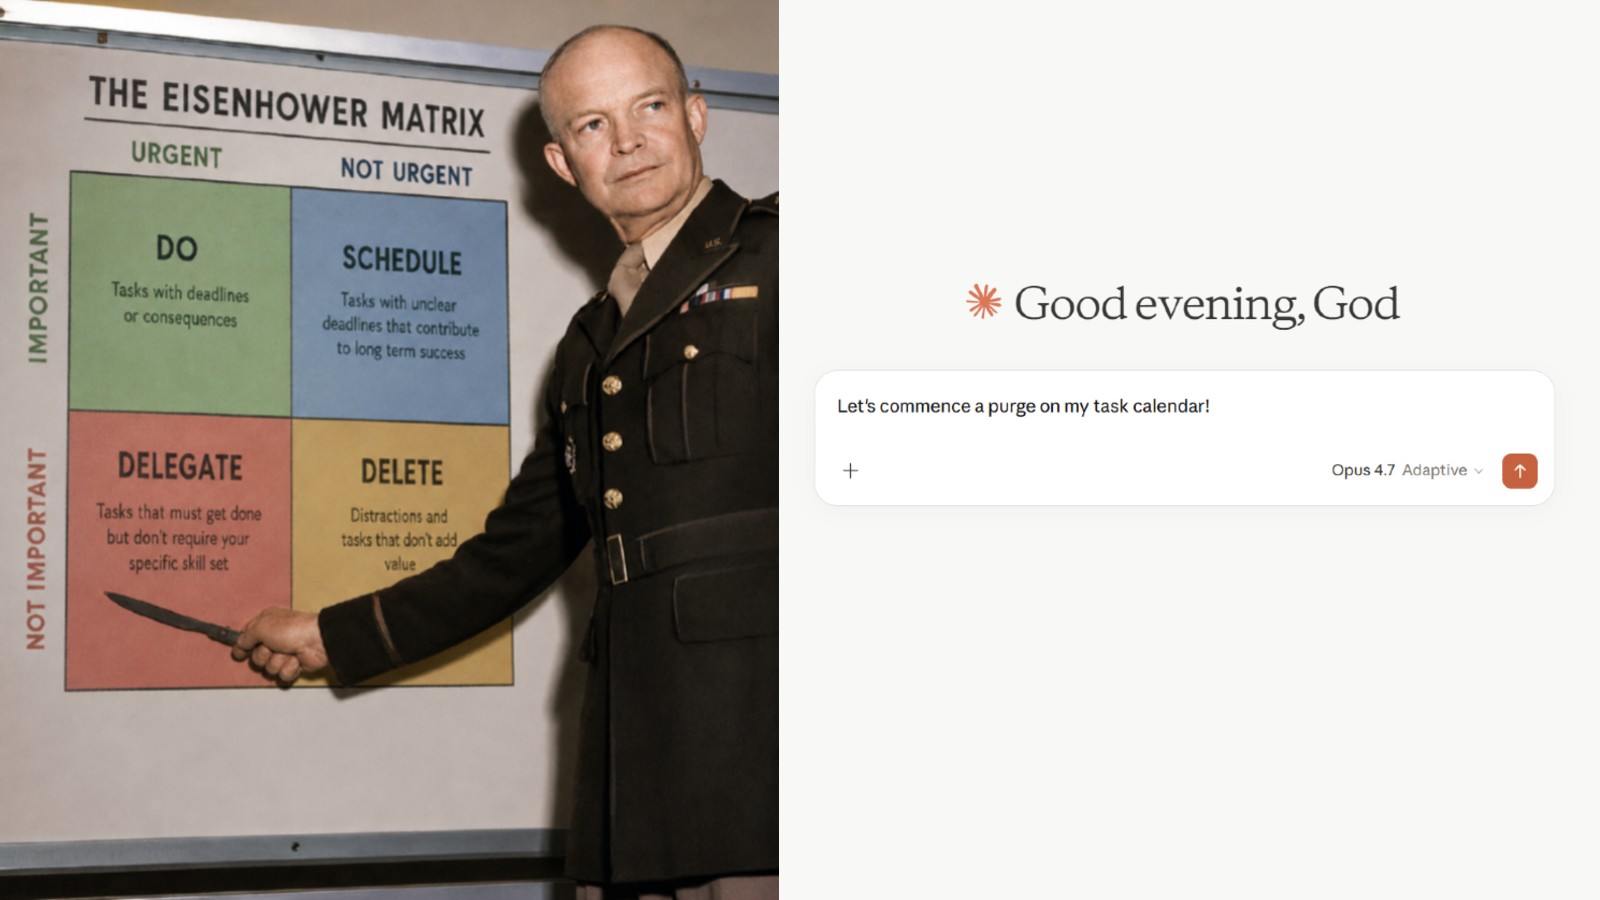
Using AI for Eisenhower Matrix task management and time auditing
By
–
Steal my Eisenhower Matrix prompt to audit your entire schedule and find where your time is actually leaking. Built for solopreneurs who control their own calendar. Feed it your real tasks and it sorts every single one into four quadrants, exposes your time split, and rebuilds
-
Claude Code technical team shifts from Markdown to HTML output
By
–
The team that built Claude Code stopped using Markdown. This isn't from a random AI account farming engagement. Thariq Shihipar is on Anthropic's Claude Code technical staff. He helped build the tool, and he's publishing why his own team moved to HTML as their default output
-

New benchmark for evaluating autonomous AI agent performance
By
–
a researcher at ICML opens his paper with a question. what does your AI agent do when nobody’s watching? he builds a benchmark. multi-step tasks. tool use. coding assistants, research agents, the kind of thing you trust to run for hours without supervision. he gives the
-
Routing tasks to cheapest model that meets quality bar
By
–
What changed in May 2026: > Before: you picked one model and committed.
> After: you route tasks to the cheapest model that meets the quality bar. DeepSeek V4-Pro scores within 7-8 points of Claude Opus 4.7 on SWE-bench. At 1/7th the cost during promo. The prompting skill -
DeepSeek as cheap second opinion alongside Claude
By
–
The key insight most people miss: DeepSeek replacing Claude entirely is the wrong move. DeepSeek as a $0.14 second opinion running alongside Claude is the right move. Same thinking system. Dramatically different API bill.
-

DeepSeek V4 integrated with Claude Code, reduced cost, parallel usage
By
–
DeepSeek V4 now speaks Claude Code natively. $0.14 per million tokens vs $5.00 for Claude Opus 4.7. Here's the exact setup that runs DeepSeek as a second opinion alongside your main Claude session, without replacing it: ———————————-
DEEPSEEK PARALLEL
—