10x your prompting skills with my prompt engineering guide → Mini-course
→ Free resources
→ Tips & tricks Grab it while it's free ↓ https://
godofprompt.ai/prompt-enginee
ring-guide
…
@godofprompt
-
Free prompt engineering guide: mini-course, resources, tips & tricks
By
–
-

Choose: get replaced by AI or become 10x more productive
By
–
You have a choice. Either get replaced by AI, or learn to use it and become 10x more productive.
-

AI job apocalypse is just a negotiation tactic
By
–
every CEO: “AI will replace 30% of jobs” *implements AI* *productivity drops*
*costs go up*
*rehires humans* MIT study: 95% of AI pilots failed. Fed data: only 1% actually did layoffs. the AI job apocalypse is a negotiation tactic wrapped in a press release. they want you -

Sam Altman’s contradictory AGI claims and team dissolution
By
–
Sam Altman: “AGI by 2025” also Sam Altman: “AGI will come and go and nobody will notice” also Sam Altman: “AGI has become a very sloppy term” bro dissolved his own AGI safety team while burning $7 billion a year telling everyone AGI is definitely coming trust me bro. it’s not
-

Fired 45 workers for AI, now begs them back as calls surge
By
–
Commonwealth Bank fired 45 workers. replaced them with AI. bragged about cutting 2,000 calls per week. two weeks later they’re begging those same people to come back because the AI can’t do shit. calls didn’t go down. they went UP. managers working overtime. team leads
-
Comparison of Claude Skills, Gemini Gems, Custom GPTs
By
–
Claude Skills > Gemini Gems > Custom GPTs
-
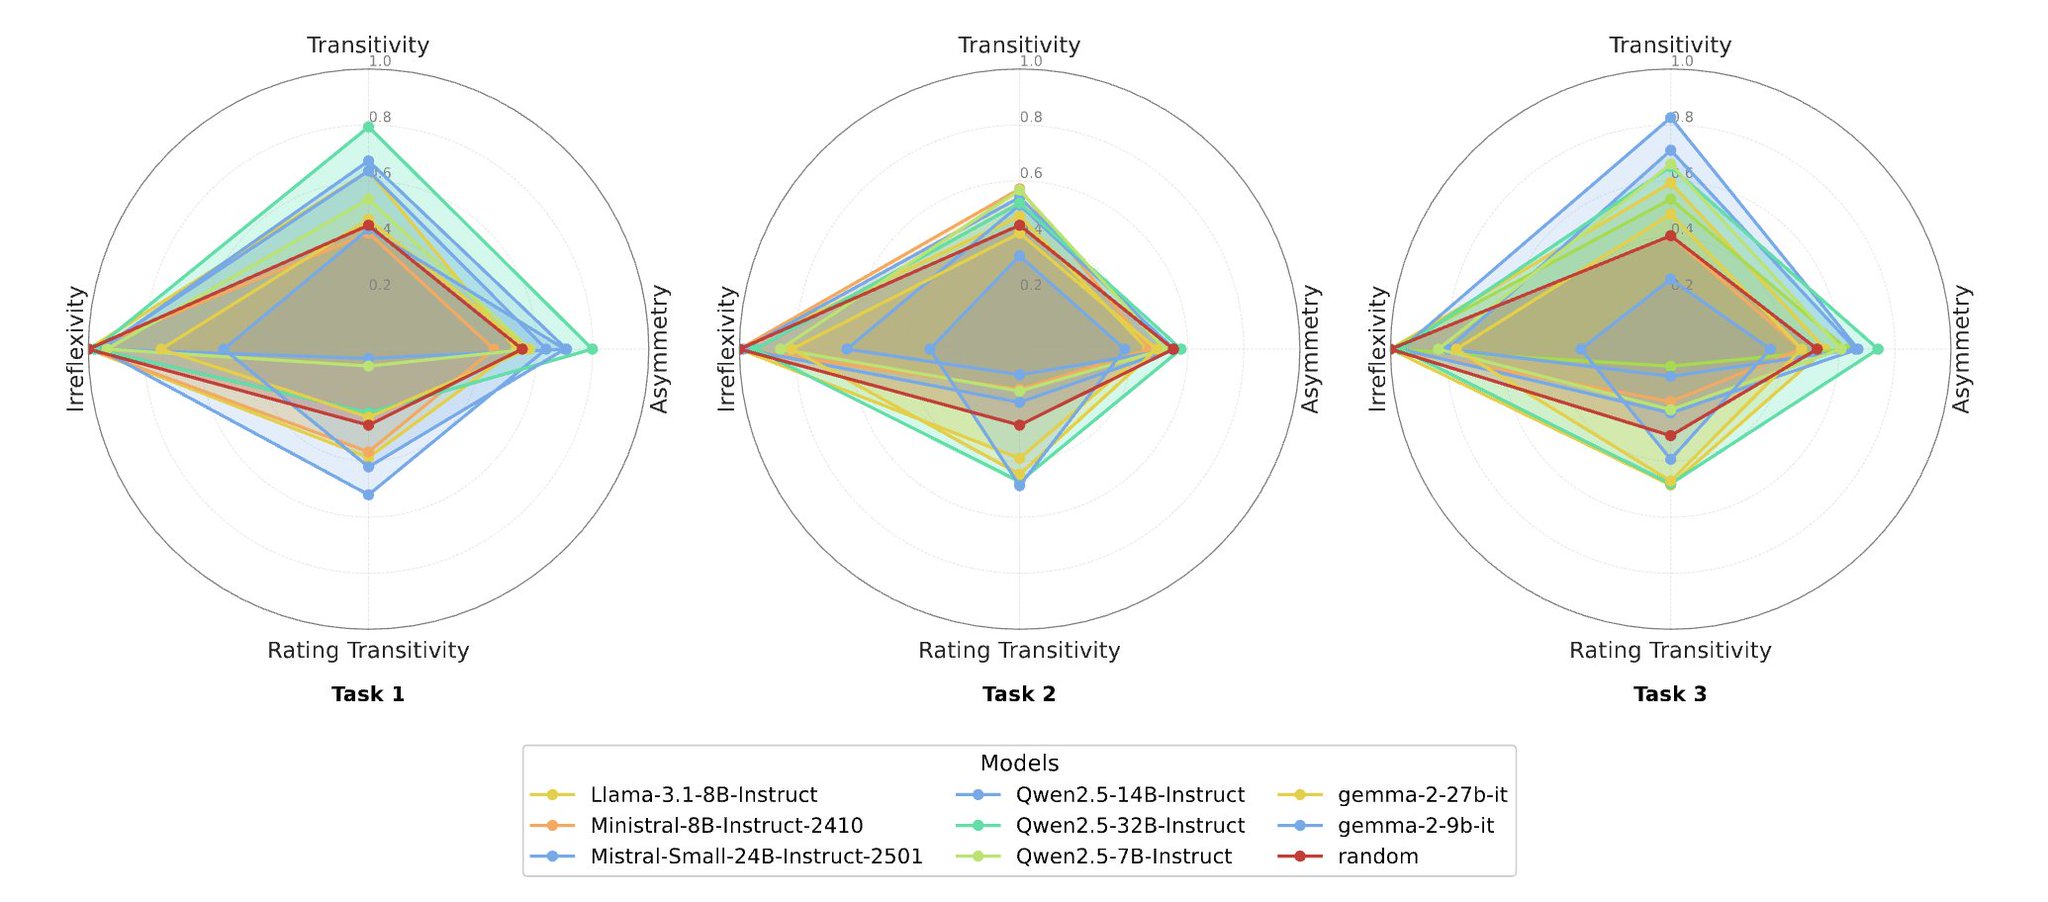
LLMs Maintain Consistent Mental Stability Across Preference Axioms
By
–
This figure visualizes the mental stability of models. LLMs like Qwen2.5 and Llama-3 stay consistent across all preference axioms transitivity, asymmetry, rating coherence proving they reason in structured, human-like ways. Even without training on user data, they infer what
-
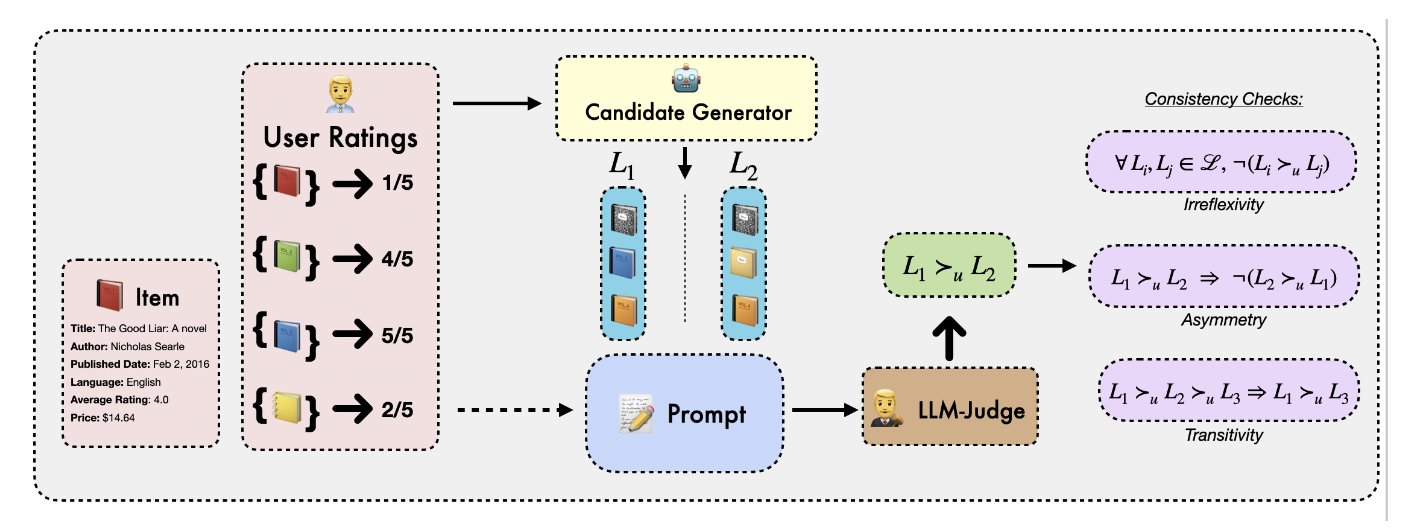
LLM-as-a-Judge pipeline replaces traditional simulators with user history
By
–
This pipeline replaces traditional simulators with a simple idea: 1. Feed the model a short user history
2. Show two candidate slates
3. Ask: which one would this user prefer?
4. Aggregate responses across multiple LLMs That’s the “LLM-as-a-Judge” world model in action -
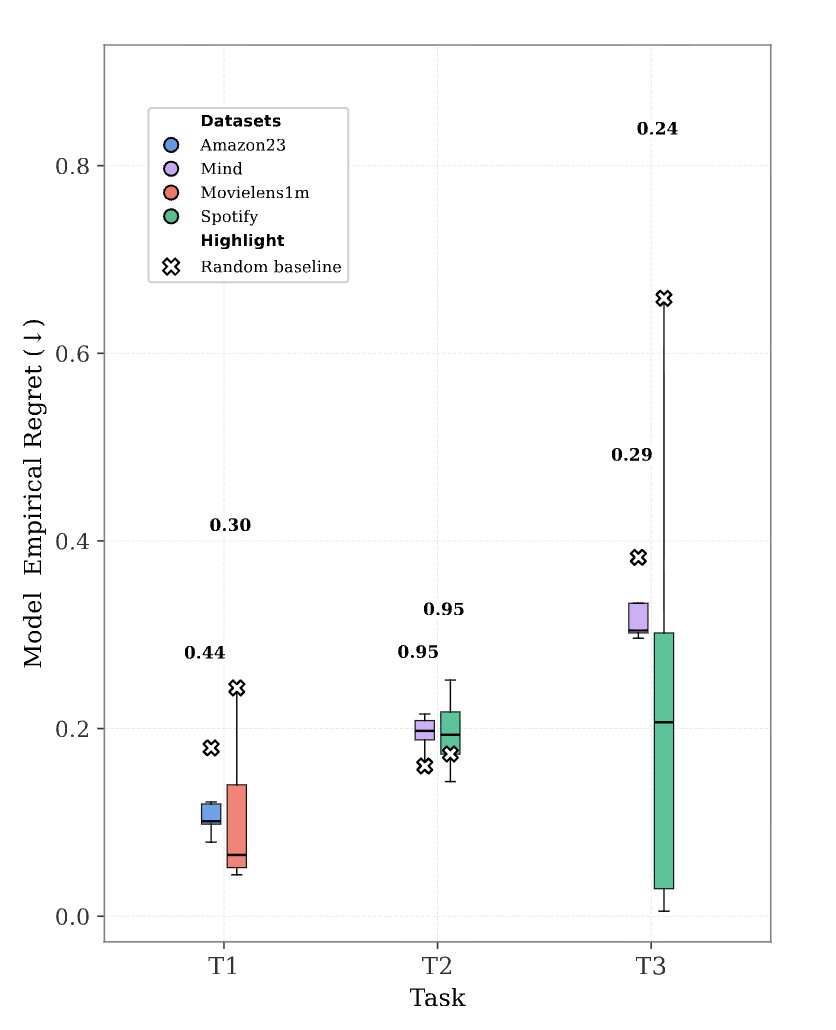
LLMs outperform random baselines in judging recommendation slates
By
–
This figure shows how well different LLMs judge slates (ordered recommendations) across datasets like Amazon, Spotify, MIND, and MovieLens. Lower “regret” = closer alignment with real user preferences. Turns out, LLMs consistently outperform random baselines when slates differ
-
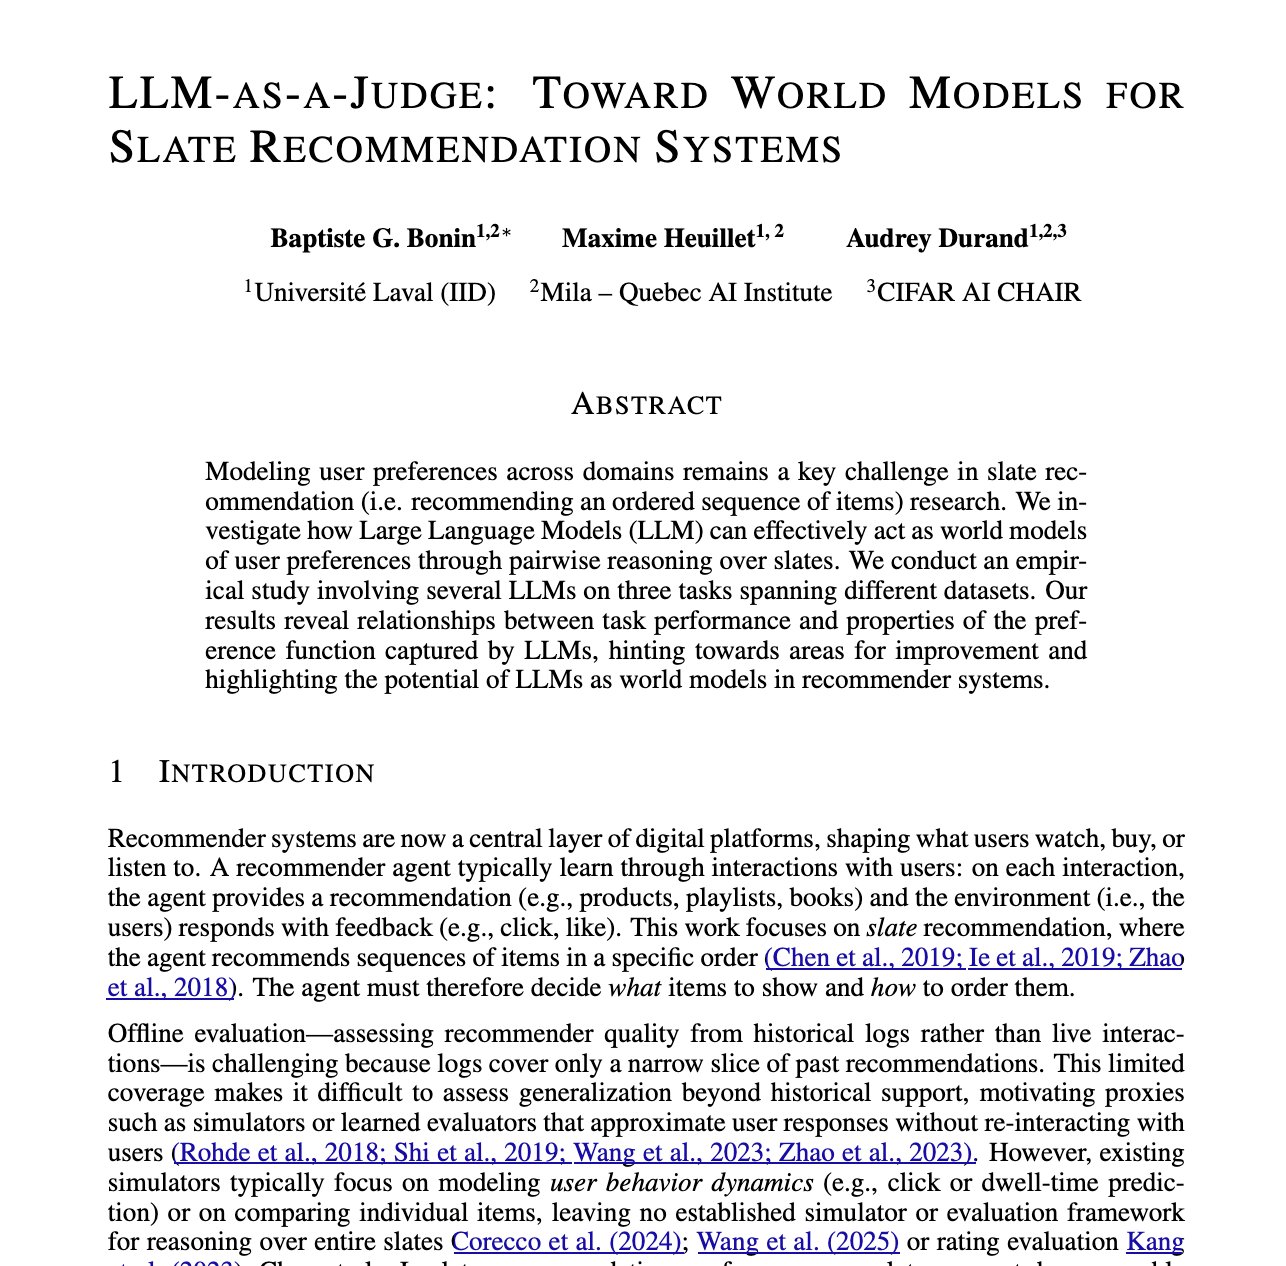
LLMs judge your taste freakishly well in new recommender paper
By
–
Holy shit… LLMs just learned how to judge your taste and they’re freakishly good at it A new paper, “LLM-as-a-Judge: Toward World Models for Slate Recommendation Systems,” just flipped recommender research on its head. Instead of simulating every click or dwell time, these