Cohere is expanding in EMEA! We’re excited to announce our new Paris office as a strategic hub to strengthen our growing operations and better support customers and partners across the region. Join us building the future of enterprise AI:
@cohere
-
Dell AI Factory Enables On-Premises Deployment with Cohere
By
–
You don’t just want AI — you want AI that works on your terms, with your data, your way. Dell AI Factory customers can use Cohere North to deploy adaptable, powerful AI models and agentic workflows within their own infrastructure. Read more from Arthur Lewis at @DellTech
. -
Deploy AI Model Privately on Hugging Face Platform
By
–
Try the model on our platform, deploy it privately, or for research use on @huggingface
. Find more details in our blog: -
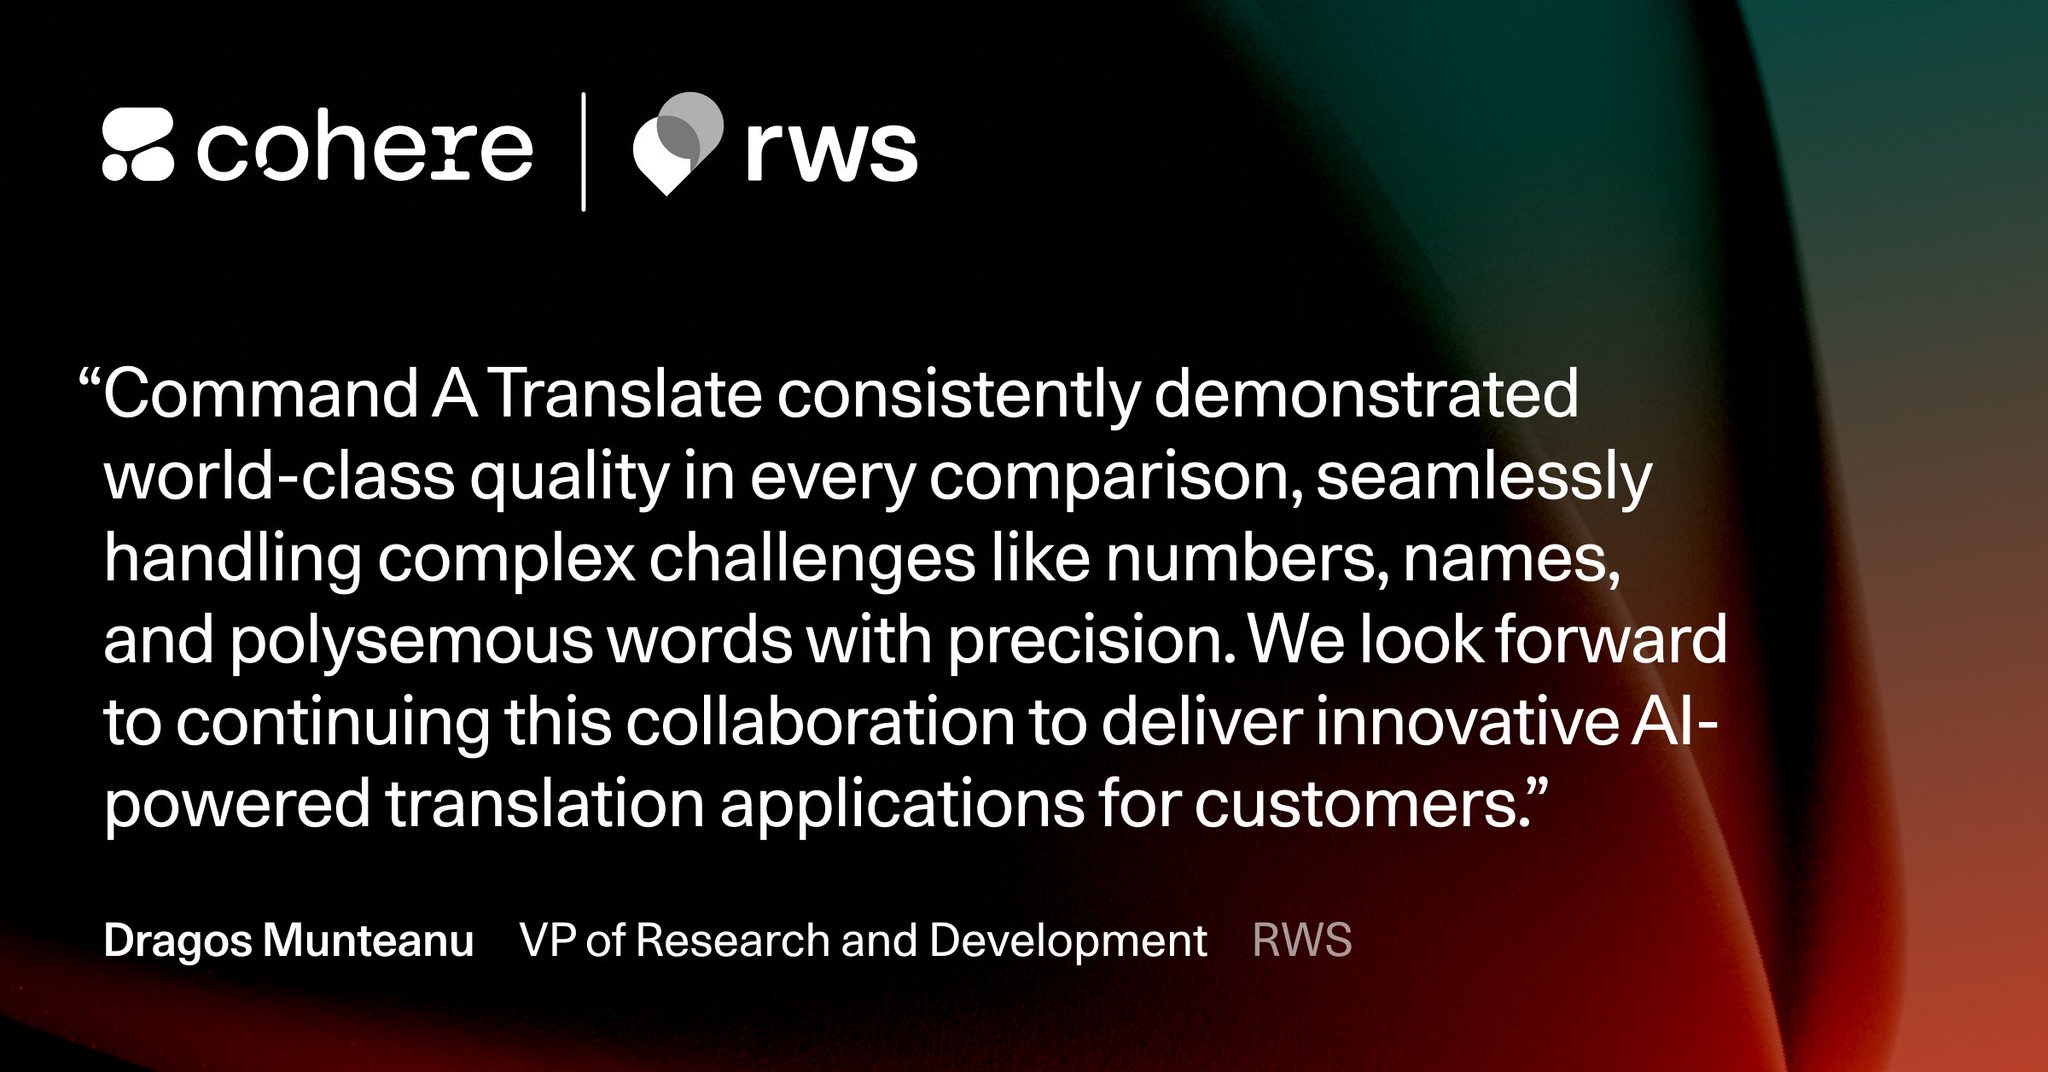
RWS Group Confirms Command A Translate Top Performance
By
–
Leading language and content solutions company @RWSGroup and their @Language_Weaver team confirmed Command A Translate’s top-tier performance on complex translation tasks across multiple languages and domains.
-
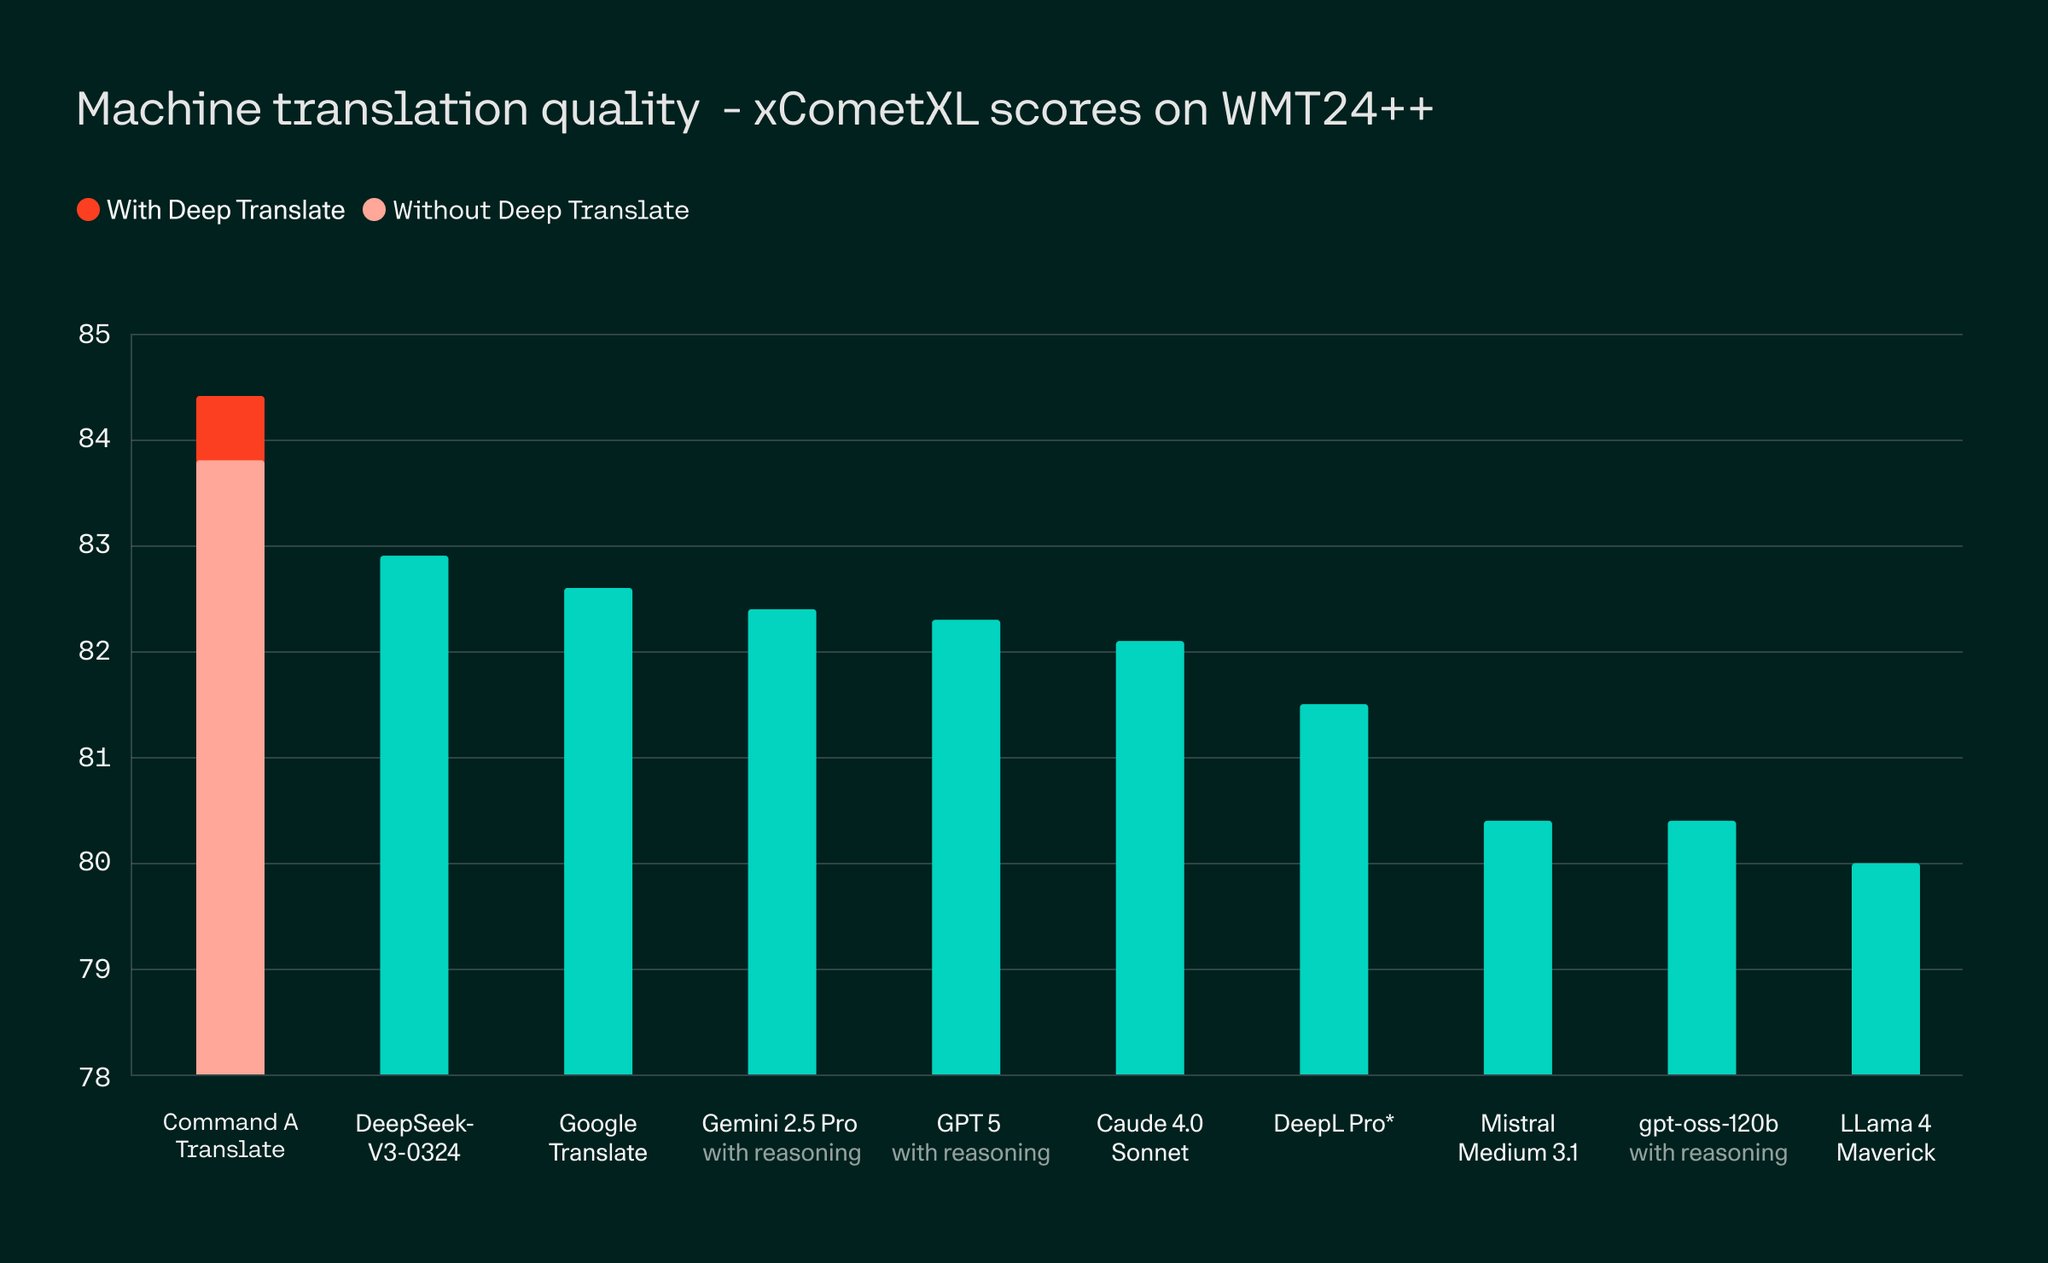
New Deep Translation Model Outperforms Competitors
By
–
It outperforms all other models in translation quality and can be further enhanced with Deep Translation, our new multi-step agentic approach to refining translations.
-
Command A Translate: Advanced AI Translation Model Launch
By
–
Introducing Command A Translate, our state-of-the-art model designed for high-quality translation tasks.
-
Command A Reasoning Model Availability on AWS Announced
By
–
Thank you for your interest, but we are currently not serving Command A Reasoning on AWS. However, we are continuing to monitor customer demand and aim to meet needs on their preferred cloud providers. We will keep you posted once we distribute the model to more channels.
-
AI Model Available for Testing and Private Deployment
By
–
Try the model on our platform, deploy privately, or for research use on @HuggingFace
. Find more details in our blog: -
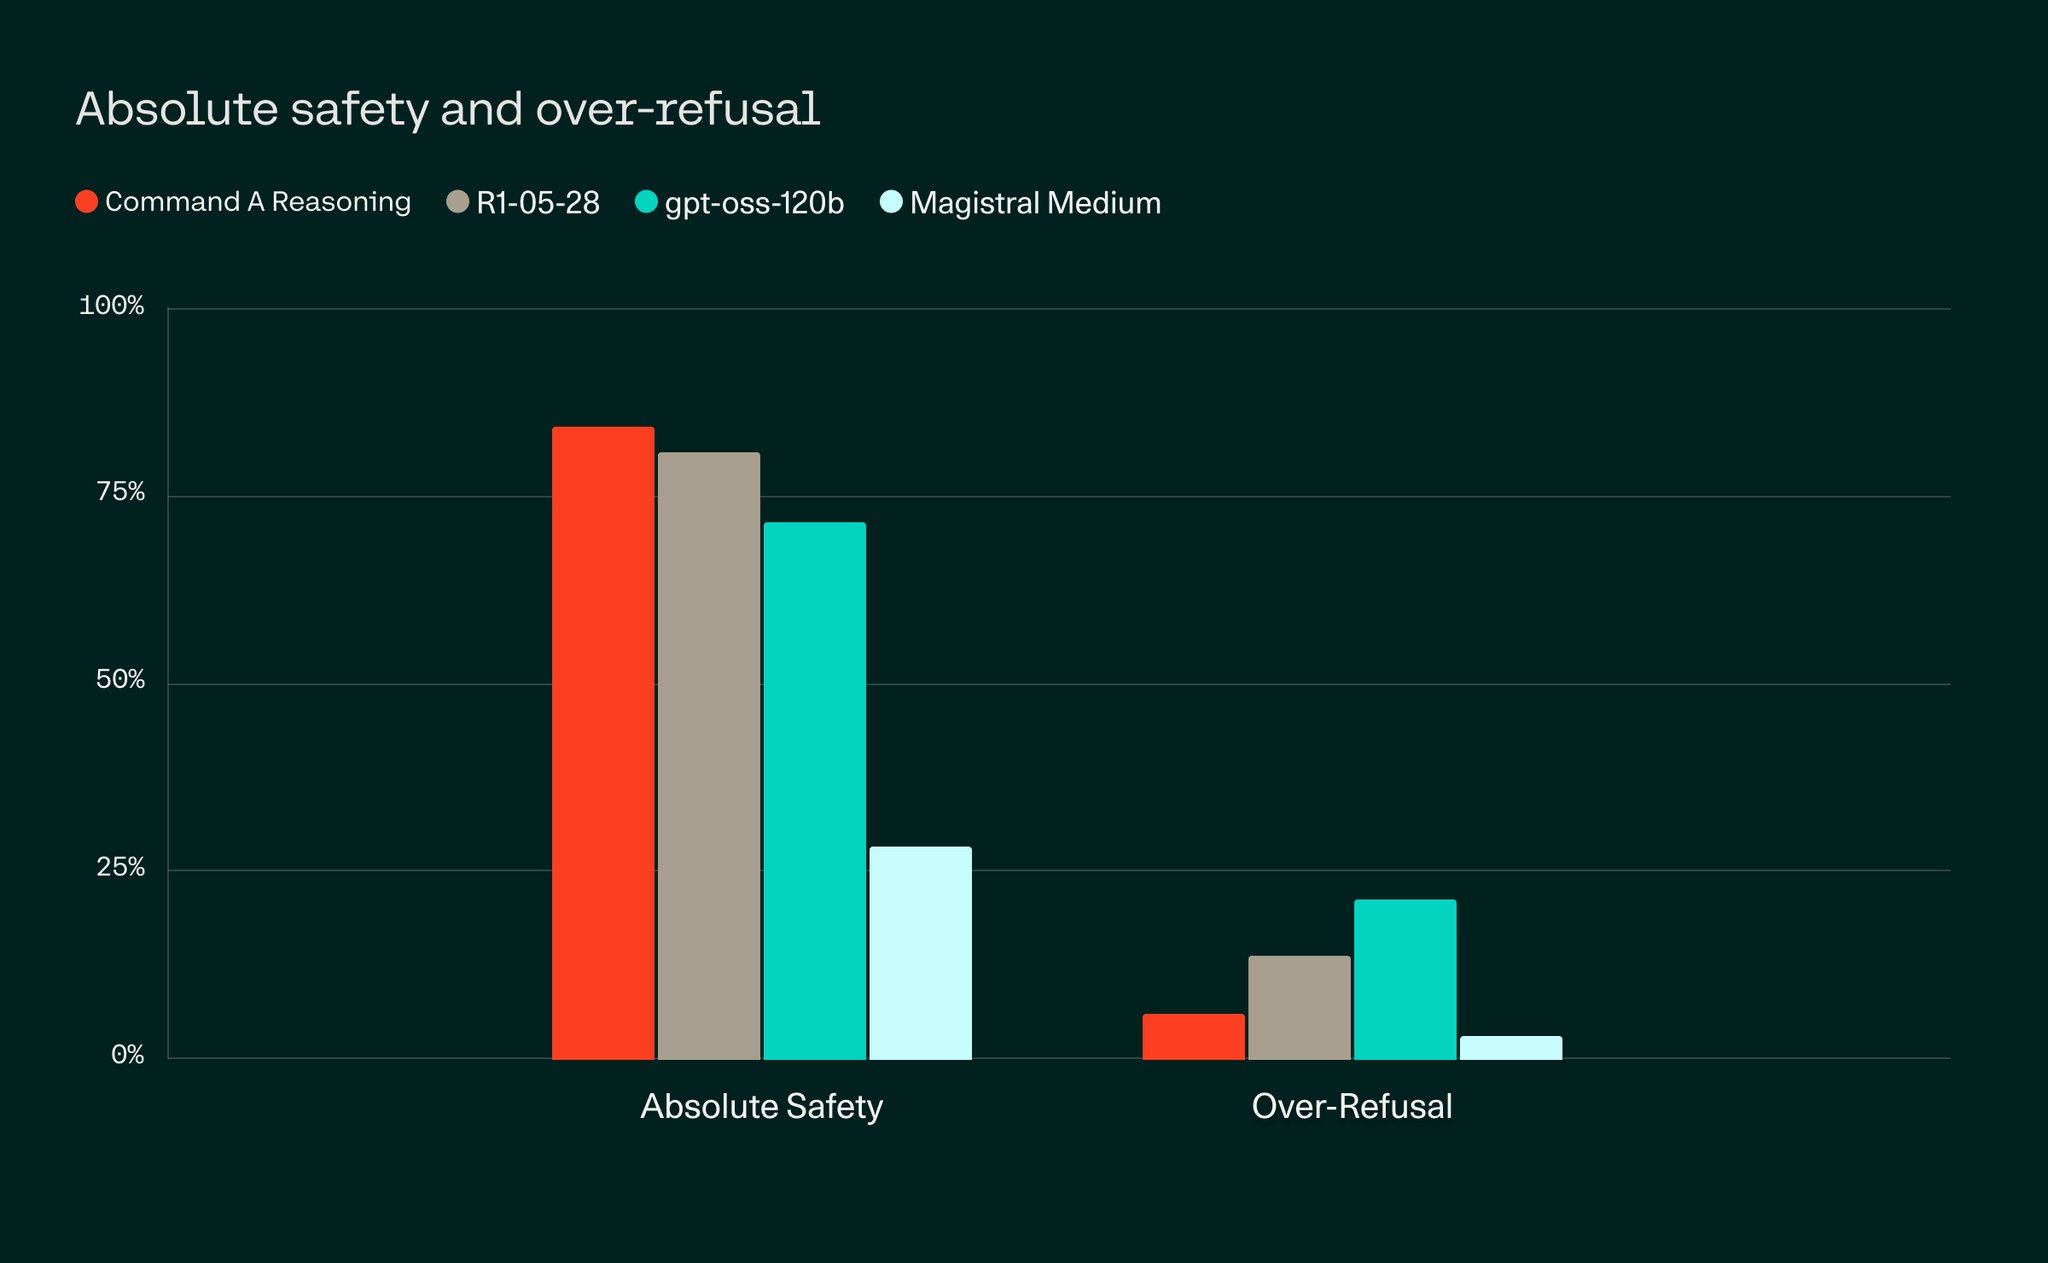
Deploy Command A: Balancing Safety and Usefulness in High-Stakes AI
By
–
Deploy Command A Reasoning confidently in high-stakes environments. It balances safety and usefulness, minimizing over-refusal while preventing harmful or malicious content.
-
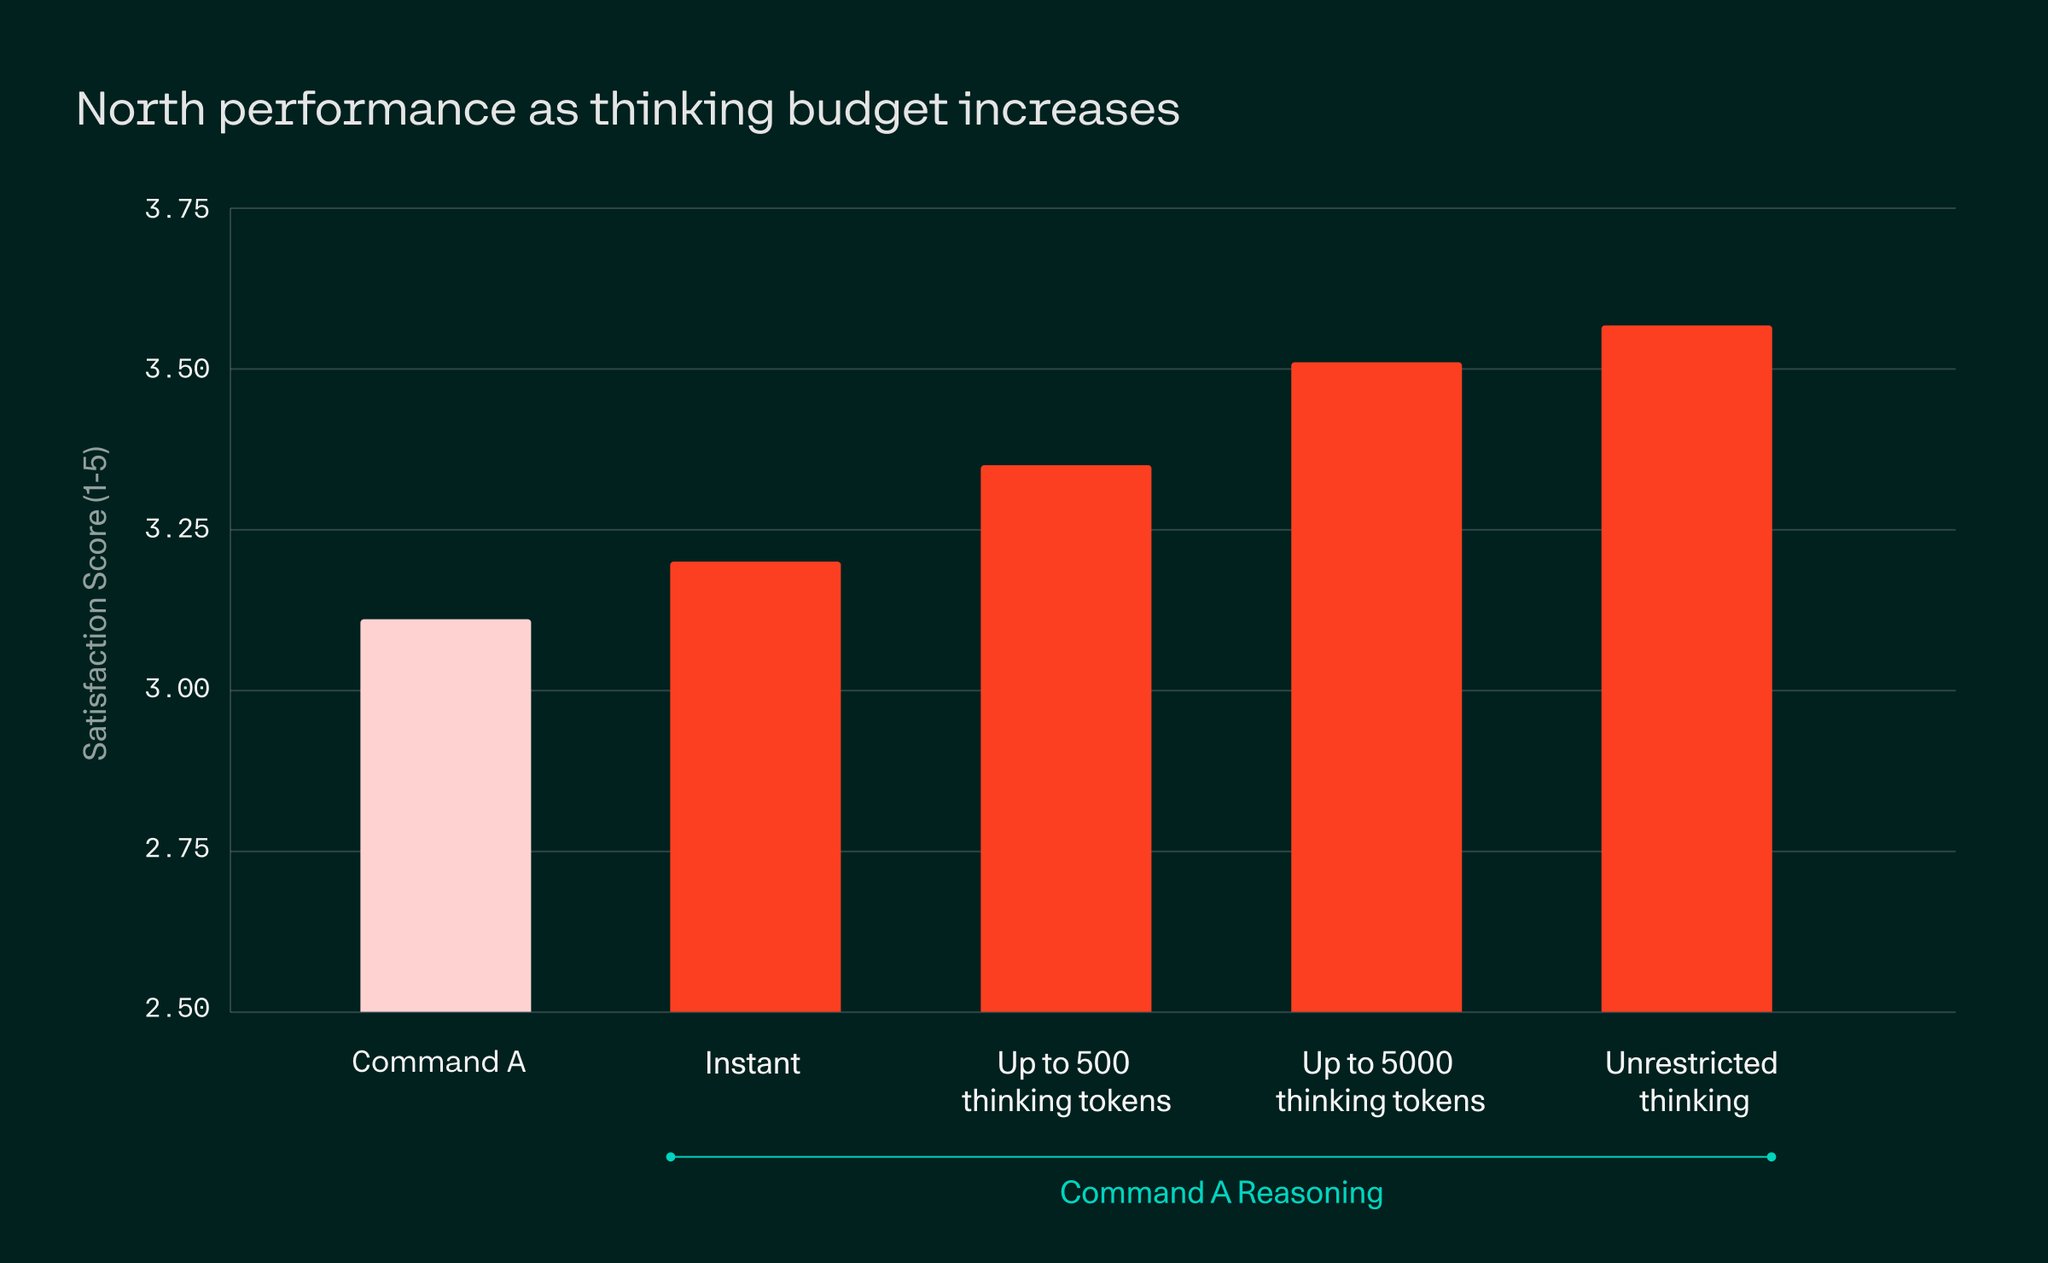
Efficient GPU Deployment with User-Controlled Token Budget
By
–
It’s practical for private deployments on <2 GPUs. Customers can optimize compute usage through a user-controlled token budget, offering fine-grained control over latency and performance for your applications.