
Full body tracking now possible using only WiFi signals A deep neural network maps the phase and amplitude of WiFi signals to UV coordinates within 24 human regions The model can estimate the dense pose of multiple subjects by utilizing WiFi signals as the only input
@aibreakfast
-
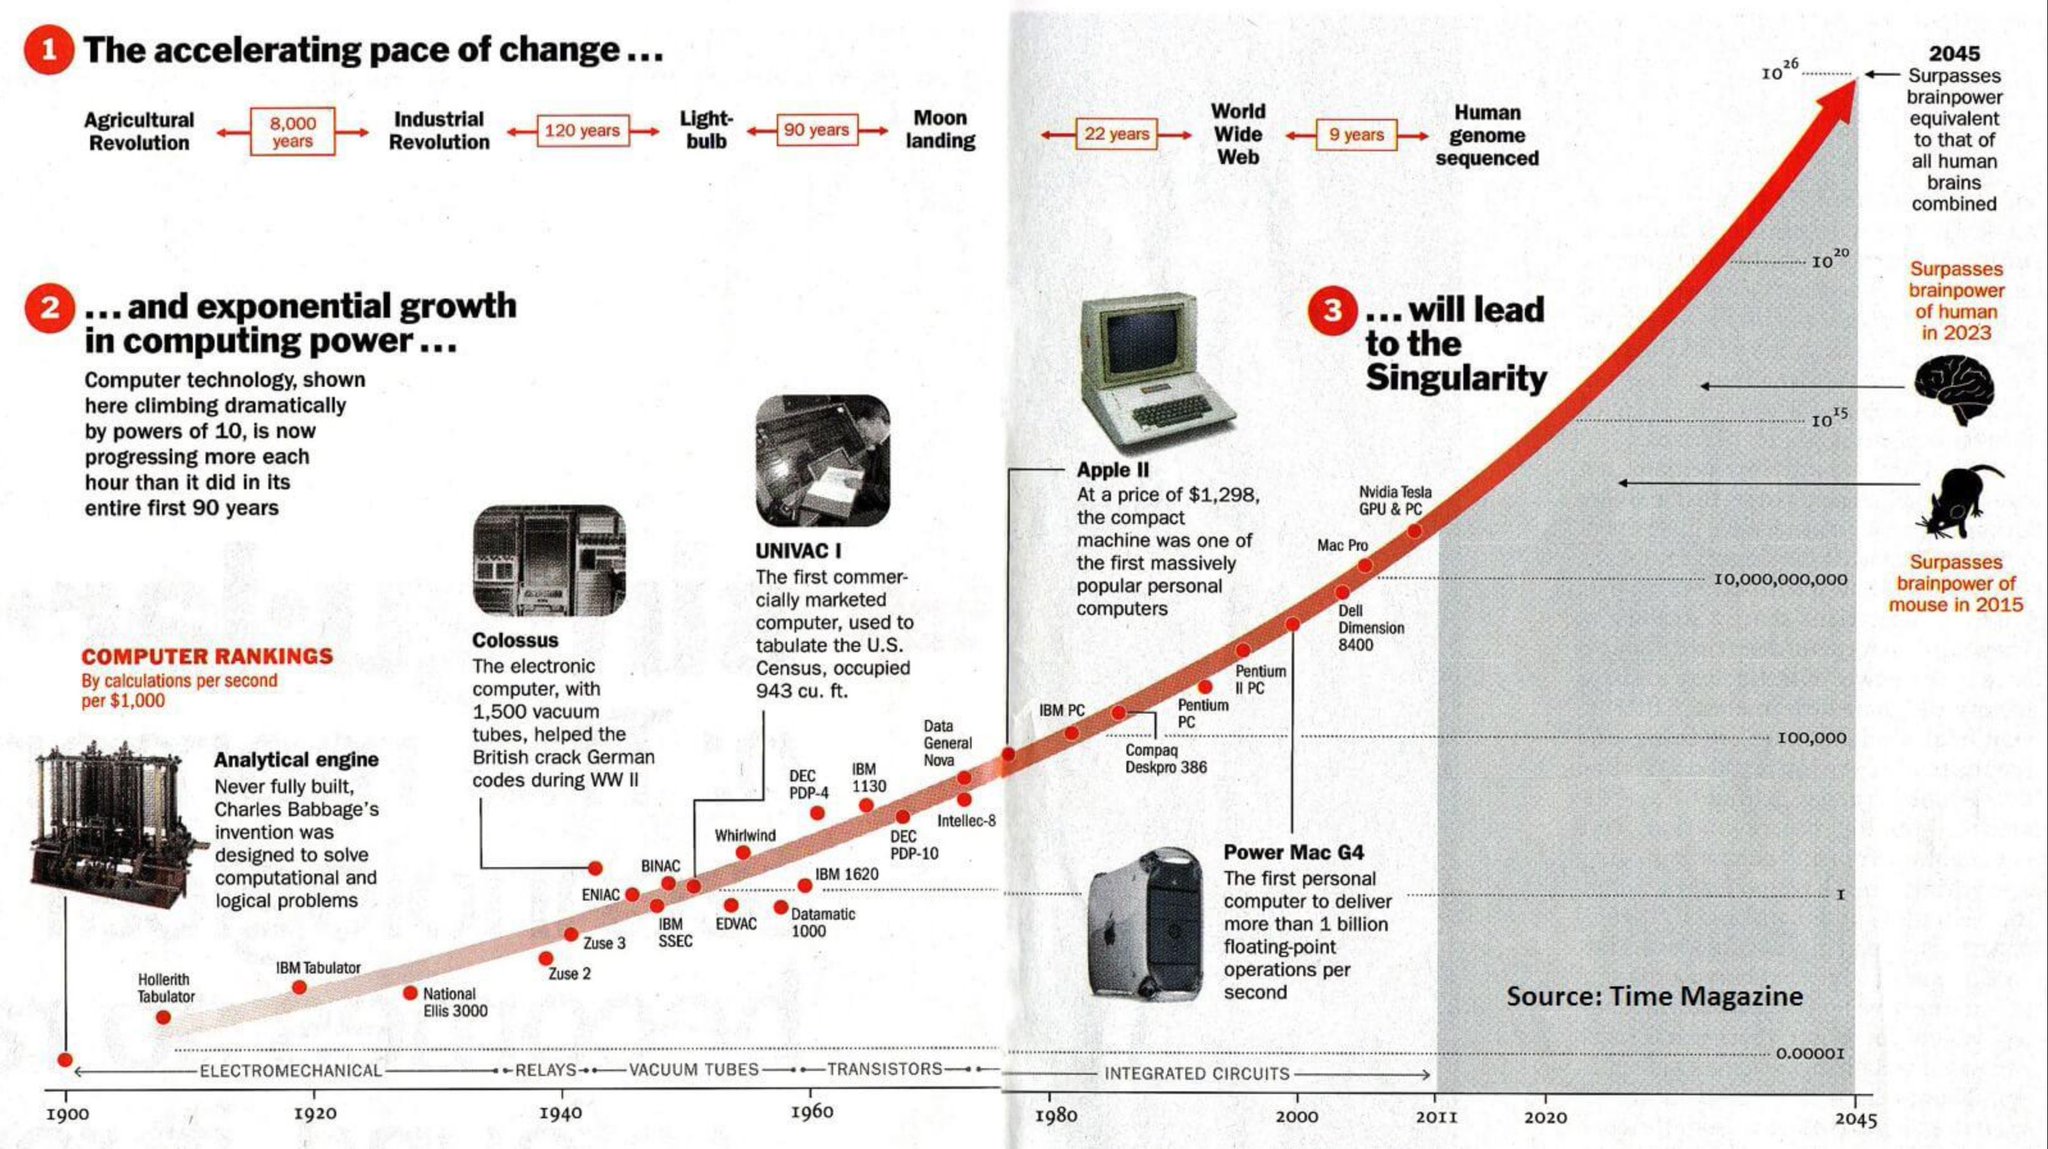
Ray Kurzweil’s 2011 Prediction on Singularity Advancement
By
–
Advancement of the Singularity as predicted by Ray Kerzweil in 2011
-
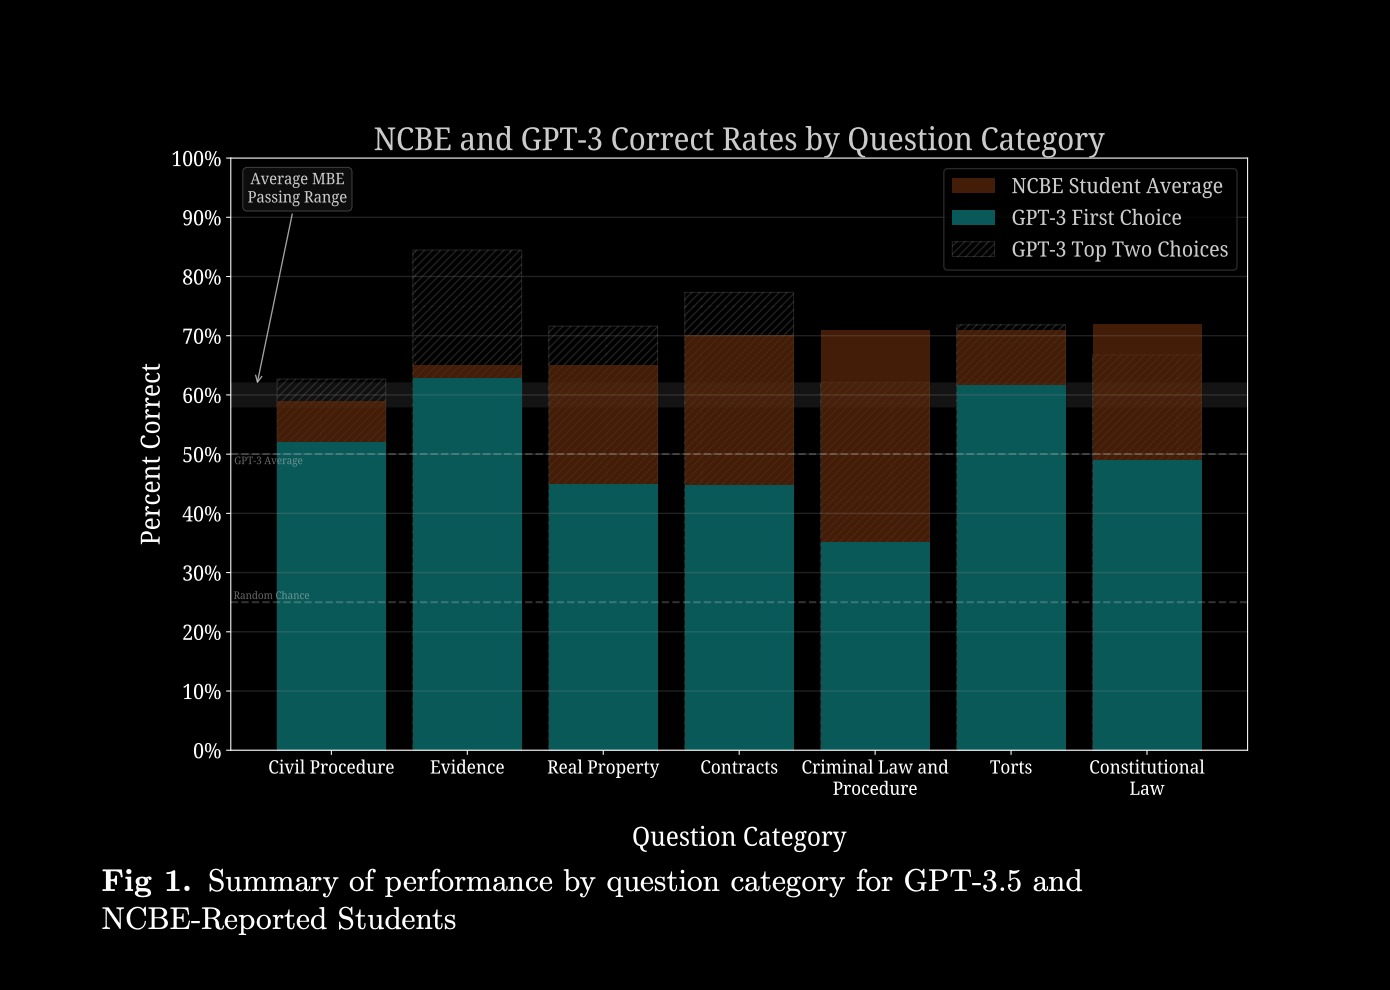
GPT-3.5 passes multiple-choice sections of Bar Exam for Evidence and Torts
By
–
GPT-3.5 took the Bar Exam "Passing range" scores on multiple-choice section for Evidence & Torts categories. Full write-up in Monday's newsletter Research paper: https://
arxiv.org/pdf/2212.14402
.pdf
… -
Universities face bankruptcy due to AI, education to rely on LLM skills.
By
–
Would not be surprised if 1/3rd of universities go broke in the next 5 years because of OpenAI. A person's education and capability for knowledge work will trend towards being a perfectly correlated proportionality to their ability to utilize Large Language Models like ChatGPT.
-

ChatGPT generates satirical headlines about AI singularity
By
–
ChatGPT creates Onion headlines about the singularity
-
Microsoft Integrating ChatGPT into Office Suite
By
–
Fresh news from the paywall club: Insider leaks say Microsoft to integrate ChatGPT into all MS Office products (Word, Powerpoint, Excel, Outlook) in 2023. Microsoft's $1B investment in OpenAI gonna print.
-
Technical architecture of the VALL-E generative audio model
By
–
Instead of turning text into a series of specific sounds (called phonemes) and then into a visual representation of the sound called a mel-spectrogram, and then into a waveform (a digital representation of sound that can be played through a speaker) VALL-E takes a shortcut:
-
Technical mechanism of AI-driven voice synthesis
By
–
It generates a series of codes based on the phonemes and an audio recording of the speaker's voice.
— AI Breakfast (@AiBreakfast) 7 janvier 2023
These codes are then turned directly into a waveform, which allows it to generate speech that sounds like the speaker from just a small amount of reference audio.
Example (🔊): pic.twitter.com/HQvjJUnbiHIt generates a series of codes based on the phonemes and an audio recording of the speaker's voice. These codes are then turned directly into a waveform, which allows it to generate speech that sounds like the speaker from just a small amount of reference audio. Example ():
-
VALL-E: A new approach to natural-sounding AI speech synthesis
By
–
VALL-E is significantly better at synthesizing natural-sounding speech and accurately reproducing the characteristics of a speaker compared to anything else available. VALL-E takes a different approach than previous systems for synthesizing speech:
-
VALL-E: New Language Modeling Approach for Text-to-Speech
By
–
Digitally clone your own voice in 3 seconds: VALL-E
— AI Breakfast (@AiBreakfast) 7 janvier 2023
Inside the new language modeling approach for text-to-speech synthesis: pic.twitter.com/slaX1P3sqzDigitally clone your own voice in 3 seconds: VALL-E Inside the new language modeling approach for text-to-speech synthesis: