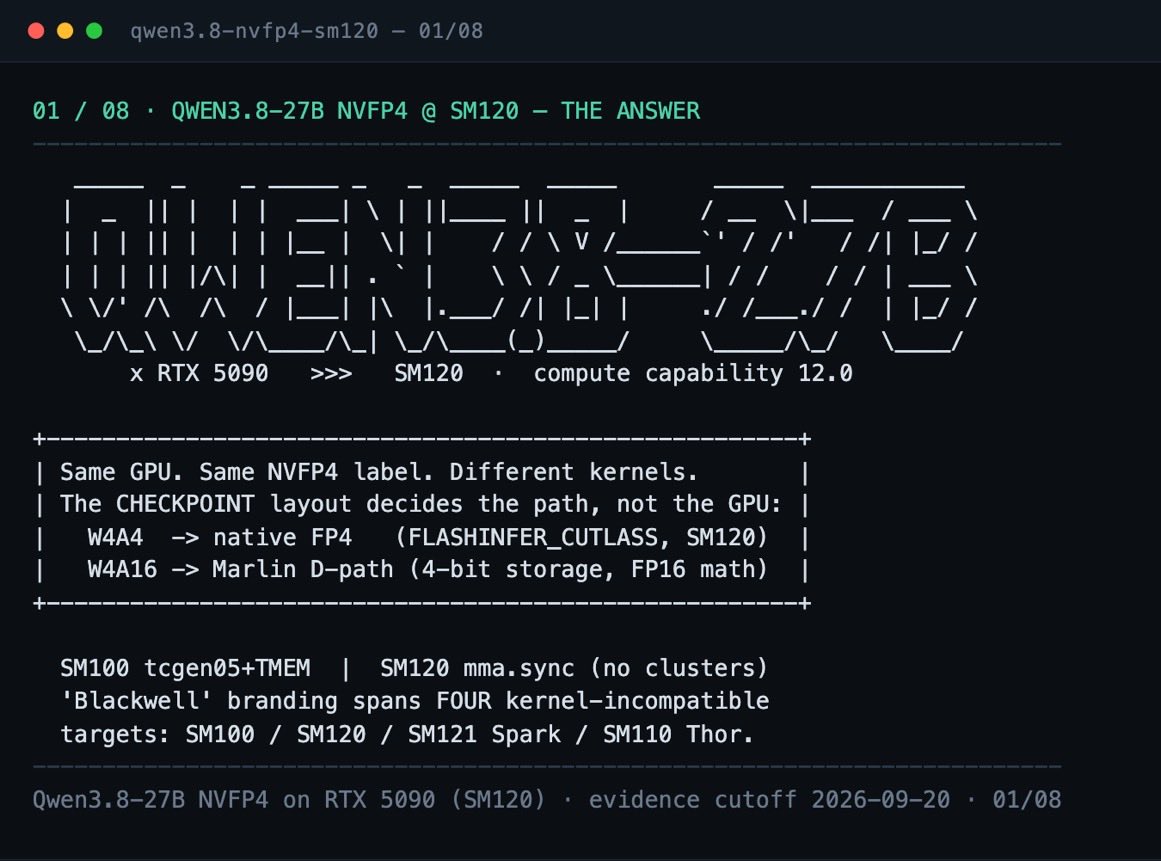
You do not pick a model and a GPU and call it done. You pick a file encoding, and a kernel path.
The GPU follows those. Start with the loop. Text becomes tokens.
Tokens move through a Transformer.
Attention decides which earlier tokens matter.
The runtime keeps a KV cache so