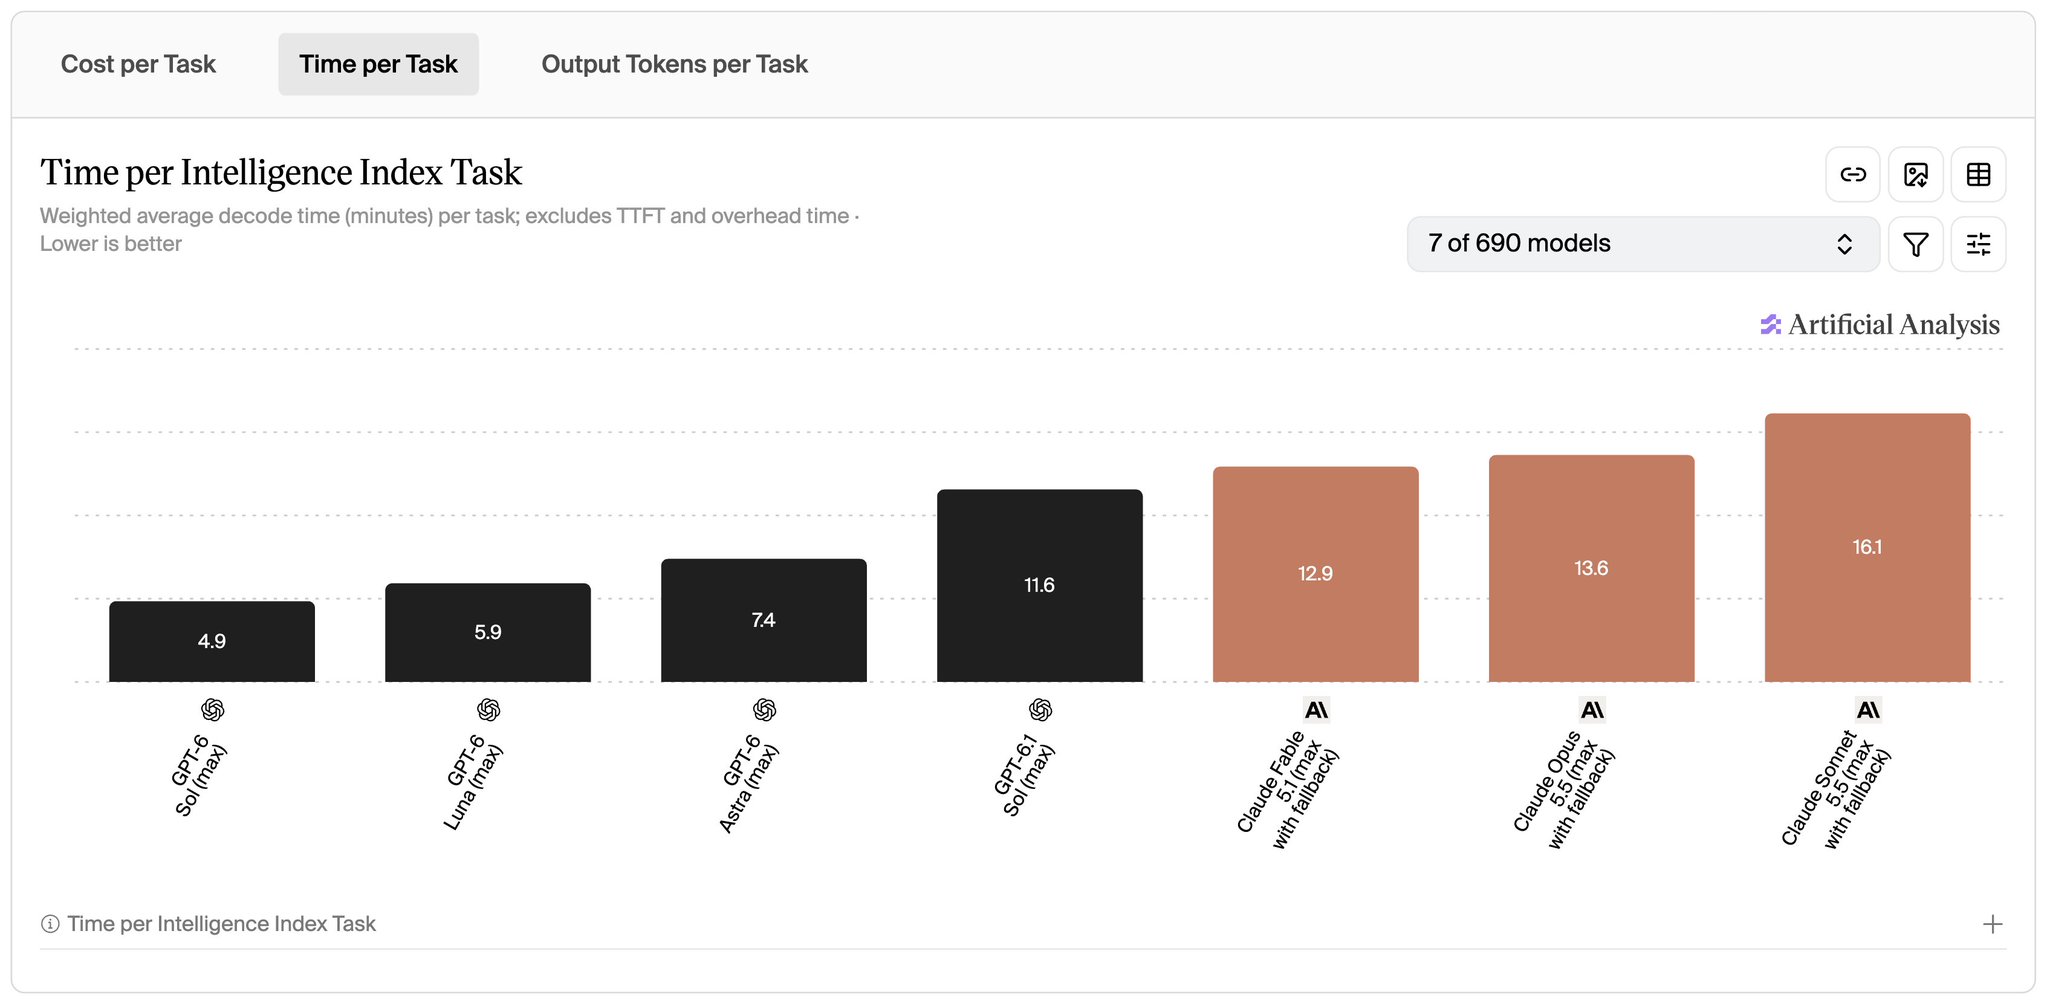
It makes no sense to compare models by speed (tok/sec) when they require different amounts of tokens to solve the same task. If you want a fair comparison, then measure their time per task, and there you will see that since GPTs generate far fewer tokens than Claude, their