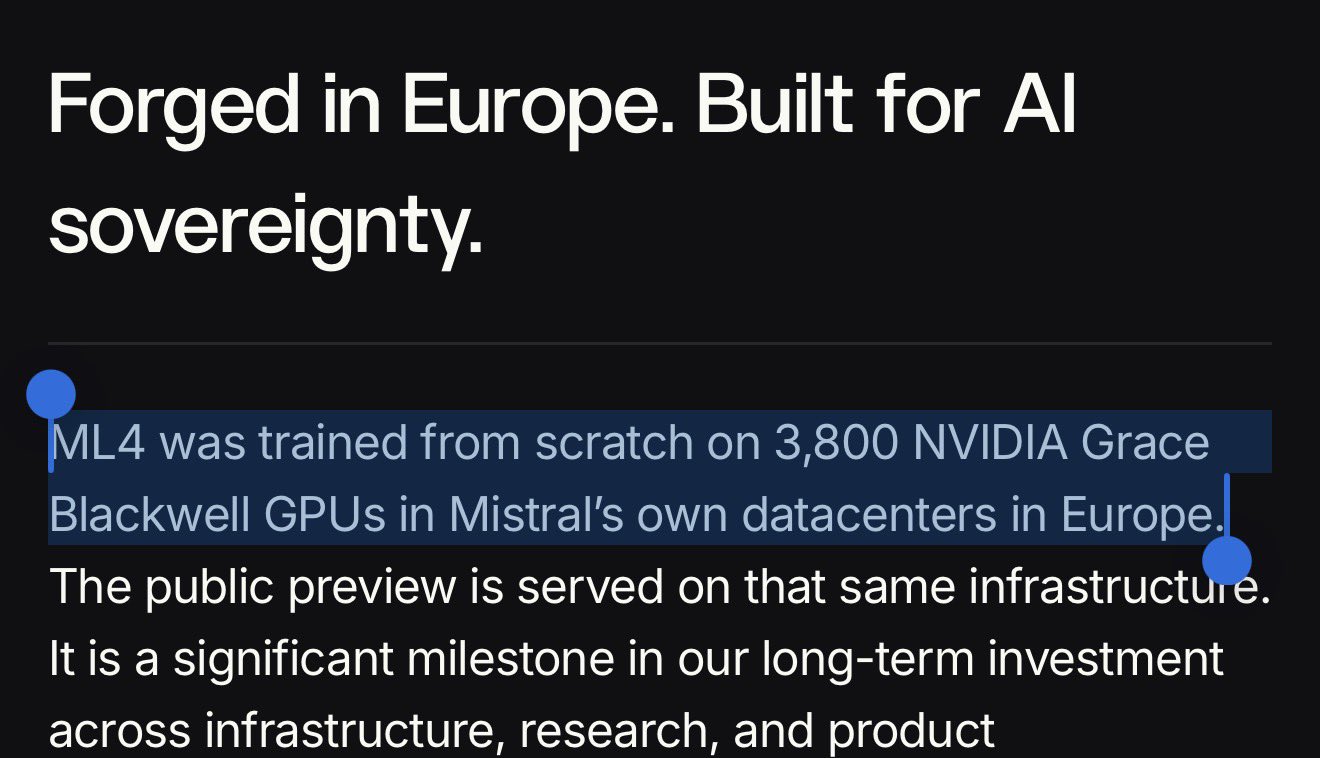
I'm very, very eager to get more info on this. Because as it stands, I don't see how it's possible to train "from scratch" a model with 1,000 billion parameters (so 46 billion active) on 3,800 GPUs. So I'd really like more details, but obviously,
Doubt about training a 1T model from scratch on 3800 GPUs
By
–