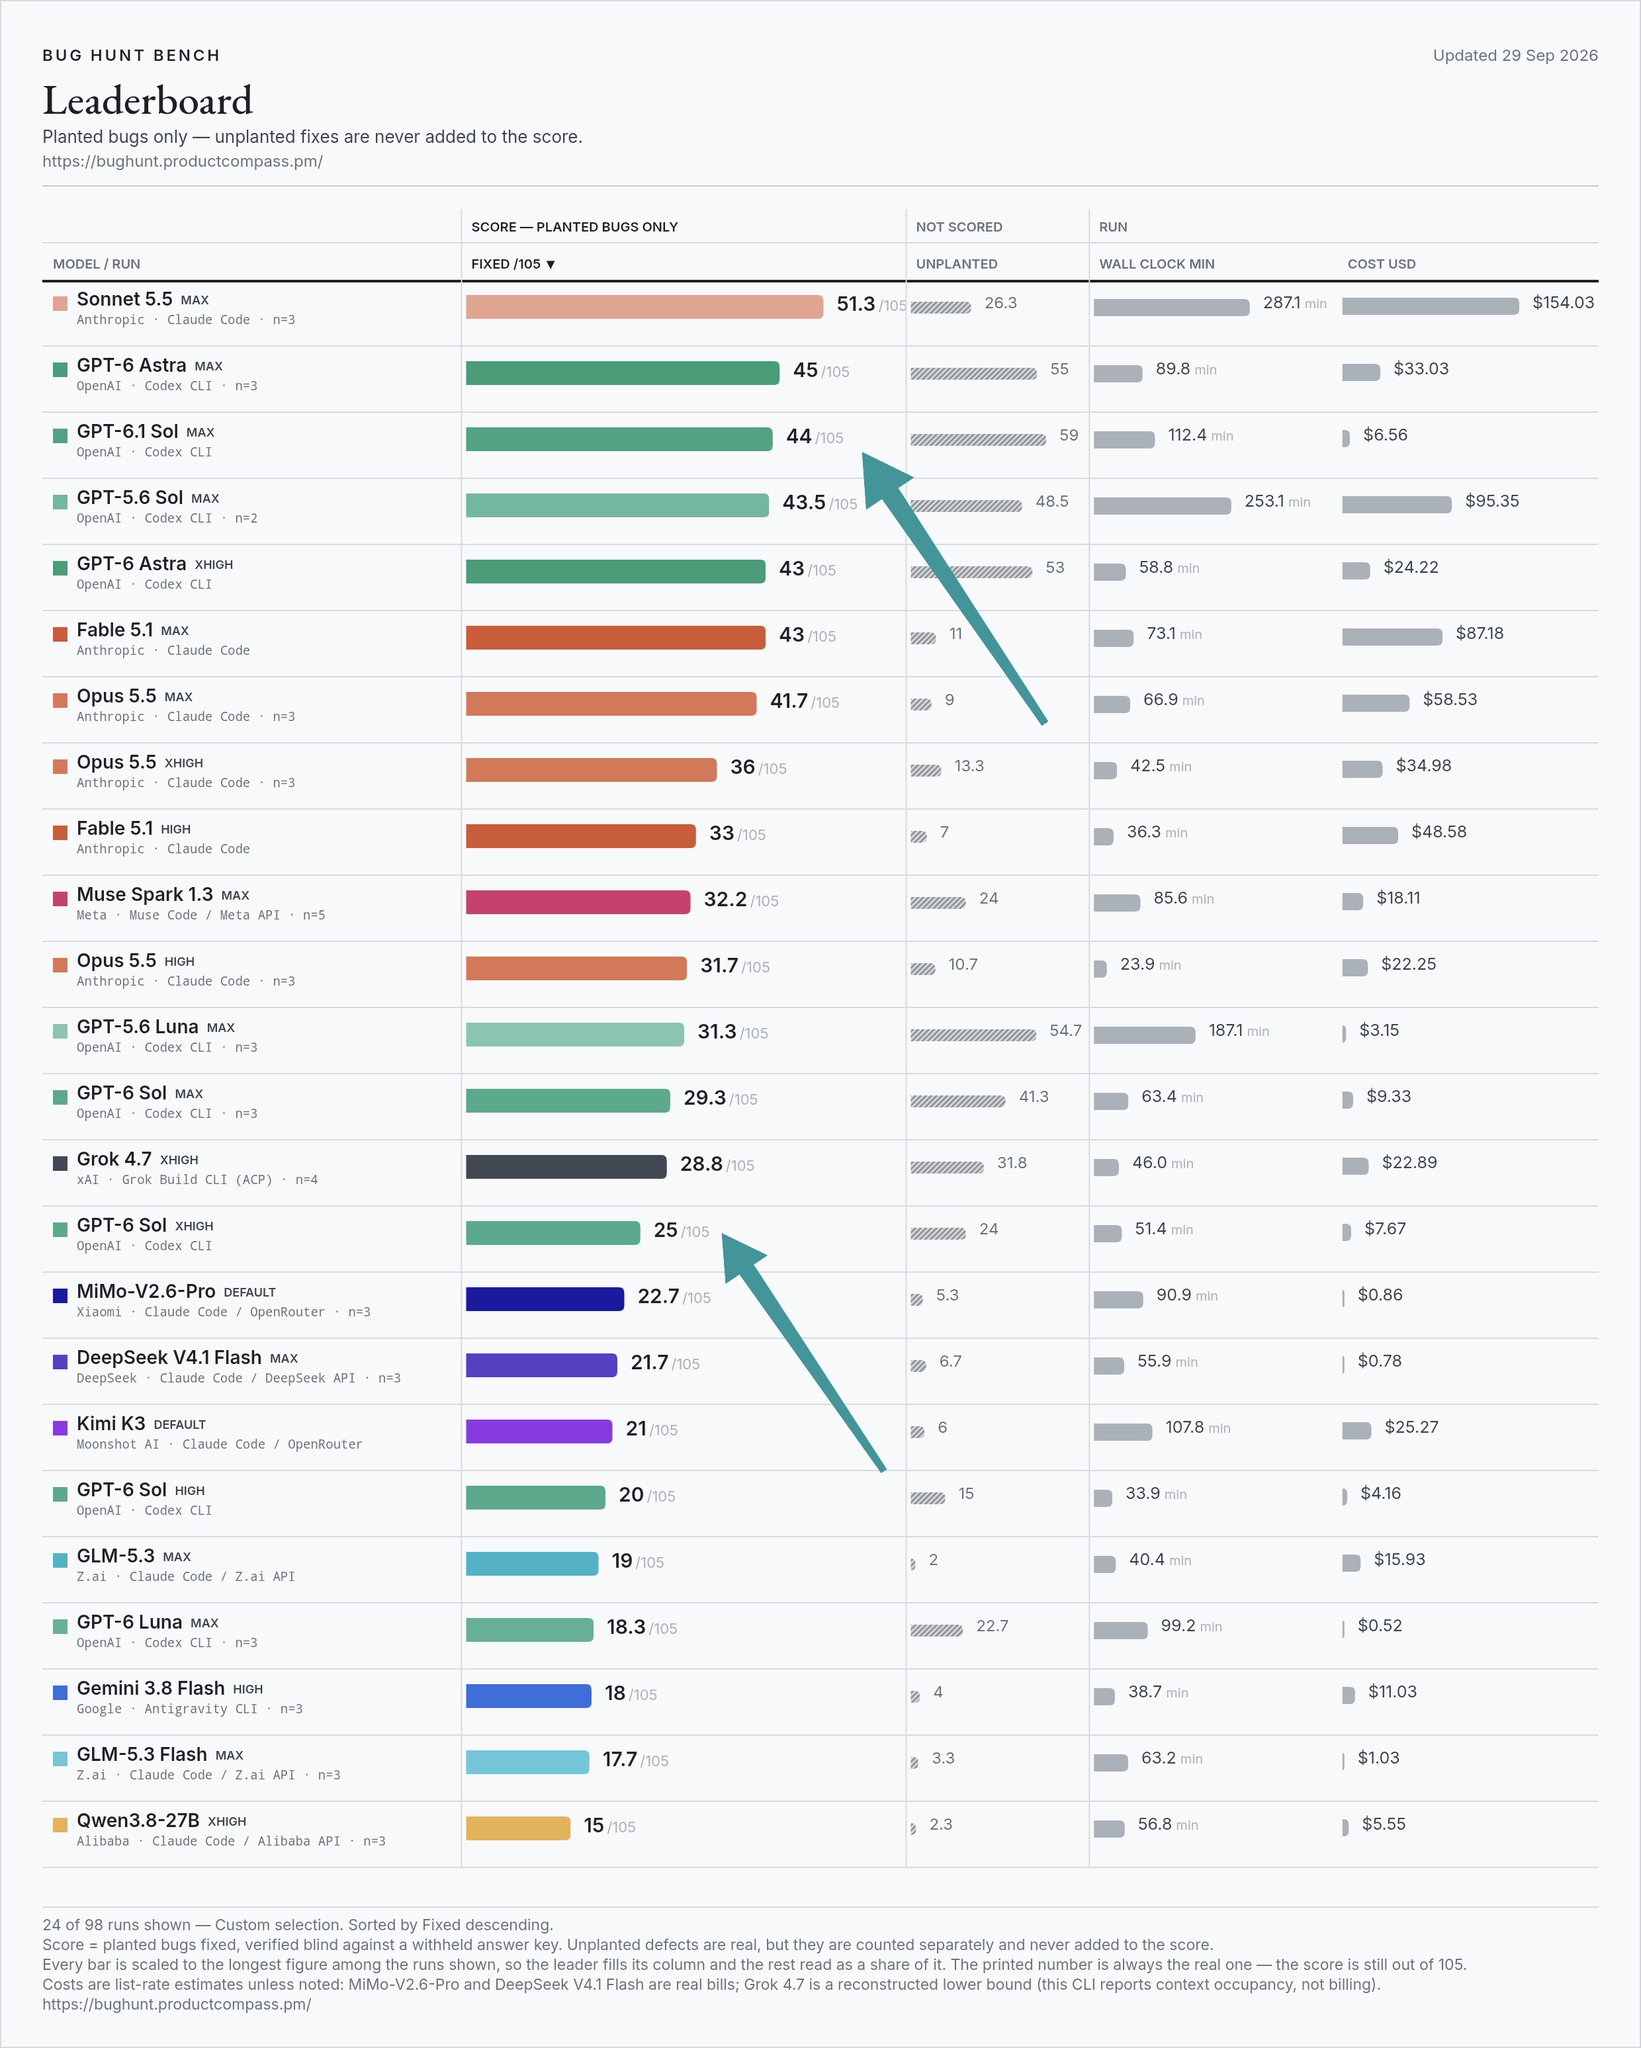
Haven’t looked to closely on this, but comparing output tokens is incorrect Claude models are incredible token inefficient (I.e. for the same task they can take up wards of 3-5x more tokens than 6.1 Sol & Astra) So even if the numbers in your post are correct, you are greeting